


Publish OpenSML-150M release
Browse files- CLEAN_DOWNLOAD_VERIFICATION.json +26 -0
- INFERENCE_VERIFICATION.json +29 -0
- LICENSE +202 -0
- README.md +282 -0
- SHA256SUMS +16 -0
- TECHNICAL_REPORT.md +1356 -0
- TRAINING_RECORDS_MANIFEST.json +847 -0
- TRIAL28_RESULTS.json +262 -0
- checkpoint_provenance.json +38 -0
- config.json +24 -0
- corpus.json +60 -0
- inference.py +36 -0
- manifest.json +31 -0
- native_model.py +278 -0
- native_tokenizer.py +55 -0
- native_utils.py +8 -0
- pretraining-overview.svg +2798 -0
- pretraining-phase-b.svg +2110 -0
- pretraining-sources.svg +0 -0
- report.json +38 -0
- requirements.txt +3 -0
- tokenizer.json +0 -0
- tokenizer_config.json +8 -0
CLEAN_DOWNLOAD_VERIFICATION.json
ADDED
|
@@ -0,0 +1,26 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"repository": "wzebrowski/OpenSML-150M",
|
| 3 |
+
"revision": "27ba9cd101492c0dbfeb6cea0147e429a86d8648",
|
| 4 |
+
"download": "Fresh force-download of 17 release files with no authentication",
|
| 5 |
+
"hashes": "All SHA256SUMS entries verified",
|
| 6 |
+
"working_directory": "/private/tmp (outside original project)",
|
| 7 |
+
"environment": "Separate temporary virtual environment; published requirements installed from PyPI",
|
| 8 |
+
"mlx": "0.32.2",
|
| 9 |
+
"mlx-metal": "0.32.2",
|
| 10 |
+
"tokenizers": "0.22.2",
|
| 11 |
+
"generation": {
|
| 12 |
+
"text": " I am a student.",
|
| 13 |
+
"token_ids": [
|
| 14 |
+
345,
|
| 15 |
+
768,
|
| 16 |
+
261,
|
| 17 |
+
2560,
|
| 18 |
+
17,
|
| 19 |
+
1
|
| 20 |
+
],
|
| 21 |
+
"stop_reason": "eos",
|
| 22 |
+
"prompt_tokens": 13,
|
| 23 |
+
"generated_tokens": 6
|
| 24 |
+
},
|
| 25 |
+
"scope": "Strict loading and short inference test; no benchmark rerun or broad quality claim."
|
| 26 |
+
}
|
INFERENCE_VERIFICATION.json
ADDED
|
@@ -0,0 +1,29 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"model_name": "OpenSML-150M",
|
| 3 |
+
"weights_sha256": "cbd3e3fb4ada74d7264371b79cee7598f513b7b950f1f141ef9f1a43bd2e1b4e",
|
| 4 |
+
"strict_loading": "passed",
|
| 5 |
+
"prompt": "Say hello in one sentence.",
|
| 6 |
+
"generation": {
|
| 7 |
+
"text": " I am a student.",
|
| 8 |
+
"token_ids": [
|
| 9 |
+
345,
|
| 10 |
+
768,
|
| 11 |
+
261,
|
| 12 |
+
2560,
|
| 13 |
+
17,
|
| 14 |
+
1
|
| 15 |
+
],
|
| 16 |
+
"stop_reason": "eos",
|
| 17 |
+
"prompt_tokens": 13,
|
| 18 |
+
"generated_tokens": 6
|
| 19 |
+
},
|
| 20 |
+
"precision": "FP32",
|
| 21 |
+
"attention": "vanilla",
|
| 22 |
+
"ffn": "reference",
|
| 23 |
+
"scope": "Short local loading/generation check; no benchmark rerun or cross-framework parity claim.",
|
| 24 |
+
"parameter_count": 150439168,
|
| 25 |
+
"tested_mlx_runtime": "0.32.3.dev20260920+7241f12",
|
| 26 |
+
"cached_full_prefix_argmax": "matched on checked prompt",
|
| 27 |
+
"context_overflow": "rejected",
|
| 28 |
+
"dependency_scope": "PyPI requirements are a baseline; smoke check used the recorded local development runtime."
|
| 29 |
+
}
|
LICENSE
ADDED
|
@@ -0,0 +1,202 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
|
| 2 |
+
Apache License
|
| 3 |
+
Version 2.0, January 2004
|
| 4 |
+
http://www.apache.org/licenses/
|
| 5 |
+
|
| 6 |
+
TERMS AND CONDITIONS FOR USE, REPRODUCTION, AND DISTRIBUTION
|
| 7 |
+
|
| 8 |
+
1. Definitions.
|
| 9 |
+
|
| 10 |
+
"License" shall mean the terms and conditions for use, reproduction,
|
| 11 |
+
and distribution as defined by Sections 1 through 9 of this document.
|
| 12 |
+
|
| 13 |
+
"Licensor" shall mean the copyright owner or entity authorized by
|
| 14 |
+
the copyright owner that is granting the License.
|
| 15 |
+
|
| 16 |
+
"Legal Entity" shall mean the union of the acting entity and all
|
| 17 |
+
other entities that control, are controlled by, or are under common
|
| 18 |
+
control with that entity. For the purposes of this definition,
|
| 19 |
+
"control" means (i) the power, direct or indirect, to cause the
|
| 20 |
+
direction or management of such entity, whether by contract or
|
| 21 |
+
otherwise, or (ii) ownership of fifty percent (50%) or more of the
|
| 22 |
+
outstanding shares, or (iii) beneficial ownership of such entity.
|
| 23 |
+
|
| 24 |
+
"You" (or "Your") shall mean an individual or Legal Entity
|
| 25 |
+
exercising permissions granted by this License.
|
| 26 |
+
|
| 27 |
+
"Source" form shall mean the preferred form for making modifications,
|
| 28 |
+
including but not limited to software source code, documentation
|
| 29 |
+
source, and configuration files.
|
| 30 |
+
|
| 31 |
+
"Object" form shall mean any form resulting from mechanical
|
| 32 |
+
transformation or translation of a Source form, including but
|
| 33 |
+
not limited to compiled object code, generated documentation,
|
| 34 |
+
and conversions to other media types.
|
| 35 |
+
|
| 36 |
+
"Work" shall mean the work of authorship, whether in Source or
|
| 37 |
+
Object form, made available under the License, as indicated by a
|
| 38 |
+
copyright notice that is included in or attached to the work
|
| 39 |
+
(an example is provided in the Appendix below).
|
| 40 |
+
|
| 41 |
+
"Derivative Works" shall mean any work, whether in Source or Object
|
| 42 |
+
form, that is based on (or derived from) the Work and for which the
|
| 43 |
+
editorial revisions, annotations, elaborations, or other modifications
|
| 44 |
+
represent, as a whole, an original work of authorship. For the purposes
|
| 45 |
+
of this License, Derivative Works shall not include works that remain
|
| 46 |
+
separable from, or merely link (or bind by name) to the interfaces of,
|
| 47 |
+
the Work and Derivative Works thereof.
|
| 48 |
+
|
| 49 |
+
"Contribution" shall mean any work of authorship, including
|
| 50 |
+
the original version of the Work and any modifications or additions
|
| 51 |
+
to that Work or Derivative Works thereof, that is intentionally
|
| 52 |
+
submitted to Licensor for inclusion in the Work by the copyright owner
|
| 53 |
+
or by an individual or Legal Entity authorized to submit on behalf of
|
| 54 |
+
the copyright owner. For the purposes of this definition, "submitted"
|
| 55 |
+
means any form of electronic, verbal, or written communication sent
|
| 56 |
+
to the Licensor or its representatives, including but not limited to
|
| 57 |
+
communication on electronic mailing lists, source code control systems,
|
| 58 |
+
and issue tracking systems that are managed by, or on behalf of, the
|
| 59 |
+
Licensor for the purpose of discussing and improving the Work, but
|
| 60 |
+
excluding communication that is conspicuously marked or otherwise
|
| 61 |
+
designated in writing by the copyright owner as "Not a Contribution."
|
| 62 |
+
|
| 63 |
+
"Contributor" shall mean Licensor and any individual or Legal Entity
|
| 64 |
+
on behalf of whom a Contribution has been received by Licensor and
|
| 65 |
+
subsequently incorporated within the Work.
|
| 66 |
+
|
| 67 |
+
2. Grant of Copyright License. Subject to the terms and conditions of
|
| 68 |
+
this License, each Contributor hereby grants to You a perpetual,
|
| 69 |
+
worldwide, non-exclusive, no-charge, royalty-free, irrevocable
|
| 70 |
+
copyright license to reproduce, prepare Derivative Works of,
|
| 71 |
+
publicly display, publicly perform, sublicense, and distribute the
|
| 72 |
+
Work and such Derivative Works in Source or Object form.
|
| 73 |
+
|
| 74 |
+
3. Grant of Patent License. Subject to the terms and conditions of
|
| 75 |
+
this License, each Contributor hereby grants to You a perpetual,
|
| 76 |
+
worldwide, non-exclusive, no-charge, royalty-free, irrevocable
|
| 77 |
+
(except as stated in this section) patent license to make, have made,
|
| 78 |
+
use, offer to sell, sell, import, and otherwise transfer the Work,
|
| 79 |
+
where such license applies only to those patent claims licensable
|
| 80 |
+
by such Contributor that are necessarily infringed by their
|
| 81 |
+
Contribution(s) alone or by combination of their Contribution(s)
|
| 82 |
+
with the Work to which such Contribution(s) was submitted. If You
|
| 83 |
+
institute patent litigation against any entity (including a
|
| 84 |
+
cross-claim or counterclaim in a lawsuit) alleging that the Work
|
| 85 |
+
or a Contribution incorporated within the Work constitutes direct
|
| 86 |
+
or contributory patent infringement, then any patent licenses
|
| 87 |
+
granted to You under this License for that Work shall terminate
|
| 88 |
+
as of the date such litigation is filed.
|
| 89 |
+
|
| 90 |
+
4. Redistribution. You may reproduce and distribute copies of the
|
| 91 |
+
Work or Derivative Works thereof in any medium, with or without
|
| 92 |
+
modifications, and in Source or Object form, provided that You
|
| 93 |
+
meet the following conditions:
|
| 94 |
+
|
| 95 |
+
(a) You must give any other recipients of the Work or
|
| 96 |
+
Derivative Works a copy of this License; and
|
| 97 |
+
|
| 98 |
+
(b) You must cause any modified files to carry prominent notices
|
| 99 |
+
stating that You changed the files; and
|
| 100 |
+
|
| 101 |
+
(c) You must retain, in the Source form of any Derivative Works
|
| 102 |
+
that You distribute, all copyright, patent, trademark, and
|
| 103 |
+
attribution notices from the Source form of the Work,
|
| 104 |
+
excluding those notices that do not pertain to any part of
|
| 105 |
+
the Derivative Works; and
|
| 106 |
+
|
| 107 |
+
(d) If the Work includes a "NOTICE" text file as part of its
|
| 108 |
+
distribution, then any Derivative Works that You distribute must
|
| 109 |
+
include a readable copy of the attribution notices contained
|
| 110 |
+
within such NOTICE file, excluding those notices that do not
|
| 111 |
+
pertain to any part of the Derivative Works, in at least one
|
| 112 |
+
of the following places: within a NOTICE text file distributed
|
| 113 |
+
as part of the Derivative Works; within the Source form or
|
| 114 |
+
documentation, if provided along with the Derivative Works; or,
|
| 115 |
+
within a display generated by the Derivative Works, if and
|
| 116 |
+
wherever such third-party notices normally appear. The contents
|
| 117 |
+
of the NOTICE file are for informational purposes only and
|
| 118 |
+
do not modify the License. You may add Your own attribution
|
| 119 |
+
notices within Derivative Works that You distribute, alongside
|
| 120 |
+
or as an addendum to the NOTICE text from the Work, provided
|
| 121 |
+
that such additional attribution notices cannot be construed
|
| 122 |
+
as modifying the License.
|
| 123 |
+
|
| 124 |
+
You may add Your own copyright statement to Your modifications and
|
| 125 |
+
may provide additional or different license terms and conditions
|
| 126 |
+
for use, reproduction, or distribution of Your modifications, or
|
| 127 |
+
for any such Derivative Works as a whole, provided Your use,
|
| 128 |
+
reproduction, and distribution of the Work otherwise complies with
|
| 129 |
+
the conditions stated in this License.
|
| 130 |
+
|
| 131 |
+
5. Submission of Contributions. Unless You explicitly state otherwise,
|
| 132 |
+
any Contribution intentionally submitted for inclusion in the Work
|
| 133 |
+
by You to the Licensor shall be under the terms and conditions of
|
| 134 |
+
this License, without any additional terms or conditions.
|
| 135 |
+
Notwithstanding the above, nothing herein shall supersede or modify
|
| 136 |
+
the terms of any separate license agreement you may have executed
|
| 137 |
+
with Licensor regarding such Contributions.
|
| 138 |
+
|
| 139 |
+
6. Trademarks. This License does not grant permission to use the trade
|
| 140 |
+
names, trademarks, service marks, or product names of the Licensor,
|
| 141 |
+
except as required for reasonable and customary use in describing the
|
| 142 |
+
origin of the Work and reproducing the content of the NOTICE file.
|
| 143 |
+
|
| 144 |
+
7. Disclaimer of Warranty. Unless required by applicable law or
|
| 145 |
+
agreed to in writing, Licensor provides the Work (and each
|
| 146 |
+
Contributor provides its Contributions) on an "AS IS" BASIS,
|
| 147 |
+
WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or
|
| 148 |
+
implied, including, without limitation, any warranties or conditions
|
| 149 |
+
of TITLE, NON-INFRINGEMENT, MERCHANTABILITY, or FITNESS FOR A
|
| 150 |
+
PARTICULAR PURPOSE. You are solely responsible for determining the
|
| 151 |
+
appropriateness of using or redistributing the Work and assume any
|
| 152 |
+
risks associated with Your exercise of permissions under this License.
|
| 153 |
+
|
| 154 |
+
8. Limitation of Liability. In no event and under no legal theory,
|
| 155 |
+
whether in tort (including negligence), contract, or otherwise,
|
| 156 |
+
unless required by applicable law (such as deliberate and grossly
|
| 157 |
+
negligent acts) or agreed to in writing, shall any Contributor be
|
| 158 |
+
liable to You for damages, including any direct, indirect, special,
|
| 159 |
+
incidental, or consequential damages of any character arising as a
|
| 160 |
+
result of this License or out of the use or inability to use the
|
| 161 |
+
Work (including but not limited to damages for loss of goodwill,
|
| 162 |
+
work stoppage, computer failure or malfunction, or any and all
|
| 163 |
+
other commercial damages or losses), even if such Contributor
|
| 164 |
+
has been advised of the possibility of such damages.
|
| 165 |
+
|
| 166 |
+
9. Accepting Warranty or Additional Liability. While redistributing
|
| 167 |
+
the Work or Derivative Works thereof, You may choose to offer,
|
| 168 |
+
and charge a fee for, acceptance of support, warranty, indemnity,
|
| 169 |
+
or other liability obligations and/or rights consistent with this
|
| 170 |
+
License. However, in accepting such obligations, You may act only
|
| 171 |
+
on Your own behalf and on Your sole responsibility, not on behalf
|
| 172 |
+
of any other Contributor, and only if You agree to indemnify,
|
| 173 |
+
defend, and hold each Contributor harmless for any liability
|
| 174 |
+
incurred by, or claims asserted against, such Contributor by reason
|
| 175 |
+
of your accepting any such warranty or additional liability.
|
| 176 |
+
|
| 177 |
+
END OF TERMS AND CONDITIONS
|
| 178 |
+
|
| 179 |
+
APPENDIX: How to apply the Apache License to your work.
|
| 180 |
+
|
| 181 |
+
To apply the Apache License to your work, attach the following
|
| 182 |
+
boilerplate notice, with the fields enclosed by brackets "[]"
|
| 183 |
+
replaced with your own identifying information. (Don't include
|
| 184 |
+
the brackets!) The text should be enclosed in the appropriate
|
| 185 |
+
comment syntax for the file format. We also recommend that a
|
| 186 |
+
file or class name and description of purpose be included on the
|
| 187 |
+
same "printed page" as the copyright notice for easier
|
| 188 |
+
identification within third-party archives.
|
| 189 |
+
|
| 190 |
+
Copyright [yyyy] [name of copyright owner]
|
| 191 |
+
|
| 192 |
+
Licensed under the Apache License, Version 2.0 (the "License");
|
| 193 |
+
you may not use this file except in compliance with the License.
|
| 194 |
+
You may obtain a copy of the License at
|
| 195 |
+
|
| 196 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 197 |
+
|
| 198 |
+
Unless required by applicable law or agreed to in writing, software
|
| 199 |
+
distributed under the License is distributed on an "AS IS" BASIS,
|
| 200 |
+
WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
| 201 |
+
See the License for the specific language governing permissions and
|
| 202 |
+
limitations under the License.
|
README.md
ADDED
|
@@ -0,0 +1,282 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
---
|
| 2 |
+
license: apache-2.0
|
| 3 |
+
datasets:
|
| 4 |
+
- HuggingFaceTB/smollm-corpus
|
| 5 |
+
- HuggingFaceTB/dclm-edu
|
| 6 |
+
- HuggingFaceFW/finewiki
|
| 7 |
+
- HuggingFaceTB/smol-smoltalk
|
| 8 |
+
- HuggingFaceH4/ultrachat_200k
|
| 9 |
+
- rajpurkar/squad_v2
|
| 10 |
+
- allenai/ai2_arc
|
| 11 |
+
- databricks/databricks-dolly-15k
|
| 12 |
+
- allenai/tulu-3-sft-personas-instruction-following
|
| 13 |
+
- HuggingFaceTB/smoltalk
|
| 14 |
+
- allenai/sciq
|
| 15 |
+
language:
|
| 16 |
+
- en
|
| 17 |
+
pipeline_tag: text-generation
|
| 18 |
+
tags:
|
| 19 |
+
- text-generation
|
| 20 |
+
- mlx
|
| 21 |
+
- pretraining
|
| 22 |
+
- from-scratch
|
| 23 |
+
- small-language-model
|
| 24 |
+
- post-training
|
| 25 |
+
- silicon
|
| 26 |
+
|
| 27 |
+
---
|
| 28 |
+
|
| 29 |
+
|
| 30 |
+
# OpenSML-150M
|
| 31 |
+
|
| 32 |
+
|
| 33 |
+
**Author:** William Zebrowski · **Checkpoint:** OpenSML-150M Instruct · **Status:** research preview
|
| 34 |
+
|
| 35 |
+
|
| 36 |
+
[Technical report](https://github.com/williamzebrowskI/opensml-150m/blob/main/sml-mlx-v1/docs/TECHNICAL_REPORT.md) · [Results and provenance](TRIAL28_RESULTS.json) · [Tokenizer](tokenizer/tokenizer.json)
|
| 37 |
+
|
| 38 |
+
|
| 39 |
+
An English-first language model trained from scratch with Apple's MLX framework.
|
| 40 |
+
Pretraining processed **7.800B tokens** across Stage A and Stage B on a four-Mac
|
| 41 |
+
cluster, later expanded to five Macs using Thunderbolt RDMA. Three supervised
|
| 42 |
+
fine-tuning stages produced the selected OpenSML-150M checkpoint.
|
| 43 |
+
|
| 44 |
+
|
| 45 |
+
## Availability and Inference
|
| 46 |
+
|
| 47 |
+
|
| 48 |
+
The selected **OpenSML-150M** weights, frozen tokenizer, and standalone native MLX inference code are included. The **OpenSML-150M Instruct** checkpoint contains the selected fine-tuned FP32 weights; optimizer state is excluded. Its training-step identity is retained in the checkpoint provenance.
|
| 49 |
+
|
| 50 |
+
|
| 51 |
+
Use Python 3.11+ on Apple Silicon. Install the Hugging Face CLI first and authenticate if this repository is private:
|
| 52 |
+
|
| 53 |
+
|
| 54 |
+
```bash
|
| 55 |
+
hf download wzebrowski/OpenSML-150M --local-dir ./OpenSML-150M
|
| 56 |
+
cd OpenSML-150M
|
| 57 |
+
python -m pip install -r requirements.txt
|
| 58 |
+
python inference.py --prompt "Say hello in one sentence." --max-new-tokens 32
|
| 59 |
+
```
|
| 60 |
+
|
| 61 |
+
|
| 62 |
+
The CLI verifies the weight hash and tokenizer manifest, then uses greedy FP32 reference MLX inference. Prompts use `User: {prompt}\nAssistant:`; `--raw-completion` skips this wrapper. The 2,048-token context includes the requested generation budget; overflow is rejected. Output includes text, generated token IDs, and the stop reason. Native loading and a short generation were verified locally; this is **not a Transformers AutoModel or mlx-lm loader package**. Other formats and cross-framework parity remain unverified.
|
| 63 |
+
|
| 64 |
+
|
| 65 |
+
See [checkpoint provenance](checkpoint_provenance.json), [loading verification](INFERENCE_VERIFICATION.json), and [bundle hashes](SHA256SUMS).
|
| 66 |
+
|
| 67 |
+
|
| 68 |
+
## Model Specification
|
| 69 |
+
|
| 70 |
+
|
| 71 |
+
| Field | Value |
|
| 72 |
+
| --- | --- |
|
| 73 |
+
| Parameters (model-card label) | 150,439,188 (150.44M) |
|
| 74 |
+
| Layers / hidden width / FFN width | 20 / 768 / 2,048 |
|
| 75 |
+
| Attention | GQA: 12 query heads / 4 KV heads; head dimension 64 |
|
| 76 |
+
| Position encoding | RoPE, base 10,000 |
|
| 77 |
+
| Normalization / MLP | RMSNorm, Q/K normalization, SwiGLU |
|
| 78 |
+
| Vocabulary / context | 32,000 / 2,048 |
|
| 79 |
+
| Embeddings | Tied input and output |
|
| 80 |
+
| Linear biases / dropout | Neither used |
|
| 81 |
+
| Pretraining precision | BF16 compute; FP32 master weights and optimizer state |
|
| 82 |
+
| Benchmark precision | FP32 scoring, explicit vanilla MLX attention |
|
| 83 |
+
|
| 84 |
+
|
| 85 |
+
The independently fitted tokenizer is a 32,000-token byte-level BPE. Its recorded
|
| 86 |
+
held-out audit had zero round-trip failures. Full configuration, parameter
|
| 87 |
+
accounting, and tokenizer checks are in the [technical report](https://github.com/williamzebrowskI/opensml-150m/blob/main/sml-mlx-v1/docs/TECHNICAL_REPORT.md).
|
| 88 |
+
|
| 89 |
+
|
| 90 |
+
## Training and Model Lineage
|
| 91 |
+
|
| 92 |
+
|
| 93 |
+
The selected pretrained base is **Stage B step 73,243**, after **7,800,086,528
|
| 94 |
+
lifetime pretraining tokens**. Stage B continued Stage A with the adjusted mixture below.
|
| 95 |
+
Percentages are configured token shares.
|
| 96 |
+
|
| 97 |
+
|
| 98 |
+
| Source | Initial token share | Stage B token share | Selection |
|
| 99 |
+
| --- | ---: | ---: | --- |
|
| 100 |
+
| [FineWeb-Edu](https://huggingface.co/datasets/HuggingFaceTB/smollm-corpus) | 55% | 55% | `fineweb-edu-dedup` |
|
| 101 |
+
| [DCLM-Edu](https://huggingface.co/datasets/HuggingFaceTB/dclm-edu) | 25% | 20% | `edu_int_score >= 3` |
|
| 102 |
+
| [FineWiki](https://huggingface.co/datasets/HuggingFaceFW/finewiki) | 10% | 15% | English |
|
| 103 |
+
| [Cosmopedia v2](https://huggingface.co/datasets/HuggingFaceTB/smollm-corpus) | 10% | 10% | Textbook/tutorial/blog/educational format filter |
|
| 104 |
+
|
| 105 |
+
|
| 106 |
+
FineWeb-Edu and Cosmopedia v2 come from two subsets of the same SmolLM Corpus
|
| 107 |
+
repository. Pretraining used no dedicated code or math dataset.
|
| 108 |
+
|
| 109 |
+
|
| 110 |
+
```text
|
| 111 |
+
V1 pretrained base → Unified384 → Repair512 → OpenSML-150M (SFT step 768)
|
| 112 |
+
+384 +128 +256 updates
|
| 113 |
+
```
|
| 114 |
+
|
| 115 |
+
|
| 116 |
+
Unified384 used Smol-SmolTalk, UltraChat, SQuAD v2, ARC training questions, and
|
| 117 |
+
locally authored follow-ups. Repair512 added Dolly and Tulu Persona instruction
|
| 118 |
+
examples. The final stage used SmolTalk constraints, SQuAD v2, SciQ, and Repair512
|
| 119 |
+
replay. All model parameters were updated; the selected checkpoint is a direct
|
| 120 |
+
continuation, without LoRA or parameter interpolation. Dataset exposure, source
|
| 121 |
+
pins, optimizer schedules, and checkpoint hashes are in the technical report.
|
| 122 |
+
|
| 123 |
+
|
| 124 |
+
### Pretraining Loss Curves
|
| 125 |
+
|
| 126 |
+
|
| 127 |
+

|
| 128 |
+
|
| 129 |
+
|
| 130 |
+
Recorded held-out loss without smoothing. The star marks the selected base;
|
| 131 |
+
later points are outside its training exposure. The late-training panel uses a
|
| 132 |
+
magnified scale. This chart uses the same original validation set throughout.
|
| 133 |
+
|
| 134 |
+
|
| 135 |
+
<details>
|
| 136 |
+
<summary>Stage B detail and per-source curves</summary>
|
| 137 |
+
|
| 138 |
+
|
| 139 |
+

|
| 140 |
+
|
| 141 |
+
|
| 142 |
+
This panel uses a different, expanded validation set; its absolute losses should
|
| 143 |
+
not be merged with the overview. The selected base has original-set loss
|
| 144 |
+
2.81855024 and expanded-set loss 2.76700753.
|
| 145 |
+
|
| 146 |
+
|
| 147 |
+

|
| 148 |
+
|
| 149 |
+
|
| 150 |
+
Per-source panels use separate vertical scales. Full validation accounting and
|
| 151 |
+
historical measurements are in the technical report.
|
| 152 |
+
|
| 153 |
+
|
| 154 |
+
</details>
|
| 155 |
+
|
| 156 |
+
|
| 157 |
+
## Evaluation
|
| 158 |
+
|
| 159 |
+
|
| 160 |
+
### Zero-shot Likelihood Benchmarks
|
| 161 |
+
|
| 162 |
+
|
| 163 |
+
Existing full-split evaluations cover **15,428 multiple-choice examples**.
|
| 164 |
+
The pretrained base and selected SFT model are reported separately.
|
| 165 |
+
|
| 166 |
+
|
| 167 |
+
| Benchmark | Split | Examples | Pretrained base acc / acc_norm | OpenSML-150M acc / acc_norm |
|
| 168 |
+
| --- | --- | ---: | ---: | ---: |
|
| 169 |
+
| ARC-Easy | Test | 2,376 | 54.67% / 48.53% | 56.65% / 55.43% |
|
| 170 |
+
| ARC-Challenge | Test | 1,172 | 23.38% / 26.88% | 26.02% / 29.52% |
|
| 171 |
+
| PIQA | Validation | 1,838 | 65.23% / 64.36% | 64.53% / 64.09% |
|
| 172 |
+
| HellaSwag | Validation | 10,042 | 30.21% / 34.44% | 30.55% / 33.94% |
|
| 173 |
+
|
| 174 |
+
|
| 175 |
+
SFT improves both ARC metrics. PIQA declines slightly; HellaSwag raw accuracy
|
| 176 |
+
rises slightly while normalized accuracy declines.
|
| 177 |
+
|
| 178 |
+
|
| 179 |
+
<details>
|
| 180 |
+
<summary>Likelihood prompts and scoring</summary>
|
| 181 |
+
|
| 182 |
+
|
| 183 |
+
The native evaluator uses zero-shot raw completion prompts, FP32 scoring,
|
| 184 |
+
reference MLX attention, batch size 1, and no chat template or added BOS/EOS.
|
| 185 |
+
`acc` ranks summed candidate log-likelihood; `acc_norm` divides by candidate
|
| 186 |
+
Unicode character count, excluding the leading delimiter. No generation or LLM
|
| 187 |
+
judge is involved. The evaluator follows pinned harness conventions but is not
|
| 188 |
+
an installed lm-evaluation-harness run. Dataset pins and integrity receipts are
|
| 189 |
+
in the technical report and results record.
|
| 190 |
+
|
| 191 |
+
|
| 192 |
+
</details>
|
| 193 |
+
|
| 194 |
+
|
| 195 |
+
### Comparison with Small Language Models
|
| 196 |
+
|
| 197 |
+
|
| 198 |
+
External scores below are **previously published measurements**. Each cell shows
|
| 199 |
+
`acc / acc_norm`; **—** means not reported in the selected source. Bold marks the
|
| 200 |
+
highest available reported value.
|
| 201 |
+
|
| 202 |
+
|
| 203 |
+
| Model | ARC-Easy acc / acc_norm | ARC-Challenge acc / acc_norm | PIQA acc / acc_norm | HellaSwag acc / acc_norm |
|
| 204 |
+
| --- | ---: | ---: | ---: | ---: |
|
| 205 |
+
| **OpenSML-150M (SFT)** | **56.65% / 55.43%** | **26.02% / 29.52%** | **64.53% / 64.09%** | **30.55% / 33.94%** |
|
| 206 |
+
| [GPT-2 (124M, base)](https://huggingface.co/openai-community/gpt2) | — / 39.48% | — / — | — / 62.51% | 28.92% / 31.14% |
|
| 207 |
+
| [OPT-125M (base)](https://huggingface.co/facebook/opt-125m) | 43.52% / 39.98% | 18.94% / 22.78% | 63.00% / 62.02% | — / — |
|
| 208 |
+
| [Pythia-160M (base)](https://huggingface.co/EleutherAI/pythia-160m) | 43.52% / 39.65% | 18.77% / 23.29% | 62.73% / 61.64% | — / — |
|
| 209 |
+
|
| 210 |
+
|
| 211 |
+
OpenSML's largest reported advantage is normalized ARC-Easy: +15.45 percentage
|
| 212 |
+
points over OPT-125M and +15.78 over Pythia-160M. These are cross-source
|
| 213 |
+
comparisons, not a controlled ranking: prompts, normalization, numerical settings,
|
| 214 |
+
and dataset revisions are not verified identical. OpenSML is SFT-trained; the
|
| 215 |
+
references are base models. Source records are in the technical report.
|
| 216 |
+
|
| 217 |
+
|
| 218 |
+
### Instruction Following: IFEval
|
| 219 |
+
|
| 220 |
+
|
| 221 |
+
| Checkpoint | Prompt strict | Instruction strict | Prompt loose | Instruction loose | 1,280-token cap hits |
|
| 222 |
+
| --- | ---: | ---: | ---: | ---: | ---: |
|
| 223 |
+
| OpenSML-150M | 15.16% (82/541) | 25.30% (211/834) | 15.71% (85/541) | 25.78% (215/834) | 33/541 |
|
| 224 |
+
|
| 225 |
+
|
| 226 |
+
These results apply to OpenSML-150M, not the pretrained base. All 541 prompts and
|
| 227 |
+
834 instructions were scored using programmatic strict/loose verifiers, without
|
| 228 |
+
an LLM judge.
|
| 229 |
+
|
| 230 |
+
|
| 231 |
+
<details>
|
| 232 |
+
<summary>IFEval formatting, generation, and scoring</summary>
|
| 233 |
+
|
| 234 |
+
|
| 235 |
+
Generation is zero-shot and greedy, with plain `User: {prompt}\nAssistant:`
|
| 236 |
+
formatting, no added system message, and a 1,280-new-token cap. The context is
|
| 237 |
+
2,048 tokens; document-end EOS is ID 1. No additional stop strings or repetition
|
| 238 |
+
penalty are used. All responses are scored as produced: 508 stop at EOS and 33
|
| 239 |
+
reach the generation cap; none hit the context limit. The dataset's only split
|
| 240 |
+
is named `train`, but these prompts are evaluation inputs, not supervised records.
|
| 241 |
+
|
| 242 |
+
|
| 243 |
+
</details>
|
| 244 |
+
|
| 245 |
+
|
| 246 |
+
### Complete-answer Diagnostics
|
| 247 |
+
|
| 248 |
+
|
| 249 |
+
Saved development checks report a follow-up joint proxy of 22/32 and named-constraint
|
| 250 |
+
passes on 5/32 public cases. Repetition was detected on 4/63 legacy turns and
|
| 251 |
+
18/73 public-development turns. These are mechanical development proxies;
|
| 252 |
+
a systematic independent review of complete-answer correctness is still pending.
|
| 253 |
+
Likelihood and IFEval do not establish reliable factual answers. No MT-Bench or
|
| 254 |
+
coding-success score is reported for the selected model.
|
| 255 |
+
|
| 256 |
+
|
| 257 |
+
## Intended Use and Limitations
|
| 258 |
+
|
| 259 |
+
|
| 260 |
+
Intended for small-language-model research and controlled experimentation.
|
| 261 |
+
Responses may be incorrect, repetitive, biased, or unsafe. Production use,
|
| 262 |
+
safety behavior, tool use, multilingual ability, and extended dialogue remain
|
| 263 |
+
unvalidated. Benchmark reuse during selection limits evaluation independence;
|
| 264 |
+
a comprehensive contamination audit has not been established.
|
| 265 |
+
|
| 266 |
+
|
| 267 |
+
## Checkpoint Verification
|
| 268 |
+
|
| 269 |
+
|
| 270 |
+
Saved hashes and integrity receipts identify the selected weights and completed
|
| 271 |
+
evaluations. They do not establish cross-framework inference parity. An unchanged native weight export and standalone inference CLI are included.
|
| 272 |
+
The export has a local loading/generation check; a full benchmark rerun of this download bundle has not been performed. See the
|
| 273 |
+
[results and provenance record](TRIAL28_RESULTS.json) and technical report.
|
| 274 |
+
|
| 275 |
+
|
| 276 |
+
## Licensing and Data Provenance
|
| 277 |
+
|
| 278 |
+
|
| 279 |
+
William Zebrowski releases the OpenSML-150M model weights, tokenizer and author-controlled project contributions under [Apache-2.0](LICENSE). Anyone may use, modify, fine-tune and redistribute these contributions for personal, research or commercial purposes, subject to the license terms.
|
| 280 |
+
|
| 281 |
+
This grant covers rights held by the author and does not relicense third-party training materials. Upstream materials retain their own terms, including SQuAD v2 (CC-BY-SA-4.0) and SciQ (CC-BY-NC-3.0). The model license does not grant blanket commercial rights to those datasets.
|
| 282 |
+
|
SHA256SUMS
ADDED
|
@@ -0,0 +1,16 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
6050506f4e9411f7720754591436ec5477ee04d8c136f69dedb5365280d73a2e INFERENCE_VERIFICATION.json
|
| 2 |
+
cfc7749b96f63bd31c3c42b5c471bf756814053e847c10f3eb003417bc523d30 LICENSE
|
| 3 |
+
7edb9a16eaf1ef9232bf5eb3b82dd6a6e5df36fe63108d1525bce00777025bdc README.md
|
| 4 |
+
b5483cebea706f876ff0deddf843e046e0e963ff76e6d97b18d521da03ebeae5 checkpoint_provenance.json
|
| 5 |
+
6d0fc4cb42c9fafb832f57153842bdb71cee5d72678fd2e4cb43b6f3c881604b config.json
|
| 6 |
+
e4c47b7b6aba08f948de7c2c7cb94c58dbd09dde2ded6ac185c60856ee686d27 corpus.json
|
| 7 |
+
f53e9934693d5513a3500c4ba31462b406b4537cf23d37bfc803a962c3b94827 inference.py
|
| 8 |
+
1194292c6d906ac19e6f01c6ad2b42825143fad426a22aa8856d903776701ecb manifest.json
|
| 9 |
+
cbd3e3fb4ada74d7264371b79cee7598f513b7b950f1f141ef9f1a43bd2e1b4e model.safetensors
|
| 10 |
+
1eee6f8afe78767ff6b9c604ccf2328c98b24bc94dbad6291a0ad699dd7345fe native_model.py
|
| 11 |
+
a4b98c7860e40509313e719e3cd235dbf7afa7b81965d217af57416e5ff7c9bb native_tokenizer.py
|
| 12 |
+
2be27ef4bac5f2490b1faaf12e9487eda46356225be220139939459f5105e7af native_utils.py
|
| 13 |
+
e871f690eabebf82da173f0e406f38b79a10cd7d2647bb3592c3fc35ae9a2f16 report.json
|
| 14 |
+
2d5c8eddf30346ebeffdc25fc07552d0e8a9789e967f89e7ff53dc525c7ce569 requirements.txt
|
| 15 |
+
e095f0413a11fa91fbb58f37d00e4c6bcda59beb89b28f6f680db1436a7e8891 tokenizer.json
|
| 16 |
+
619f500553367eb76f5be00a98625130ec857b9c367561334984096c029ba2a9 tokenizer_config.json
|
TECHNICAL_REPORT.md
ADDED
|
@@ -0,0 +1,1356 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# OpenSML-150M — Technical Report
|
| 2 |
+
|
| 3 |
+
William Zebrowski · V2 training and selected post-training checkpoint · Updated October 2, 2026
|
| 4 |
+
|
| 5 |
+
This report is the detailed companion to the OpenSML-150M model card. The current
|
| 6 |
+
record below covers the V2 base at Stage B step 73,243 (7,800,086,528 pretraining
|
| 7 |
+
tokens) and the selected SFT checkpoint at total step 768. The September 18
|
| 8 |
+
report is preserved in a clearly dated historical appendix; its training status,
|
| 9 |
+
hardware, and unfinished-evaluation statements describe that earlier boundary.
|
| 10 |
+
Current selection and release statements below take precedence.
|
| 11 |
+
|
| 12 |
+
## Parameter-count accounting note
|
| 13 |
+
|
| 14 |
+
The owner-requested model-card wording reports 150,439,188 parameters (150.44M).
|
| 15 |
+
The existing architecture accounting and configuration records total 150,439,168.
|
| 16 |
+
This 20-parameter discrepancy is unresolved; the presentation edit was not a
|
| 17 |
+
model-weight change. The original component accounting is preserved in the
|
| 18 |
+
historical appendix.
|
| 19 |
+
|
| 20 |
+
## Current V2 Training and Evaluation Record
|
| 21 |
+
|
| 22 |
+
## Availability and Inference
|
| 23 |
+
|
| 24 |
+
This repository currently documents the selected fine-tuned model and its pretrained
|
| 25 |
+
base, and provides their shared tokenizer
|
| 26 |
+
and historical configuration files. It does not provide model weights or a tested
|
| 27 |
+
standalone inference bundle. A download-and-generate quick start is therefore not
|
| 28 |
+
yet available. The local project uses native MLX inference on Apple hardware;
|
| 29 |
+
compatibility with Transformers AutoModel, GGUF, ONNX, vLLM, and llama.cpp has not
|
| 30 |
+
been established for this repository. The selected SFT checkpoint uses the native plain User/Assistant format described
|
| 31 |
+
below; the pretrained base remains a completion model.
|
| 32 |
+
|
| 33 |
+
## At a Glance
|
| 34 |
+
|
| 35 |
+
| Item | Configuration |
|
| 36 |
+
| --- | --- |
|
| 37 |
+
| Model type | Decoder-only language model; selected instruction-tuned checkpoint with base results separately reported |
|
| 38 |
+
| Initialization | Random weights; no pretrained model initialization |
|
| 39 |
+
| Parameters | 150,439,168 |
|
| 40 |
+
| Backbone | 20 layers, width 768 |
|
| 41 |
+
| Context | 2,048 tokens |
|
| 42 |
+
| Tokenizer | Independently trained 32,000-token byte-level BPE |
|
| 43 |
+
| Training framework | MLX, with custom training and cluster orchestration |
|
| 44 |
+
| Five-Mac cluster | One M5 Ultra, one M3 Ultra, and three M4 Max machines |
|
| 45 |
+
| Communication | Native JACCL over Thunderbolt RDMA; four-node ring initially, five-node continuation |
|
| 46 |
+
| Selected pretrained base | Step 73,243; 7,800,086,528 lifetime pretraining tokens |
|
| 47 |
+
| Original exposure target | 15B total tokens; a plan, not the completed exposure of the selected base |
|
| 48 |
+
| Selected fine-tuned model | OpenSML-150M; total SFT step 768 |
|
| 49 |
+
| Current status | Base and selected SFT checkpoint documented; weight release pending |
|
| 50 |
+
|
| 51 |
+
## Model Specification
|
| 52 |
+
|
| 53 |
+
| Field | Value |
|
| 54 |
+
| --- | --- |
|
| 55 |
+
| Unique parameters | 150,439,168 |
|
| 56 |
+
| Layers / hidden width / FFN width | 20 / 768 / 2,048 |
|
| 57 |
+
| Attention | GQA: 12 query heads / 4 KV heads; head dimension 64 |
|
| 58 |
+
| Position encoding | RoPE, base 10,000 |
|
| 59 |
+
| Normalization / MLP | RMSNorm, Q/K normalization, SwiGLU |
|
| 60 |
+
| Vocabulary / context | 32,000 / 2,048 |
|
| 61 |
+
| Embeddings | Tied input and output |
|
| 62 |
+
| Linear biases / dropout | Neither used |
|
| 63 |
+
| Pretraining precision | BF16 compute; FP32 master weights and optimizer state |
|
| 64 |
+
| Benchmark precision | FP32 scoring, explicit vanilla MLX attention |
|
| 65 |
+
|
| 66 |
+
### Architecture
|
| 67 |
+
|
| 68 |
+
The model uses grouped-query attention with 12 query heads and 4 key/value heads
|
| 69 |
+
(head dimension 64), rotary position embeddings with base 10,000, RMSNorm, Q/K
|
| 70 |
+
normalization, and SwiGLU feed-forward layers with intermediate width 2,048.
|
| 71 |
+
Input and output embeddings are tied; linear layers are bias-free.
|
| 72 |
+
|
| 73 |
+
The tied vocabulary matrix contains 24,576,000 parameters. Initialization uses
|
| 74 |
+
normal standard deviation 0.02 with residual output projections scaled by
|
| 75 |
+
1/sqrt(2L). These are established Transformer components in our configuration,
|
| 76 |
+
not a claim of a new attention architecture.
|
| 77 |
+
|
| 78 |
+
## Pretraining Data
|
| 79 |
+
|
| 80 |
+
The model uses a prose-first mixture streamed from Hugging Face. This replaces
|
| 81 |
+
the earlier OpenWebText description on this page; that description does not apply
|
| 82 |
+
to OpenSML-150M.
|
| 83 |
+
|
| 84 |
+
| Source | Initial token share | Stage B token share | Selection |
|
| 85 |
+
| --- | ---: | ---: | --- |
|
| 86 |
+
| [FineWeb-Edu](https://huggingface.co/datasets/HuggingFaceTB/smollm-corpus) | 55% | 55% | `fineweb-edu-dedup` |
|
| 87 |
+
| [DCLM-Edu](https://huggingface.co/datasets/HuggingFaceTB/dclm-edu) | 25% | 20% | `edu_int_score >= 3` |
|
| 88 |
+
| [FineWiki](https://huggingface.co/datasets/HuggingFaceFW/finewiki) | 10% | 15% | English |
|
| 89 |
+
| [Cosmopedia v2](https://huggingface.co/datasets/HuggingFaceTB/smollm-corpus) | 10% | 10% | Textbook/tutorial/blog/educational format filter |
|
| 90 |
+
|
| 91 |
+
The [original corpus recipe](https://huggingface.co/wzebrowski/OpenSML-150M/blob/main/configs/corpus.json) records the initial mixture.
|
| 92 |
+
Stage B began at step 73,008, after 7,775,059,968 tokens, and changed the mixture
|
| 93 |
+
as shown above. No dedicated code or math source was included in this prose
|
| 94 |
+
pretraining mixture; prose can still contain technical material, equations,
|
| 95 |
+
and code.
|
| 96 |
+
|
| 97 |
+
Pretraining uses three dataset repositories: FineWeb-Edu and Cosmopedia
|
| 98 |
+
v2 are two distinct subsets of SmolLM Corpus. All four pretraining sources are
|
| 99 |
+
listed above. Dataset tags also include the public sources used across the
|
| 100 |
+
selected checkpoint's SFT lineage, described below.
|
| 101 |
+
|
| 102 |
+
Normalized document hashes assign 97% to training and 1% each to tokenizer
|
| 103 |
+
development, validation, and a reserved final split. Original text is preserved
|
| 104 |
+
for model input. A bounded window of 10,000 recent accepted hashes suppresses
|
| 105 |
+
nearby exact duplicates across sources; it is not complete corpus deduplication
|
| 106 |
+
or a benchmark contamination audit.
|
| 107 |
+
|
| 108 |
+
Early training read each source in dataset order without a document shuffle
|
| 109 |
+
buffer. From step 70,710 (7,530,332,160 tokens), the data-review continuation
|
| 110 |
+
introduced a resumable 256-document shuffle buffer per source. This is bounded
|
| 111 |
+
shuffling, not a global random permutation. Documents receive one explicit EOS
|
| 112 |
+
and are packed into causal windows that can cross document boundaries;
|
| 113 |
+
attention is not reset at every document.
|
| 114 |
+
|
| 115 |
+
Mac-1 handles filtering, tokenization, and RAM prefetch, then distributes disjoint
|
| 116 |
+
rank slices. The training path does not save corpus/token shards to disk.
|
| 117 |
+
Checkpoint cursors, tokenizer-fitting samples, logs, staged files, and small HF
|
| 118 |
+
metadata caches are separate storage uses. Exact-resume state tracks consumed
|
| 119 |
+
batches, not the prefetch worker's advanced position.
|
| 120 |
+
|
| 121 |
+
## Tokenizer
|
| 122 |
+
|
| 123 |
+
**ByteBPE32K v1 is completed and frozen.** It was fitted on our source mixture,
|
| 124 |
+
not borrowed from another model. Tokenizer-fitting shares are measured in UTF-8
|
| 125 |
+
bytes; pretraining shares are measured in tokens.
|
| 126 |
+
|
| 127 |
+
| Audit item | Recorded result |
|
| 128 |
+
| --- | --- |
|
| 129 |
+
| Fitting sample | 500,048,186 UTF-8 bytes; 113,898 documents |
|
| 130 |
+
| Held-out audit | 4,010,605 bytes; 970 documents |
|
| 131 |
+
| Vocabulary | Exactly 32,000 IDs including structural tokens |
|
| 132 |
+
| Round-trip failures | Zero across the held-out audit |
|
| 133 |
+
| Regression fixtures | 9 passed |
|
| 134 |
+
| Special IDs | Padding 0; document-end 1; turn-start 2; turn-end 3 |
|
| 135 |
+
| Encoding | Full byte alphabet; no text normalization or implicit BOS/EOS |
|
| 136 |
+
|
| 137 |
+
Literal control-token spellings encode as ordinary text. Reserved turn tokens
|
| 138 |
+
do not mean the base model has been chat-trained. The selected SFT model uses
|
| 139 |
+
plain role labels and document-end EOS rather than relying on those reserved turn tokens. Held-out bytes/token were
|
| 140 |
+
4.6255 for web, 4.4532 for DCLM, 4.0593 for wiki, and 5.0610 for Cosmopedia.
|
| 141 |
+
These are encoding checks, not model capability results.
|
| 142 |
+
|
| 143 |
+
Files: [tokenizer](https://huggingface.co/wzebrowski/OpenSML-150M/blob/main/tokenizer/tokenizer.json),
|
| 144 |
+
[configuration](https://huggingface.co/wzebrowski/OpenSML-150M/blob/main/tokenizer/tokenizer_config.json),
|
| 145 |
+
[manifest](https://huggingface.co/wzebrowski/OpenSML-150M/blob/main/tokenizer/manifest.json), and [audit](https://huggingface.co/wzebrowski/OpenSML-150M/blob/main/tokenizer/report.json).
|
| 146 |
+
The artifact is provided with its structural-token contract; standard text
|
| 147 |
+
encoding alone does not reproduce every custom trainer boundary rule.
|
| 148 |
+
|
| 149 |
+
```text
|
| 150 |
+
Tokenizer artifact fingerprint:
|
| 151 |
+
1194292c6d906ac19e6f01c6ad2b42825143fad426a22aa8856d903776701ecb
|
| 152 |
+
```
|
| 153 |
+
|
| 154 |
+
## Training Method
|
| 155 |
+
|
| 156 |
+
| Setting | Value |
|
| 157 |
+
| --- | --- |
|
| 158 |
+
| Optimizer | AdamW; betas 0.9/0.95; epsilon 1e-8 |
|
| 159 |
+
| Precision | BF16 compute; FP32 master weights, moments, and accumulated/reduced gradients |
|
| 160 |
+
| Regularization | Matrix weight decay 0.1; gradient norm clip 1.0 |
|
| 161 |
+
| Local microbatches | Initially 4 / 3 / 3 / 3; five-Mac continuation 4 / 3 / 2 / 2 / 2 sequences |
|
| 162 |
+
| Gradient accumulation | 4 |
|
| 163 |
+
| Global update | 52 sequences; 106,496 tokens |
|
| 164 |
+
| Learning rate | Initial peak 3e-4; later validation-plateau schedule, then 5e-6 floor; selected Stage B base used 5e-6 |
|
| 165 |
+
| Validation / samples | Every 25M / 50M tokens |
|
| 166 |
+
| Routine checkpoint saves | Every 10M tokens, plus best/final/clean-stop saves |
|
| 167 |
+
|
| 168 |
+
### Four-to-five-Mac training history
|
| 169 |
+
|
| 170 |
+
The original cluster used one M3 Ultra and three M4 Max Mac Studios. At step
|
| 171 |
+
**50,096**, after **5,335,023,616 tokens**, training continued with an M5 Ultra
|
| 172 |
+
coordinator added to form a five-Mac ring. This transition is recorded in the
|
| 173 |
+
selected pretrained checkpoint's provenance; the model was not trained on
|
| 174 |
+
five Macs from initialization.
|
| 175 |
+
|
| 176 |
+
| Machine | Unified memory | Local microbatch | Tokens per global update |
|
| 177 |
+
| --- | ---: | ---: | ---: |
|
| 178 |
+
| M5 Ultra | 96 GB | 4 | 32,768 |
|
| 179 |
+
| M3 Ultra | 96 GB | 3 | 24,576 |
|
| 180 |
+
| M4 Max | 36 GB | 2 | 16,384 |
|
| 181 |
+
| M4 Max | 36 GB | 2 | 16,384 |
|
| 182 |
+
| M4 Max | 36 GB | 2 | 16,384 |
|
| 183 |
+
|
| 184 |
+
The physical ring is **Mac-1 → Mac-2 → Mac-3 → Mac-5 → Mac-4 → Mac-1**.
|
| 185 |
+
This is replicated data parallelism: each Mac holds the complete model and
|
| 186 |
+
optimizer, processes disjoint examples, combines gradients with batch-size
|
| 187 |
+
weighting, and applies the same update. It is not a model split across five
|
| 188 |
+
machines. Mac-1 streams/tokenizes the corpus, distributes batches, evaluates,
|
| 189 |
+
and saves checkpoints.
|
| 190 |
+
|
| 191 |
+
Native JACCL over Thunderbolt RDMA carries tensors. Ethernet/SSH and
|
| 192 |
+
job-scoped coordinator tunnels handle control traffic. With context 2,048 and
|
| 193 |
+
four accumulation steps, the five-Mac allocation preserves the earlier effective
|
| 194 |
+
batch: `(4 + 3 + 2 + 2 + 2) × 4 × 2048 = 106,496` tokens per update.
|
| 195 |
+
The transition preserves architecture, tokenizer and optimizer state. No
|
| 196 |
+
controlled four-versus-five-Mac throughput comparison is claimed.
|
| 197 |
+
|
| 198 |
+
The implementation uses compiled backward computation, fast attention, custom
|
| 199 |
+
Metal cross-entropy, and packed SwiGLU. Their presence is not, by itself, evidence
|
| 200 |
+
of a measured speedup for each individual optimization.
|
| 201 |
+
|
| 202 |
+
### Pilot and Continuation
|
| 203 |
+
|
| 204 |
+
The pilot finished at step 4,696 after 500,105,216 tokens. It used token-based
|
| 205 |
+
warmup, a stable phase, and a final cosine decay to 3e-5. The initial continuation restored
|
| 206 |
+
its weights, optimizer and consumed data cursor, reheated to 3e-4 over 50M
|
| 207 |
+
additional tokens, and originally targeted 15B total tokens. Later training
|
| 208 |
+
changed schedules through explicit checkpoint transitions: a validation-plateau
|
| 209 |
+
controller at step 38,056; a lower-LR continuation at step 60,263; and the
|
| 210 |
+
shuffle/validation transition at step 70,710. Stage B began from step 73,008
|
| 211 |
+
at 5e-6. The selected Stage B base is step **73,243**, with **7,800,086,528**
|
| 212 |
+
lifetime pretraining tokens.
|
| 213 |
+
|
| 214 |
+
This is **not a single unchanged 15B schedule from initialization**, and the
|
| 215 |
+
15B target must not be read as the training exposure of these checkpoints.
|
| 216 |
+
The linked [pilot](https://huggingface.co/wzebrowski/OpenSML-150M/blob/main/configs/pilot.json) and [early continuation configuration](https://huggingface.co/wzebrowski/OpenSML-150M/blob/main/configs/training_recipe.json)
|
| 217 |
+
are historical recipes; the later transitions are summarized here.
|
| 218 |
+
|
| 219 |
+
## Training and Model Lineage
|
| 220 |
+
|
| 221 |
+
The selected fine-tuned model is **OpenSML-150M**, retained by the
|
| 222 |
+
project owner as the current baseline. Its internal experiment identifier is
|
| 223 |
+
Trial 28 — Repair512 +256; that identifier remains in provenance records only. Its ancestry is:
|
| 224 |
+
|
| 225 |
+
```text
|
| 226 |
+
Pretrained V2: Stage B step 73,243 (7.800B pretraining tokens)
|
| 227 |
+
→ Unified384: 384 supervised updates from the base
|
| 228 |
+
→ Repair512: 128 additional public-repair updates
|
| 229 |
+
→ OpenSML-150M: 256 additional updates; total SFT step 768
|
| 230 |
+
```
|
| 231 |
+
|
| 232 |
+
These SFT labels are update counts, not pretraining steps or token counts.
|
| 233 |
+
This step 768 is distinct from the earlier Text Follow-up 768 branch. The model
|
| 234 |
+
is a direct fine-tuned checkpoint, without parameter interpolation. Other search
|
| 235 |
+
candidates are separate experiments and are not ancestors of these weights.
|
| 236 |
+
|
| 237 |
+
### Fine-tuning Data and Settings
|
| 238 |
+
|
| 239 |
+
| Stage | Data and method | Retained exposure |
|
| 240 |
+
| --- | --- | --- |
|
| 241 |
+
| Unified384 | Smol-SmolTalk and UltraChat conversations, writing/summarization, authored recovery/format follow-ups, SQuAD v2 passage reading, and ARC training questions; assistant-only supervised learning | First 384 updates of the 768-update recipe |
|
| 242 |
+
| Repair512 | Short Smol-SmolTalk/UltraChat chats, Dolly ordinary and grounded answers, and verified Tulu 3 Persona instruction examples; assistant-only supervised learning | 128 additional updates from Unified384 |
|
| 243 |
+
| OpenSML-150M | SmolTalk constraints, SQuAD v2 training passages, SciQ training labels, and Repair512 replay; supervised learning with repetition and retention objectives | 256 additional updates; first 4,096 ordered training records |
|
| 244 |
+
|
| 245 |
+
Trial 28 prepared an 8,192-record, 512-update experiment. Its retained checkpoint
|
| 246 |
+
is the **+256 midpoint**, not the final +512 model. The full prepared mixture was
|
| 247 |
+
3,072 SmolTalk constraint records, 2,048 SQuAD records, 1,024 SciQ records, and
|
| 248 |
+
2,048 replay records, including repeated passes through fresh examples. Those
|
| 249 |
+
full-plan counts must not be interpreted as the retained midpoint's exposure.
|
| 250 |
+
|
| 251 |
+
Trial 28 updates all model parameters, including tied embeddings; no LoRA or
|
| 252 |
+
frozen-layer restriction is used. It retains the architecture, context length,
|
| 253 |
+
and tokenizer of the base. Batches contain 16 whole conversations. Supervised
|
| 254 |
+
cross-entropy weights conversations equally and trains assistant targets plus
|
| 255 |
+
EOS while masking prompt/history positions. Targets are retained whole; records
|
| 256 |
+
that exceed length/context limits are excluded.
|
| 257 |
+
|
| 258 |
+
The Trial 28 optimizer uses AdamW, betas 0.9/0.95, zero weight decay, clipping at
|
| 259 |
+
norm 1, and a 16-update warmup to 2e-6 followed by cosine decay toward 2e-7 over
|
| 260 |
+
the planned 512 updates. The selected midpoint therefore stops partway through
|
| 261 |
+
that schedule. The objective adds a selective repetition unlikelihood term
|
| 262 |
+
(weight 0.3) and a frozen-Repair512 forward-KL retention term (weight 2), restricted
|
| 263 |
+
to replay examples. This is supervised post-training with auxiliary objectives;
|
| 264 |
+
it does not use DPO or a reward-model policy-optimization stage in this lineage.
|
| 265 |
+
|
| 266 |
+
Trial 28 source revisions are SmolTalk `5feaf2fd3ffca7c237fc38d1861bc30365d48ffa`,
|
| 267 |
+
SQuAD v2 `3ffb306f725f7d2ce8394bc1873b24868140c412`, and SciQ
|
| 268 |
+
`2c94ad3e1aafab77146f384e23536f97a4849815`.
|
| 269 |
+
Training preparation excludes known benchmark overlaps and separates development
|
| 270 |
+
and reserved records, but this is not a comprehensive contamination audit.
|
| 271 |
+
Public targets have not all received independent factual review.
|
| 272 |
+
|
| 273 |
+
Selection followed repeated development and public-benchmark comparisons.
|
| 274 |
+
Trial 28 passed the recorded benchmark gate but failed the chat-repetition
|
| 275 |
+
component of the development gate; the owner explicitly retained it. It is the
|
| 276 |
+
**selected current baseline**, not a statistically established best model across
|
| 277 |
+
all capabilities. Reused benchmarks are exploratory development evidence.
|
| 278 |
+
|
| 279 |
+
## Pretraining Loss Curves
|
| 280 |
+
|
| 281 |
+
These charts show recorded held-out next-token validation loss from the selected
|
| 282 |
+
pretraining lineage, without smoothing. **Blue is Phase A** (the initial mixture
|
| 283 |
+
and its continuations); **teal is Phase B** (the Stage B prose refinement).
|
| 284 |
+
Phase B starts at step **73,008**, after **7.775B tokens**. The star marks the
|
| 285 |
+
selected pretrained base at step **73,243**, after **7.800B tokens**. Later points
|
| 286 |
+
show continued pretraining beyond the selected checkpoint, not additional
|
| 287 |
+
training included in that checkpoint. Lower loss is better.
|
| 288 |
+
|
| 289 |
+
### Full History and Late-training Zoom
|
| 290 |
+
|
| 291 |
+
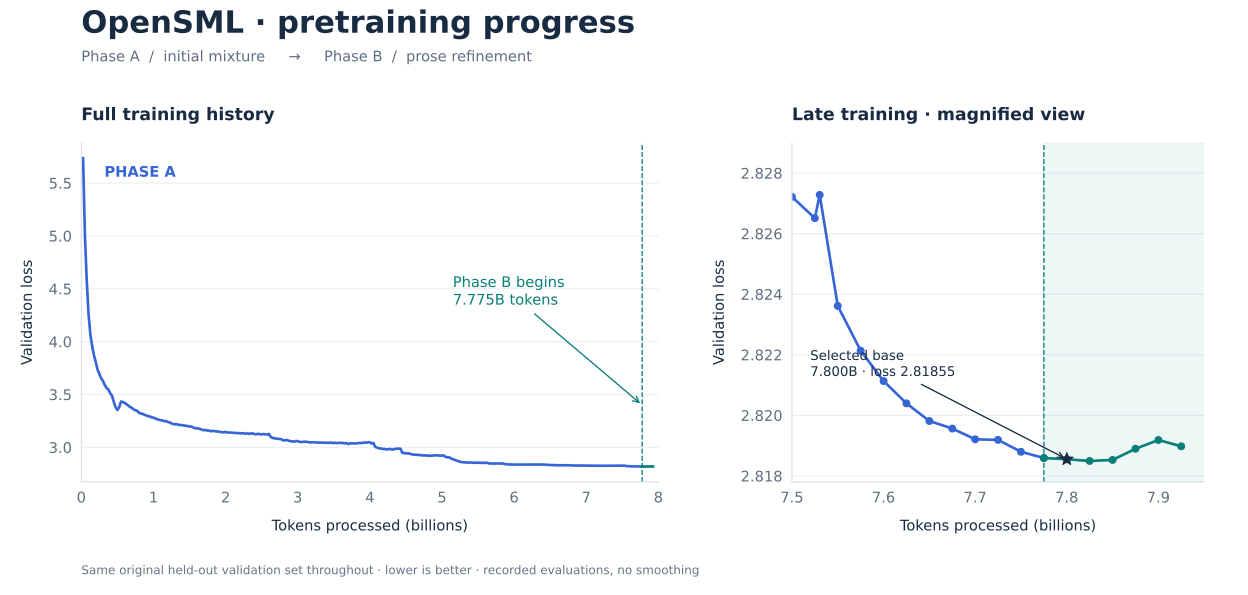
|
| 292 |
+
|
| 293 |
+
The overview and zoom use the **same original held-out set** throughout
|
| 294 |
+
(262,144 target positions). The zoom makes the shorter Phase B visible; its
|
| 295 |
+
vertical scale is magnified. Aggregate validation weights remain fixed at
|
| 296 |
+
55% web, 25% DCLM, 10% Wikipedia, and 10% Cosmopedia across both phases,
|
| 297 |
+
even though the Phase B training mixture changes. The selected checkpoint's
|
| 298 |
+
loss on this original set is **2.81855024**.
|
| 299 |
+
|
| 300 |
+
### Phase B Detail
|
| 301 |
+
|
| 302 |
+
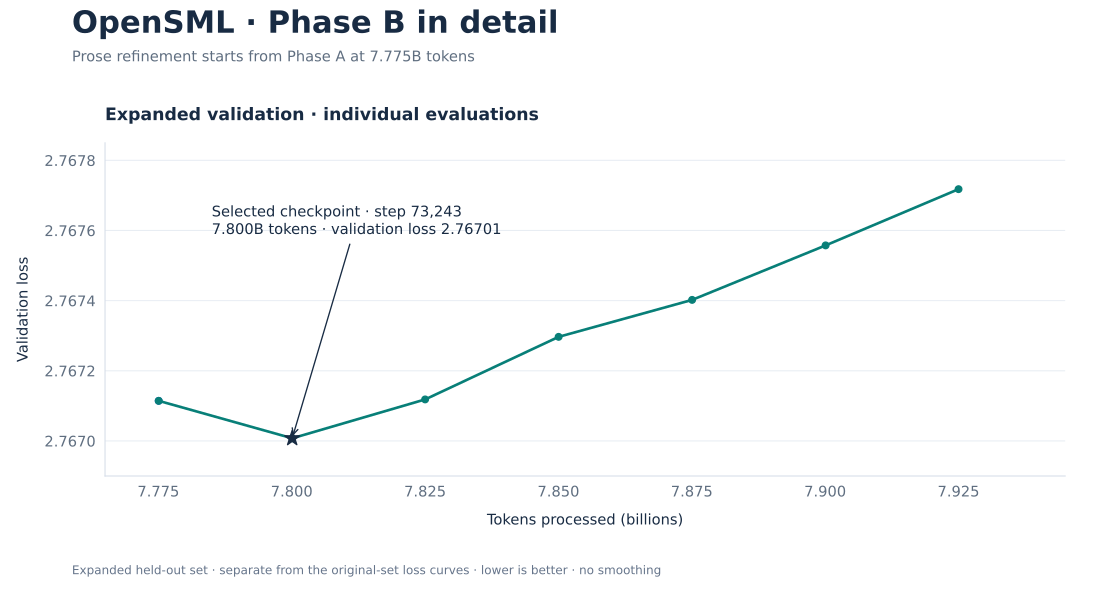
|
| 303 |
+
|
| 304 |
+
This close-up uses the **expanded held-out set** (4,194,304 target positions),
|
| 305 |
+
introduced late in Phase A. Its absolute loss values are separate from the
|
| 306 |
+
original-set curves above and below. The selected checkpoint's expanded loss
|
| 307 |
+
is **2.76700753**. The tightly zoomed vertical scale shows small changes; the
|
| 308 |
+
later increase is less than 0.001 loss. Validation weights remain fixed to the
|
| 309 |
+
original reference mixture.
|
| 310 |
+
|
| 311 |
+
### Validation Loss by Data Source
|
| 312 |
+
|
| 313 |
+
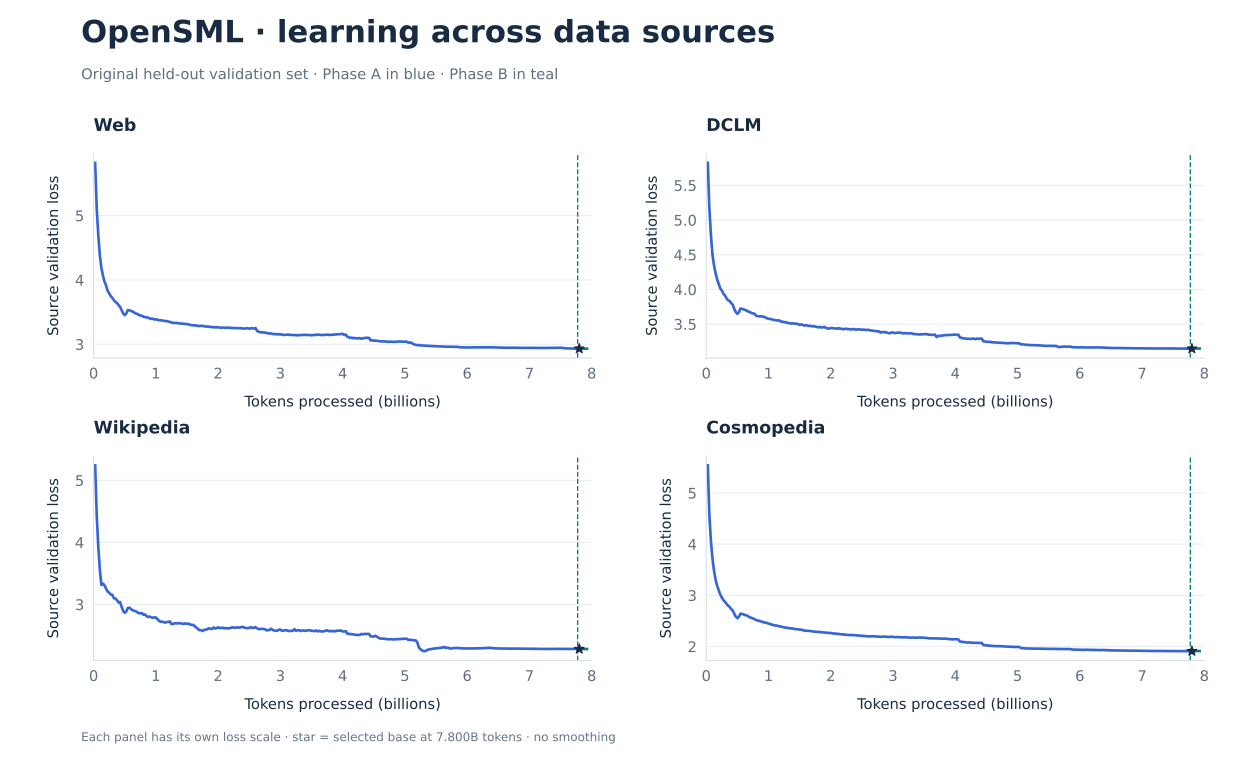
|
| 314 |
+
|
| 315 |
+
Each source is evaluated on the original held-out set throughout. Panels use
|
| 316 |
+
their own vertical scales; they show each source's trajectory rather than a
|
| 317 |
+
common-scale ranking of source difficulty. The dashed line marks the Phase B
|
| 318 |
+
transition and the star marks the selected base.
|
| 319 |
+
|
| 320 |
+
## Interim Results
|
| 321 |
+
|
| 322 |
+
**Dated snapshot: September 18, 2026, through step 8,217. Not a live counter.**
|
| 323 |
+
|
| 324 |
+
| Selected milestone | Total tokens | Validation loss |
|
| 325 |
+
| --- | ---: | ---: |
|
| 326 |
+
| Pilot endpoint, step 4,696 | 500,105,216 | 3.3536 |
|
| 327 |
+
| Near end of continuation rewarm, step 5,165 | 550,051,840 | 3.4327 |
|
| 328 |
+
| Best at this snapshot, step 8,217 | 875,077,632 | 3.3078 |
|
| 329 |
+
|
| 330 |
+
These are selected milestones, not a complete learning curve. The loss rise and
|
| 331 |
+
recovery do not isolate the causal effect of reheating from additional training.
|
| 332 |
+
|
| 333 |
+
At step 8,217, per-source losses were web **3.4116**, DCLM **3.6108**, wiki
|
| 334 |
+
**2.7977**, and Cosmopedia **2.4896**. Evaluation uses 16 batches of two sequences
|
| 335 |
+
per source: 262,144 target positions in total. The aggregate applies the training
|
| 336 |
+
mixture weights. Pilot and continuation preserve the same held-out fingerprint.
|
| 337 |
+
|
| 338 |
+
One earlier production readout at step 7,980 reported 13,794 interval tokens/sec
|
| 339 |
+
and 13,578 run tokens/sec across the cluster. This is an observed counter, not a
|
| 340 |
+
controlled performance benchmark, utilization measurement, or total runtime.
|
| 341 |
+
|
| 342 |
+
## Selected Pretrained Base
|
| 343 |
+
|
| 344 |
+
The selected pretrained checkpoint is the preserved Stage B base at
|
| 345 |
+
step **73,243**, after **7,800,086,528 pretraining tokens**. Its original legacy
|
| 346 |
+
validation loss is **2.81855024**. Its expanded validation loss is **2.76700753**.
|
| 347 |
+
These are different evaluation sets and must not be merged into one loss curve.
|
| 348 |
+
The expanded set has 256 batches of two sequences per source, or 4,194,304
|
| 349 |
+
positions in total; the legacy set has 262,144 positions.
|
| 350 |
+
|
| 351 |
+
The historical September 18 milestones above remain a dated record, not the
|
| 352 |
+
current training counter. Lower next-token loss does not by itself establish
|
| 353 |
+
correct answers, reasoning, or reliable instruction following.
|
| 354 |
+
|
| 355 |
+
## Evaluation
|
| 356 |
+
|
| 357 |
+
Results identify either the **pretrained Stage B base at step 73,243** or the
|
| 358 |
+
**selected OpenSML-150M SFT checkpoint at total step 768**. Their identities and
|
| 359 |
+
results are kept separate. The pretrained weight SHA-256 is:
|
| 360 |
+
|
| 361 |
+
```text
|
| 362 |
+
ca9bd5d82005f28e77f319d3a5a29f29fb4e4f86e7ceea049f01162fd8aae80f
|
| 363 |
+
```
|
| 364 |
+
|
| 365 |
+
### Zero-shot Likelihood Benchmarks
|
| 366 |
+
|
| 367 |
+
The complete evaluation scored **15,428 multiple-choice examples**. Higher is
|
| 368 |
+
better; raw and normalized accuracy are separate metrics.
|
| 369 |
+
|
| 370 |
+
| Benchmark | Split | Examples | Pretrained base acc / acc_norm | OpenSML-150M acc / acc_norm |
|
| 371 |
+
| --- | --- | ---: | ---: | ---: |
|
| 372 |
+
| ARC-Easy | Test | 2,376 | 54.67% / 48.53% | 56.65% / 55.43% |
|
| 373 |
+
| ARC-Challenge | Test | 1,172 | 23.38% / 26.88% | 26.02% / 29.52% |
|
| 374 |
+
| PIQA | Validation | 1,838 | 65.23% / 64.36% | 64.53% / 64.09% |
|
| 375 |
+
| HellaSwag | Validation | 10,042 | 30.21% / 34.44% | 30.55% / 33.94% |
|
| 376 |
+
|
| 377 |
+
Under the recorded protocol, the selected SFT checkpoint improves both ARC
|
| 378 |
+
metrics over the base. PIQA is slightly lower; HellaSwag raw accuracy increases
|
| 379 |
+
slightly while normalized accuracy decreases. Fine-tuning therefore shows a
|
| 380 |
+
mixed result rather than uniform gains.
|
| 381 |
+
|
| 382 |
+
Scoring ranks supplied answer continuations by their summed log-likelihood
|
| 383 |
+
(`acc`). `acc_norm` divides that score by the candidate text's Unicode character
|
| 384 |
+
count, rather than token count. The evaluator uses plain task completion prompts,
|
| 385 |
+
no few-shot demonstrations, no chat template, and no added BOS/EOS tokens. It
|
| 386 |
+
loads the selected checkpoint in FP32, uses reference feed-forward operations
|
| 387 |
+
and explicit vanilla MLX attention, and scores one example at a time. No response
|
| 388 |
+
sampling or LLM judge is involved.
|
| 389 |
+
|
| 390 |
+
The custom evaluator follows the pinned lm-evaluation-harness task conventions
|
| 391 |
+
at revision `b954108c9baaaa934b4ad842033b31a97ee30816`; this is not an installed
|
| 392 |
+
harness run or an official leaderboard submission. All expected rows completed,
|
| 393 |
+
and the saved integrity receipt records unchanged inputs. Different prompt,
|
| 394 |
+
normalization, tokenizer, or numerical settings can change scores. These numbers
|
| 395 |
+
are not automatically comparable with external model cards. A comprehensive
|
| 396 |
+
pretraining contamination audit has not been established, and these are not
|
| 397 |
+
claimed to be untouched final-test results.
|
| 398 |
+
|
| 399 |
+
### Comparison with Small Language Models
|
| 400 |
+
|
| 401 |
+
**OpenSML-150M** is compared below with recognizable models in the same approximate
|
| 402 |
+
parameter range: GPT-2 (124M), OPT-125M, and Pythia-160M. All external values are
|
| 403 |
+
**previously published results**. OpenSML values are
|
| 404 |
+
our existing measurements of the selected fine-tuned checkpoint.
|
| 405 |
+
|
| 406 |
+
Each cell shows **acc / acc_norm**; **—** means the cited source does not report
|
| 407 |
+
that metric. Bold marks the highest available reported value in each column.
|
| 408 |
+
These are cross-source comparisons, not a controlled common-harness ranking.
|
| 409 |
+
|
| 410 |
+
| Model | ARC-Easy acc / acc_norm | ARC-Challenge acc / acc_norm | PIQA acc / acc_norm | HellaSwag acc / acc_norm |
|
| 411 |
+
| --- | ---: | ---: | ---: | ---: |
|
| 412 |
+
| **OpenSML-150M (SFT)** | **56.65% / 55.43%** | **26.02% / 29.52%** | **64.53% / 64.09%** | **30.55% / 33.94%** |
|
| 413 |
+
| [GPT-2 (124M, base)](https://huggingface.co/openai-community/gpt2) | — / 39.48% | — / — | — / 62.51% | 28.92% / 31.14% |
|
| 414 |
+
| [OPT-125M (base)](https://huggingface.co/facebook/opt-125m) | 43.52% / 39.98% | 18.94% / 22.78% | 63.00% / 62.02% | — / — |
|
| 415 |
+
| [Pythia-160M (base)](https://huggingface.co/EleutherAI/pythia-160m) | 43.52% / 39.65% | 18.77% / 23.29% | 62.73% / 61.64% | — / — |
|
| 416 |
+
|
| 417 |
+
**The strongest reported margin is ARC-Easy:** OpenSML-150M's normalized score
|
| 418 |
+
is +15.45 percentage points above OPT-125M and +15.78 points above Pythia-160M.
|
| 419 |
+
On normalized ARC-Challenge, the respective differences are +6.74 and +6.23
|
| 420 |
+
points. OpenSML also exceeds the available published PIQA and GPT-2 HellaSwag
|
| 421 |
+
values shown here. These differences describe the reported numbers, not
|
| 422 |
+
statistically established superiority under identical evaluation settings.
|
| 423 |
+
|
| 424 |
+
OpenSML uses the zero-shot native-MLX protocol described above, with
|
| 425 |
+
character-normalized `acc_norm`. External metrics retain their source definitions;
|
| 426 |
+
we have not verified identical prompts, normalization, precision, or dataset
|
| 427 |
+
revisions across all sources. OpenSML is instruction fine-tuned, whereas the
|
| 428 |
+
three references are pretrained base models. The comparison therefore does not
|
| 429 |
+
isolate architecture, pretraining quality, or instruction-following ability.
|
| 430 |
+
Missing external metrics have not been filled by running new evaluations.
|
| 431 |
+
|
| 432 |
+
### Instruction Following: IFEval
|
| 433 |
+
|
| 434 |
+
These results apply only to **OpenSML-150M**, not the pretrained base.
|
| 435 |
+
|
| 436 |
+
| Checkpoint | Prompt strict | Instruction strict | Prompt loose | Instruction loose | 1,280-token cap hits |
|
| 437 |
+
| --- | ---: | ---: | ---: | ---: | ---: |
|
| 438 |
+
| OpenSML-150M | 15.16% (82/541) | 25.30% (211/834) | 15.71% (85/541) | 25.78% (215/834) | 33/541 |
|
| 439 |
+
|
| 440 |
+
The evaluation completes all 541 official prompts and 834 instructions using
|
| 441 |
+
zero-shot greedy generation and the pinned programmatic strict/loose verifiers,
|
| 442 |
+
without an LLM judge. Each unchanged prompt is formatted as
|
| 443 |
+
`User: {prompt}\nAssistant:` with no added system message. Generation uses cached
|
| 444 |
+
native MLX decoding, context 2,048, a 1,280-new-token cap, document-end EOS ID 1,
|
| 445 |
+
no additional stop strings, and no repetition penalty. Outputs are scored as
|
| 446 |
+
produced, including length-capped answers. Of the responses, 508 stop at EOS,
|
| 447 |
+
33 reach the generation cap, and none hit the context limit.
|
| 448 |
+
|
| 449 |
+
The dataset's official split is named `train`; these evaluation examples are
|
| 450 |
+
not used as supervised training records in the documented experiment. Benchmark
|
| 451 |
+
inspection across multiple candidates nevertheless limits independence of model
|
| 452 |
+
selection. No pretrained-base IFEval score is reported here.
|
| 453 |
+
|
| 454 |
+
### Complete-answer Diagnostics
|
| 455 |
+
|
| 456 |
+
For OpenSML-150M, saved development generations cover 63 legacy-retention turns
|
| 457 |
+
and 73 public-development turns. The recorded follow-up joint proxy is 22/32;
|
| 458 |
+
5/32 public named-constraint checks pass. Repetition is detected on 4/63 legacy
|
| 459 |
+
turns and 18/73 public turns; in the chat subset it rises from Repair512's 3/18
|
| 460 |
+
to 4/18. These are development diagnostics and mechanical proxies, not
|
| 461 |
+
independent human-reviewed complete-answer correctness rates.
|
| 462 |
+
|
| 463 |
+
A systematic complete-answer review comparable to PetitGPT's published suite
|
| 464 |
+
has not been established for the selected checkpoint. Likelihood and IFEval
|
| 465 |
+
scores do not establish factual correctness or reliable conversational answers.
|
| 466 |
+
|
| 467 |
+
### Reading and Fact-sensitivity Diagnostics (Pretrained Base)
|
| 468 |
+
|
| 469 |
+
The following diagnostics apply to the pretrained base, not Trial 28.
|
| 470 |
+
A separate September 24 audit used **400-example subsets per task**, distinct
|
| 471 |
+
from the full benchmark results above. On the same selected rows, OpenSML base
|
| 472 |
+
and a pinned SmolLM2-135M **base** reference scored:
|
| 473 |
+
|
| 474 |
+
| Diagnostic | OpenSML base | SmolLM2-135M base |
|
| 475 |
+
| --- | ---: | ---: |
|
| 476 |
+
| PIQA | 65.00% | 66.00% |
|
| 477 |
+
| HellaSwag | 34.25% | 42.25% |
|
| 478 |
+
| BoolQ | 62.75% | 62.75% |
|
| 479 |
+
|
| 480 |
+
The reference revision was `93efa2f097d58c2a74874c7e644dbc9b0cee75a2`.
|
| 481 |
+
These are local matched-subset measurements, not the reference model's published
|
| 482 |
+
full-benchmark scores. Different data, architecture, tokenizers, and training
|
| 483 |
+
budgets prevent attributing the differences to pretraining exposure alone.
|
| 484 |
+
|
| 485 |
+
BoolQ accuracy did not establish reliable reading: OpenSML selected "yes" on
|
| 486 |
+
95.25% of items; without the passage it scored 58.75%. In a separate authored
|
| 487 |
+
fact-swap diagnostic, the model answered both variants correctly on **18/120
|
| 488 |
+
pairs** in question/answer format. Swapping the passage changes the correct
|
| 489 |
+
choice, so this diagnostic checks whether recognition follows supplied facts.
|
| 490 |
+
The pairs share templates and are not 240 independent task families.
|
| 491 |
+
|
| 492 |
+
### What These Results Establish
|
| 493 |
+
|
| 494 |
+
Likelihood benchmarks measure recognition among supplied choices. They do not
|
| 495 |
+
measure whether the model can independently write a factually correct, complete
|
| 496 |
+
answer. The reading diagnostics also score choices rather than complete assistant
|
| 497 |
+
responses. A systematic complete-answer evaluation comparable to a reviewed
|
| 498 |
+
free-form answer suite has not been established for this pretrained checkpoint.
|
| 499 |
+
IFEval for the selected SFT checkpoint is reported separately above. No
|
| 500 |
+
MT-Bench or coding-success score is claimed for that checkpoint.
|
| 501 |
+
|
| 502 |
+
## Checkpoint Identity and Verification
|
| 503 |
+
|
| 504 |
+
The pretrained checkpoint is `step_0073243_7f3070237eea`, selected from the Stage B run.
|
| 505 |
+
The selected SFT checkpoint is `step_0000768_4980617cb301`, with weight SHA-256:
|
| 506 |
+
|
| 507 |
+
```text
|
| 508 |
+
cbd3e3fb4ada74d7264371b79cee7598f513b7b950f1f141ef9f1a43bd2e1b4e
|
| 509 |
+
```
|
| 510 |
+
|
| 511 |
+
The SFT weight hash was verified against the retained bundle. Its full multiple-choice
|
| 512 |
+
and IFEval integrity receipts record 15,428 and 541 completed examples respectively,
|
| 513 |
+
with unchanged inputs. Checkpoint metadata pins Repair512 as its direct parent.
|
| 514 |
+
A portable [Trial 28 results and provenance record](https://huggingface.co/wzebrowski/OpenSML-150M/resolve/main/TRIAL28_RESULTS.json) preserves
|
| 515 |
+
exact scores, protocol settings, dataset pins, and source-record hashes.
|
| 516 |
+
Local evaluation records pin its weight hash, tokenizer fingerprint, dataset
|
| 517 |
+
revisions, evaluator source hashes, and runtime settings. The full-benchmark
|
| 518 |
+
integrity receipt records 15,428 completed examples with unchanged inputs.
|
| 519 |
+
The tokenizer round-trip audit is described above. These checks establish
|
| 520 |
+
artifact identity and the scope of the recorded evaluation; they do not establish
|
| 521 |
+
cross-framework inference parity or deployment readiness. A released-weight
|
| 522 |
+
export verification and reproducible inference guide remain pending.
|
| 523 |
+
|
| 524 |
+
## Limitations and Intended Use
|
| 525 |
+
|
| 526 |
+
The eventual model is intended for small-language-model research and controlled
|
| 527 |
+
experimentation. The selected checkpoint is instruction-tuned, but is not a validated production assistant. It may generate
|
| 528 |
+
incorrect, repetitive, biased, offensive, or unsafe text. Do not rely on it for
|
| 529 |
+
high-stakes decisions. Broader capability and safety assessments remain pending.
|
| 530 |
+
|
| 531 |
+
Architecture, tokenizer, data, and context differ from earlier experiments;
|
| 532 |
+
this run alone cannot attribute any improvement to a single change.
|
| 533 |
+
|
| 534 |
+
## Repository Contents and Release Plan
|
| 535 |
+
|
| 536 |
+
- This model card documents the selected SFT checkpoint, pretrained ancestry, and separately labeled evaluations.
|
| 537 |
+
- `configs/` contains the original pinned corpus and pilot/early-continuation recipes; these are historical, not the complete later training history.
|
| 538 |
+
- `tokenizer/` contains the completed tokenizer, its corpus contract, and audit.
|
| 539 |
+
- Model weights, optimizer states, raw datasets, credentials, and private network configuration are not included.
|
| 540 |
+
|
| 541 |
+
Before a weight release, freeze the selected checkpoint and evaluation evidence,
|
| 542 |
+
add tested inference instructions and necessary implementation code, and review
|
| 543 |
+
third-party attribution. No release date is promised.
|
| 544 |
+
|
| 545 |
+
## License
|
| 546 |
+
|
| 547 |
+
OpenSML-150M project contributions in this repository are licensed under the
|
| 548 |
+
[Apache License 2.0](https://huggingface.co/wzebrowski/OpenSML-150M/resolve/main/LICENSE), for rights controlled by the author.
|
| 549 |
+
Upstream datasets and third-party materials retain their own licenses and
|
| 550 |
+
attribution requirements; the repository license does not relicense them.
|
| 551 |
+
|
| 552 |
+
Post-training sources also retain their own terms. Trial 28 source records list
|
| 553 |
+
SmolTalk as Apache-2.0, SQuAD v2 as CC-BY-SA-4.0, and SciQ as CC-BY-NC-3.0.
|
| 554 |
+
Apache-2.0 metadata for author-controlled project contributions is not a blanket
|
| 555 |
+
commercial-use license for all upstream materials or a completed weight-release
|
| 556 |
+
licensing review.
|
| 557 |
+
|
| 558 |
+
## External Benchmark Source Records
|
| 559 |
+
|
| 560 |
+
External comparison values are published measurements, not results from local
|
| 561 |
+
baseline evaluations. Incomplete local baseline runs are not used in the model card.
|
| 562 |
+
|
| 563 |
+
- GPT-2 normalized ARC-Easy and PIQA: [nano-chatgpt published table](https://github.com/Seif-Yasser-Ahmed/nano-chatgpt/blob/2c6b48b4e2eb612447b0858460c3d0472f00a98b/README.md#presentation-benchmark-table); shot counts are unspecified in that table. GPT-2 HellaSwag acc/acc_norm: [saved baseline JSON](https://github.com/Seif-Yasser-Ahmed/nano-chatgpt/blob/2c6b48b4e2eb612447b0858460c3d0472f00a98b/out_gpt2/10B/checkpoint_19072/evaluation_results/hellaswag_metrics.json). The project's comparison script invokes default HellaSwag few-shot settings. These are project measurements, not official OpenAI claims.
|
| 564 |
+
- OPT-125M: [EleutherAI baseline JSON](https://github.com/EleutherAI/pythia/blob/a19eecb807ec2c79a39ebf18108816e6ffffc1d5/evals/opt/opt-125m.json), `num_fewshot: 0`, `limit: null`; HellaSwag absent.
|
| 565 |
+
- Pythia-160M: [EleutherAI official non-deduplicated suite, step 143,000](https://github.com/EleutherAI/pythia/blob/a19eecb807ec2c79a39ebf18108816e6ffffc1d5/evals/pythia-v1/pythia-160m/zero-shot/160m_step143000.json), `num_fewshot: 0`, `limit: null`; HellaSwag absent.
|
| 566 |
+
|
| 567 |
+
## Retained SFT Dataset Exposure
|
| 568 |
+
|
| 569 |
+
These are record exposures, not token shares or unique-example counts. The
|
| 570 |
+
trainers consume ordered batches of 16 records. Tables count the first 6,144,
|
| 571 |
+
2,048, and 4,096 records at the three retained training boundaries respectively.
|
| 572 |
+
|
| 573 |
+
### Unified384
|
| 574 |
+
|
| 575 |
+
| Source | Record exposures | Share | Role |
|
| 576 |
+
| --- | ---: | ---: | --- |
|
| 577 |
+
| HuggingFaceTB/smol-smoltalk | 3,071 | 49.98% | Stage mixture |
|
| 578 |
+
| arc_easy | 198 | 3.22% | Stage mixture |
|
| 579 |
+
| HuggingFaceH4/ultrachat_200k | 1,761 | 28.66% | Stage mixture |
|
| 580 |
+
| authored-given-facts-v1 | 384 | 6.25% | Stage mixture |
|
| 581 |
+
| authored-fictional-text-v1 | 384 | 6.25% | Stage mixture |
|
| 582 |
+
| squad_v2 | 160 | 2.60% | Stage mixture |
|
| 583 |
+
| arc_challenge | 186 | 3.03% | Stage mixture |
|
| 584 |
+
| **Total** | **6,144** | **100%** | |
|
| 585 |
+
|
| 586 |
+
### Repair512
|
| 587 |
+
|
| 588 |
+
| Source | Record exposures | Share | Role |
|
| 589 |
+
| --- | ---: | ---: | --- |
|
| 590 |
+
| HuggingFaceTB/smol-smoltalk | 259 | 12.65% | Stage mixture |
|
| 591 |
+
| databricks/databricks-dolly-15k | 1,024 | 50.00% | Stage mixture |
|
| 592 |
+
| HuggingFaceH4/ultrachat_200k | 253 | 12.35% | Stage mixture |
|
| 593 |
+
| allenai/tulu-3-sft-personas-instruction-following | 512 | 25.00% | Stage mixture |
|
| 594 |
+
| **Total** | **2,048** | **100%** | |
|
| 595 |
+
|
| 596 |
+
### OpenSML-150M final continuation
|
| 597 |
+
|
| 598 |
+
| Source | Record exposures | Share | Role |
|
| 599 |
+
| --- | ---: | ---: | --- |
|
| 600 |
+
| allenai/tulu-3-sft-personas-instruction-following | 256 | 6.25% | Repair512 replay |
|
| 601 |
+
| HuggingFaceTB/smoltalk | 1,536 | 37.50% | Stage mixture |
|
| 602 |
+
| rajpurkar/squad_v2 | 1,024 | 25.00% | Stage mixture |
|
| 603 |
+
| databricks/databricks-dolly-15k | 512 | 12.50% | Repair512 replay |
|
| 604 |
+
| allenai/sciq | 512 | 12.50% | Stage mixture |
|
| 605 |
+
| HuggingFaceTB/smol-smoltalk | 132 | 3.22% | Repair512 replay |
|
| 606 |
+
| HuggingFaceH4/ultrachat_200k | 124 | 3.03% | Repair512 replay |
|
| 607 |
+
| **Total** | **4,096** | **100%** | |
|
| 608 |
+
|
| 609 |
+
|
| 610 |
+
## Historical Appendix — September 18, 2026
|
| 611 |
+
|
| 612 |
+
The following is the preserved original report at its 1B-token reporting boundary.
|
| 613 |
+
It is historical evidence, not the current model-card release status. Relative
|
| 614 |
+
links in this appendix refer to the original V2 documentation tree.
|
| 615 |
+
|
| 616 |
+
### Historical OpenSML-152M: Pretraining a Small Language Model on Apple Silicon
|
| 617 |
+
|
| 618 |
+
**William Zebrowski | Working technical report | September 18, 2026**
|
| 619 |
+
|
| 620 |
+
**Status: pretraining in progress.** Quantitative results below are frozen at
|
| 621 |
+
step 9,391, or 1,000,103,936 consumed training tokens. The planned endpoint is
|
| 622 |
+
15 billion tokens; it is not a completed result.
|
| 623 |
+
|
| 624 |
+
Project overview (`../README.md` in the original V2 documentation tree) | Data and tokenizer (`DATA_AND_TOKENIZER.md` in the original V2 documentation tree) |
|
| 625 |
+
Results notes (`RESULTS.md` in the original V2 documentation tree) | Evidence index (`EVIDENCE.md` in the original V2 documentation tree)
|
| 626 |
+
|
| 627 |
+
## Abstract
|
| 628 |
+
|
| 629 |
+
OpenSML-152M is an English-first, decoder-only language model trained from random
|
| 630 |
+
initialization on a four-Mac Studio cluster. Its implemented architecture contains
|
| 631 |
+
**150,439,168 trainable parameters**, with 20 Transformer blocks, a hidden width
|
| 632 |
+
of 768, grouped-query attention, tied embeddings, and a 2,048-token context.
|
| 633 |
+
The project name is a rounded model label, not the exact parameter count.
|
| 634 |
+
|
| 635 |
+
A custom 32,000-token byte-level BPE tokenizer was fitted to a representative
|
| 636 |
+
sample of the selected educational-prose corpus. Pretraining streams four
|
| 637 |
+
source components from three Hugging Face repositories, using a target token
|
| 638 |
+
mixture of 55% FineWeb-Edu, 25% DCLM-Edu, 10% English FineWiki, and 10% filtered
|
| 639 |
+
Cosmopedia. The training system combines BF16 computation with FP32 optimizer
|
| 640 |
+
state and gradients, unequal per-device batches, and Thunderbolt RDMA ring
|
| 641 |
+
communication through MLX/JACCL.
|
| 642 |
+
|
| 643 |
+
At the reporting boundary, aggregate development cross-entropy is **3.2812**
|
| 644 |
+
and perplexity is **26.61** on the fixed reference batches. These are interim
|
| 645 |
+
next-token prediction measurements, not downstream capability scores. Repetitive
|
| 646 |
+
and factually incorrect completions remain visible. This report documents the
|
| 647 |
+
implemented method and its evidence while leaving final evaluation, post-training,
|
| 648 |
+
and release claims explicitly open.
|
| 649 |
+
|
| 650 |
+
## Contents
|
| 651 |
+
|
| 652 |
+
1. [Scope and Reporting Conventions](#1-scope-and-reporting-conventions)
|
| 653 |
+
2. [Model Architecture](#2-model-architecture)
|
| 654 |
+
3. [Tokenizer](#3-tokenizer)
|
| 655 |
+
4. [Pretraining Data](#4-pretraining-data)
|
| 656 |
+
5. [Optimization and Training Schedule](#5-optimization-and-training-schedule)
|
| 657 |
+
6. [Distributed Execution](#6-distributed-execution)
|
| 658 |
+
7. [Checkpointing and Reproducibility](#7-checkpointing-and-reproducibility)
|
| 659 |
+
8. [Evaluation Methodology](#8-evaluation-methodology)
|
| 660 |
+
9. [Interim Results](#9-interim-results)
|
| 661 |
+
10. [Post-Training and Release Status](#10-post-training-and-release-status)
|
| 662 |
+
11. [Limitations and Intended Use](#11-limitations-and-intended-use)
|
| 663 |
+
12. [Evidence and Completion Checklist](#12-evidence-and-completion-checklist)
|
| 664 |
+
|
| 665 |
+
## 1. Scope and Reporting Conventions
|
| 666 |
+
|
| 667 |
+
### 1.1 Research objective
|
| 668 |
+
|
| 669 |
+
The objective is a useful small text-generation model with a traceable training
|
| 670 |
+
process on locally available Apple Silicon hardware. Throughput matters as a
|
| 671 |
+
resource constraint, but model selection is not based on throughput alone.
|
| 672 |
+
The architecture and mixture are this project's chosen configuration of
|
| 673 |
+
established components, not a claim of architectural novelty.
|
| 674 |
+
|
| 675 |
+
These weights were initialized from scratch. Earlier models and their
|
| 676 |
+
fine-tuning experiments are not ancestors of these weights and are not evidence
|
| 677 |
+
of this model's capabilities. Reused implementation components are separately
|
| 678 |
+
recorded in code provenance (`../provenance.json` in the original V2 documentation tree).
|
| 679 |
+
|
| 680 |
+
### 1.2 What the report distinguishes
|
| 681 |
+
|
| 682 |
+
| Term | Meaning here |
|
| 683 |
+
| --- | --- |
|
| 684 |
+
| Configured | Present in the recorded recipe or implemented code |
|
| 685 |
+
| Observed | Supported by an identified log, audit, or artifact |
|
| 686 |
+
| Planned | Not yet a completed experiment or measured outcome |
|
| 687 |
+
| Consumed training tokens | Token positions included in completed optimizer updates along this run's lineage |
|
| 688 |
+
| Validation loss | Cross-entropy on fixed held-out reference batches, not generated-answer accuracy |
|
| 689 |
+
| Best checkpoint | Lowest observed weighted validation loss under this evaluation contract |
|
| 690 |
+
| Latest checkpoint | Most recent successfully committed resumable state |
|
| 691 |
+
|
| 692 |
+
Validation records, qualitative probes, and future independent benchmarks are
|
| 693 |
+
different evidence types. Repeated use of reference batches makes them
|
| 694 |
+
development evidence, not an untouched final test. Results from another
|
| 695 |
+
tokenizer, corpus, or evaluation protocol are not directly comparable by raw loss.
|
| 696 |
+
|
| 697 |
+
### 1.3 Reporting boundary
|
| 698 |
+
|
| 699 |
+
This document is a versioned snapshot, not a live status dashboard. Training may
|
| 700 |
+
have advanced beyond the values shown. A machine-readable
|
| 701 |
+
validation table (`tables/validation_through_0009391.csv` in the original V2 documentation tree) and its
|
| 702 |
+
provenance record (`tables/validation_through_0009391.json` in the original V2 documentation tree) accompany this revision.
|
| 703 |
+
Earlier supporting notes may use earlier, explicitly dated cutoffs.
|
| 704 |
+
|
| 705 |
+
## 2. Model Architecture
|
| 706 |
+
|
| 707 |
+
### 2.1 Transformer configuration
|
| 708 |
+
|
| 709 |
+
| Component | Implemented value |
|
| 710 |
+
| --- | --- |
|
| 711 |
+
| Model family | Autoregressive, decoder-only Transformer |
|
| 712 |
+
| Trainable parameters | 150,439,168 |
|
| 713 |
+
| Transformer blocks | 20 |
|
| 714 |
+
| Hidden width | 768 |
|
| 715 |
+
| Context length | 2,048 tokens |
|
| 716 |
+
| Vocabulary | 32,000 |
|
| 717 |
+
| Query / key-value heads | 12 / 4 |
|
| 718 |
+
| Head dimension | 64 |
|
| 719 |
+
| Position representation | Rotary position embeddings; base 10,000 |
|
| 720 |
+
| Normalization | Pre-norm RMSNorm; per-head query/key RMSNorm; final RMSNorm |
|
| 721 |
+
| Feed-forward | SwiGLU; intermediate width 2,048 |
|
| 722 |
+
| Vocabulary interface | Shared input embedding and output projection |
|
| 723 |
+
| Linear biases / dropout | No linear biases; no dropout layers |
|
| 724 |
+
|
| 725 |
+
Each attention block uses a fused QKV projection. Its output width is
|
| 726 |
+
768 + 256 + 256 = 1,280. Grouped-query attention shares four key/value heads
|
| 727 |
+
across twelve query heads. The configured fast-attention path passes grouped
|
| 728 |
+
heads to MLX's scaled dot-product attention rather than explicitly expanding the
|
| 729 |
+
key/value tensors in Python.
|
| 730 |
+
|
| 731 |
+
### 2.2 Block computation
|
| 732 |
+
|
| 733 |
+
For residual input x, each block computes:
|
| 734 |
+
|
| 735 |
+
~~~text
|
| 736 |
+
h = x + Attention(RMSNorm(x))
|
| 737 |
+
y = h + SwiGLU(RMSNorm(h))
|
| 738 |
+
|
| 739 |
+
SwiGLU(z) = down(silu(gate(z)) * up(z))
|
| 740 |
+
logits = RMSNorm(final_hidden) @ embedding_weight.T
|
| 741 |
+
~~~
|
| 742 |
+
|
| 743 |
+
Query and key normalization occur before rotary position encoding. Attention
|
| 744 |
+
uses a causal mask and scale 1/sqrt(64). The configured MLP ratio of 4 is a
|
| 745 |
+
construction parameter: applying the SwiGLU width adjustment and alignment
|
| 746 |
+
produces an actual intermediate width of 2,048, not 3,072.
|
| 747 |
+
|
| 748 |
+
### 2.3 Parameter accounting
|
| 749 |
+
|
| 750 |
+
The input embedding and output projection are tied and counted once.
|
| 751 |
+
|
| 752 |
+
| Component | Parameters across the model |
|
| 753 |
+
| --- | ---: |
|
| 754 |
+
| Shared token embedding / output matrix | 24,576,000 |
|
| 755 |
+
| QKV projections, 20 blocks | 19,660,800 |
|
| 756 |
+
| Attention output projections, 20 blocks | 11,796,480 |
|
| 757 |
+
| SwiGLU projections, 20 blocks | 94,371,840 |
|
| 758 |
+
| Block and Q/K normalization weights | 33,280 |
|
| 759 |
+
| Final normalization | 768 |
|
| 760 |
+
| **Total** | **150,439,168** |
|
| 761 |
+
|
| 762 |
+
The shared vocabulary matrix accounts for approximately 16.3% of parameters.
|
| 763 |
+
The model has no separate learned positional embedding table.
|
| 764 |
+
|
| 765 |
+
### 2.4 Initialization and numerical representation
|
| 766 |
+
|
| 767 |
+
Matrix weights use normal initialization with standard deviation 0.02.
|
| 768 |
+
Attention output and feed-forward down projections are scaled by
|
| 769 |
+
1/sqrt(2L), where L = 20. Normalization weights start at one.
|
| 770 |
+
|
| 771 |
+
BF16 is used for model computation. FP32 master weights, optimizer moments,
|
| 772 |
+
gradient accumulation, and reduced gradients preserve precision during updates.
|
| 773 |
+
This is mixed-precision training, not an all-BF16 optimizer.
|
| 774 |
+
|
| 775 |
+
Implementation evidence: model (`../sml_v2/model.py` in the original V2 documentation tree),
|
| 776 |
+
precision and optimizer (`../sml_v2/precision.py` in the original V2 documentation tree).
|
| 777 |
+
|
| 778 |
+
## 3. Tokenizer
|
| 779 |
+
|
| 780 |
+
### 3.1 Construction
|
| 781 |
+
|
| 782 |
+
The tokenizer is **ByteBPE32K v1**, trained for this corpus rather than inherited
|
| 783 |
+
from the earlier model. Its fitting sample follows the same source proportions
|
| 784 |
+
as pretraining, but sampling quotas are measured in UTF-8 bytes rather than
|
| 785 |
+
model tokens.
|
| 786 |
+
|
| 787 |
+
| Property | Recorded value |
|
| 788 |
+
| --- | --- |
|
| 789 |
+
| Algorithm | Byte-level BPE |
|
| 790 |
+
| Vocabulary size | 32,000 IDs including four structural tokens |
|
| 791 |
+
| Initial alphabet | Full 256-byte alphabet |
|
| 792 |
+
| Minimum merge frequency | 2 |
|
| 793 |
+
| Fitting sample | 500,048,186 UTF-8 bytes; 113,898 documents |
|
| 794 |
+
| Development audit | 4,010,605 UTF-8 bytes; 970 documents |
|
| 795 |
+
| Tokenizers library | 0.22.2 |
|
| 796 |
+
| Normalization / prefix space | No text normalizer; no automatic prefix space |
|
| 797 |
+
| Implicit BOS/EOS insertion | None |
|
| 798 |
+
| Sampling | Seeded source shuffling; buffer size 10,000 |
|
| 799 |
+
|
| 800 |
+
A 500 MB tokenizer fitting sample is not the pretraining dataset size.
|
| 801 |
+
The fitted tokenizer is frozen during model training.
|
| 802 |
+
|
| 803 |
+
### 3.2 Encoding contract
|
| 804 |
+
|
| 805 |
+
| ID | Token | Role |
|
| 806 |
+
| ---: | --- | --- |
|
| 807 |
+
| 0 | `<|pad|>` | Reserved padding |
|
| 808 |
+
| 1 | `<|doc_end|>` | Explicit document boundary |
|
| 809 |
+
| 2 | `<|turn_start|>` | Reserved for potential conversational formatting |
|
| 810 |
+
| 3 | `<|turn_end|>` | Reserved for potential conversational formatting |
|
| 811 |
+
|
| 812 |
+
Content encoding does not insert structural IDs automatically. Literal spellings
|
| 813 |
+
of structural tokens in input text are encoded as ordinary content; the wrapper
|
| 814 |
+
rejects an unexpected reserved ID in encoded content. Pretraining appends the
|
| 815 |
+
document-end token explicitly. Reserved turn tokens do not imply that chat
|
| 816 |
+
formatting or instruction following has been trained.
|
| 817 |
+
|
| 818 |
+
### 3.3 Audit results
|
| 819 |
+
|
| 820 |
+
| Held-out source | Documents | UTF-8 bytes | Encoded tokens | Bytes/token |
|
| 821 |
+
| --- | ---: | ---: | ---: | ---: |
|
| 822 |
+
| FineWeb-Edu | 559 | 2,205,062 | 476,722 | 4.6255 |
|
| 823 |
+
| DCLM-Edu | 165 | 1,001,509 | 224,896 | 4.4532 |
|
| 824 |
+
| FineWiki | 143 | 401,775 | 98,977 | 4.0593 |
|
| 825 |
+
| Cosmopedia | 103 | 402,259 | 79,482 | 5.0610 |
|
| 826 |
+
|
| 827 |
+
The held-out audit recorded zero round-trip failures; nine regression fixtures
|
| 828 |
+
also passed. These checks establish properties of the audited encoding, not
|
| 829 |
+
downstream quality or an exhaustive audit of future streamed documents.
|
| 830 |
+
|
| 831 |
+
The manifest (`../tokenizer/bytebpe32k_v1/manifest.json` in the original V2 documentation tree) and
|
| 832 |
+
audit report (`../tokenizer/bytebpe32k_v1/report.json` in the original V2 documentation tree) retain the detailed records.
|
| 833 |
+
The tokenizer artifact fingerprint is:
|
| 834 |
+
|
| 835 |
+
~~~text
|
| 836 |
+
1194292c6d906ac19e6f01c6ad2b42825143fad426a22aa8856d903776701ecb
|
| 837 |
+
~~~
|
| 838 |
+
|
| 839 |
+
## 4. Pretraining Data
|
| 840 |
+
|
| 841 |
+
### 4.1 Source mixture
|
| 842 |
+
|
| 843 |
+
Pretraining uses four components from three upstream repositories. All are read
|
| 844 |
+
from their upstream training splits, with project-specific content-hash splits
|
| 845 |
+
applied afterward.
|
| 846 |
+
|
| 847 |
+
| Component | Upstream repository / configuration | Target token share | Additional selection |
|
| 848 |
+
| --- | --- | ---: | --- |
|
| 849 |
+
| Web | [HuggingFaceTB/smollm-corpus](https://huggingface.co/datasets/HuggingFaceTB/smollm-corpus), `fineweb-edu-dedup` | 55% | Shared text-quality filters |
|
| 850 |
+
| DCLM | [HuggingFaceTB/dclm-edu](https://huggingface.co/datasets/HuggingFaceTB/dclm-edu) | 25% | `edu_int_score >= 3` |
|
| 851 |
+
| Wiki | [HuggingFaceFW/finewiki](https://huggingface.co/datasets/HuggingFaceFW/finewiki), `en` | 10% | English configuration |
|
| 852 |
+
| Cosmopedia | SmolLM corpus, `cosmopedia-v2` | 10% | Format contains textbook, tutorial, blog, or educational |
|
| 853 |
+
|
| 854 |
+
Pinned revisions:
|
| 855 |
+
|
| 856 |
+
~~~text
|
| 857 |
+
SmolLM corpus: 3ba9d605774198c5868892d7a8deda78031a781f
|
| 858 |
+
DCLM-Edu: dbad8ad71224482740cd9c9d353591adbf62fe04
|
| 859 |
+
FineWiki: 8bd13e72e6a002407649b3e898535f42ceb1aeb9
|
| 860 |
+
~~~
|
| 861 |
+
|
| 862 |
+
The mixture is prose-focused; no dedicated coding or mathematics source is
|
| 863 |
+
selected. This does not mean every document is free of code, equations, or
|
| 864 |
+
incidental non-English text. Shares describe target consumed token proportions,
|
| 865 |
+
not document counts or a completed inventory of selected documents.
|
| 866 |
+
|
| 867 |
+
The corpus configuration records source license labels and provenance.
|
| 868 |
+
Those labels are not blanket permission to redistribute all underlying content.
|
| 869 |
+
See the complete corpus contract (`../configs/corpus.json` in the original V2 documentation tree).
|
| 870 |
+
|
| 871 |
+
### 4.2 Filtering and split assignment
|
| 872 |
+
|
| 873 |
+
Documents must contain text, meet the 200-character minimum, and remain within
|
| 874 |
+
200,000 UTF-8 bytes. Filters reject NUL characters and more than two Unicode
|
| 875 |
+
replacement characters. Documents with at least ten non-empty lines are rejected
|
| 876 |
+
when fewer than half those lines are distinct. Source-specific score and format
|
| 877 |
+
requirements are checked in addition to these shared rules.
|
| 878 |
+
|
| 879 |
+
For identity and split assignment, text is NFC-normalized and whitespace is
|
| 880 |
+
collapsed before SHA-256 hashing. The first sixteen hexadecimal hash digits,
|
| 881 |
+
modulo 10,000, assign documents as follows:
|
| 882 |
+
|
| 883 |
+
| Bucket range | Allocation |
|
| 884 |
+
| --- | --- |
|
| 885 |
+
| 0-99 | Reserved final split |
|
| 886 |
+
| 100-199 | Validation |
|
| 887 |
+
| 200-299 | Tokenizer development |
|
| 888 |
+
| 300-9,999 | Training |
|
| 889 |
+
|
| 890 |
+
These are deterministic hash allocations, not guarantees of exact byte or token
|
| 891 |
+
percentages. Model input retains the original text; identity normalization does
|
| 892 |
+
not rewrite the training text.
|
| 893 |
+
|
| 894 |
+
A cross-source window of 10,000 recent accepted document hashes suppresses
|
| 895 |
+
normalized exact duplicates. This is bounded deduplication, not full-corpus
|
| 896 |
+
near-duplicate removal. Hash splitting separates identical normalized documents
|
| 897 |
+
across roles, but does not establish benchmark decontamination.
|
| 898 |
+
|
| 899 |
+
### 4.3 Streaming, scheduling, and packing
|
| 900 |
+
|
| 901 |
+
Mac-1 reads the pinned Hugging Face sources, filters documents, tokenizes them,
|
| 902 |
+
and constructs a global batch. The live training stream follows source order;
|
| 903 |
+
unlike tokenizer fitting, it does not use a document shuffle buffer.
|
| 904 |
+
|
| 905 |
+
Source scheduling chooses the most underrepresented component using consumed
|
| 906 |
+
token offsets divided by target weights. Each source maintains its own pending
|
| 907 |
+
token buffer. Documents receive one explicit document-end token, with no
|
| 908 |
+
automatic beginning-of-document token.
|
| 909 |
+
|
| 910 |
+
A row requires 2,049 buffered tokens: 2,048 input positions and their one-token
|
| 911 |
+
shifted targets. Advancing by 2,048 preserves the final lookahead token for the
|
| 912 |
+
next row. Packed windows can cross document boundaries within a source.
|
| 913 |
+
Attention is not reset at a document-end token.
|
| 914 |
+
|
| 915 |
+
The reader is configured for four prefetched global updates and five read
|
| 916 |
+
attempts. Source exhaustion or the configured five-million-row-per-source limit
|
| 917 |
+
is an error, not a trigger to silently recycle data. Reaching 15B tokens therefore
|
| 918 |
+
depends on sufficient eligible source material remaining available.
|
| 919 |
+
|
| 920 |
+
### 4.4 Storage and token accounting
|
| 921 |
+
|
| 922 |
+
No full training corpus or token-shard collection is materialized on disk.
|
| 923 |
+
Streaming still requires RAM for reader state, token buffers, fixed validation
|
| 924 |
+
batches, and bounded prefetch. Checkpoints persist the consumed cursor and pending
|
| 925 |
+
buffer state; tokenizer samples, logs, staged inputs, and metadata are separate
|
| 926 |
+
disk uses.
|
| 927 |
+
|
| 928 |
+
| Quantity | Value / definition |
|
| 929 |
+
| --- | --- |
|
| 930 |
+
| Planned endpoint | 15,000,000,000 cumulative training positions |
|
| 931 |
+
| Positions per optimizer update | 106,496 |
|
| 932 |
+
| Consumed at this report's boundary | 1,000,103,936 |
|
| 933 |
+
| Expected full-update endpoint if geometry is unchanged | 15,000,068,096 |
|
| 934 |
+
| Expected endpoint step under that assumption | 140,851 |
|
| 935 |
+
|
| 936 |
+
Counts include boundary-token positions processed by the objective. They exclude
|
| 937 |
+
validation and generation, and do not count prefetch as consumed training.
|
| 938 |
+
They are not counts of unique words, documents, or facts. Restarting from an older
|
| 939 |
+
checkpoint can repeat computation; lineage token counts are not an accounting
|
| 940 |
+
of every token processed across failed or discarded work.
|
| 941 |
+
|
| 942 |
+
Implementation evidence: corpus (`../sml_v2/corpus.py` in the original V2 documentation tree),
|
| 943 |
+
streaming (`../sml_v2/stream.py` in the original V2 documentation tree).
|
| 944 |
+
|
| 945 |
+
## 5. Optimization and Training Schedule
|
| 946 |
+
|
| 947 |
+
### 5.1 Objective and optimizer
|
| 948 |
+
|
| 949 |
+
The objective is causal next-token cross-entropy over packed sequences:
|
| 950 |
+
|
| 951 |
+
~~~text
|
| 952 |
+
L = -(1 / N) * sum(log p(target_token | preceding_tokens))
|
| 953 |
+
~~~
|
| 954 |
+
|
| 955 |
+
All packed target positions contribute, including document boundaries. This is
|
| 956 |
+
base-model pretraining, not assistant-response-only supervision.
|
| 957 |
+
|
| 958 |
+
| Hyperparameter | Value |
|
| 959 |
+
| --- | --- |
|
| 960 |
+
| Optimizer | AdamW |
|
| 961 |
+
| Beta1 / beta2 | 0.9 / 0.95 |
|
| 962 |
+
| Epsilon | 1e-8 |
|
| 963 |
+
| Weight decay | 0.1 on matrix parameters; normalization weights excluded |
|
| 964 |
+
| Global gradient clipping | L2 norm 1.0, after distributed reduction |
|
| 965 |
+
| Peak / minimum learning rate | 3e-4 / 3e-5 |
|
| 966 |
+
| Accumulation | Four microsteps per update |
|
| 967 |
+
| Random seed | 7,337 |
|
| 968 |
+
| Schedule coordinate | Consumed training tokens |
|
| 969 |
+
|
| 970 |
+
Local gradients are averaged across accumulation microsteps in FP32. The
|
| 971 |
+
distributed weighted mean is then clipped before each replica applies its
|
| 972 |
+
optimizer update.
|
| 973 |
+
|
| 974 |
+
### 5.2 Effective batch
|
| 975 |
+
|
| 976 |
+
~~~text
|
| 977 |
+
(4 + 3 + 3 + 3) sequences/microstep
|
| 978 |
+
* 4 accumulation microsteps
|
| 979 |
+
= 52 sequences/update
|
| 980 |
+
|
| 981 |
+
52 * 2,048 = 106,496 tokens/update
|
| 982 |
+
~~~
|
| 983 |
+
|
| 984 |
+
The update contains **52 sequences**, not 208. Unequal device batches are a
|
| 985 |
+
compute-balancing choice and are reflected in the gradient weights.
|
| 986 |
+
|
| 987 |
+
### 5.3 Recorded learning-rate trajectory
|
| 988 |
+
|
| 989 |
+
The training budget was extended at 500,105,216 consumed tokens. Model,
|
| 990 |
+
optimizer, and data state were preserved; the schedule was explicitly changed.
|
| 991 |
+
This is one weight lineage, but not an uninterrupted 15B-token schedule defined
|
| 992 |
+
at initialization.
|
| 993 |
+
|
| 994 |
+
| Token interval / boundary | Learning-rate behavior |
|
| 995 |
+
| --- | --- |
|
| 996 |
+
| 0 to 5M | Linear warmup toward 3e-4 |
|
| 997 |
+
| 5M to 400M | Hold at 3e-4 |
|
| 998 |
+
| 400M to approximately 500M | Cosine decay toward 3e-5 under the original budget |
|
| 999 |
+
| 500,105,216 | Resume anchor at step 4,696; LR approximately 3e-5 |
|
| 1000 |
+
| Next 50M tokens | Linear rewarm toward 3e-4 |
|
| 1001 |
+
| Approximately 550.1M to 12B | Hold at 3e-4 |
|
| 1002 |
+
| 12B to 15B | Cosine decay toward 3e-5 |
|
| 1003 |
+
|
| 1004 |
+
The rate is evaluated at the upcoming update's ending token count, so boundaries
|
| 1005 |
+
are realized at full updates. Resuming this continuation preserves its original
|
| 1006 |
+
rewarm anchor rather than restarting warmup.
|
| 1007 |
+
|
| 1008 |
+
The scheduler is token-based, not a validation-plateau controller. No controlled
|
| 1009 |
+
experiment has established that this schedule is optimal. The early decay and
|
| 1010 |
+
rewarm must remain visible when interpreting learning curves.
|
| 1011 |
+
|
| 1012 |
+
## 6. Distributed Execution
|
| 1013 |
+
|
| 1014 |
+
### 6.1 Hardware and rank assignment
|
| 1015 |
+
|
| 1016 |
+
Training uses one M3 Ultra Mac Studio and three M4 Max Mac Studios.
|
| 1017 |
+
The logical JACCL ring is Mac-1 -> Mac-2 -> Mac-4 -> Mac-3 -> Mac-1.
|
| 1018 |
+
|
| 1019 |
+
| Logical rank | Physical host | Chip family | Microbatch | Sequences/update | Tokens/update |
|
| 1020 |
+
| ---: | --- | --- | ---: | ---: | ---: |
|
| 1021 |
+
| 0 | Mac-1 | M3 Ultra | 4 | 16 | 32,768 |
|
| 1022 |
+
| 1 | Mac-2 | M4 Max | 3 | 12 | 24,576 |
|
| 1023 |
+
| 2 | Mac-4 | M4 Max | 3 | 12 | 24,576 |
|
| 1024 |
+
| 3 | Mac-3 | M4 Max | 3 | 12 | 24,576 |
|
| 1025 |
+
| **Total** | | | **13** | **52** | **106,496** |
|
| 1026 |
+
|
| 1027 |
+
This is replicated data-parallel training, not model sharding. Each Mac stores
|
| 1028 |
+
the complete model and optimizer state and computes on a disjoint slice of the
|
| 1029 |
+
global batch. Four physical Thunderbolt links form the ring.
|
| 1030 |
+
|
| 1031 |
+
### 6.2 One optimizer update
|
| 1032 |
+
|
| 1033 |
+
1. Mac-1 constructs and distributes the global input/target arrays.
|
| 1034 |
+
2. Each rank selects its assigned sequences and performs four local microsteps.
|
| 1035 |
+
3. Accumulated FP32 gradients are weighted by local batch contribution.
|
| 1036 |
+
4. Distributed gradient reduction produces the global mean.
|
| 1037 |
+
5. Each replica clips that mean and applies the same AdamW update.
|
| 1038 |
+
6. When due, ranks coordinate evaluation, generation, or checkpoint commitment.
|
| 1039 |
+
|
| 1040 |
+
For local mean gradients g_r and microbatch sizes b_r, the intended gradient is:
|
| 1041 |
+
|
| 1042 |
+
~~~text
|
| 1043 |
+
g_global = sum(b_r * g_r) / sum(b_r)
|
| 1044 |
+
~~~
|
| 1045 |
+
|
| 1046 |
+
Before MLX's equal-rank averaging operation, the implementation multiplies each
|
| 1047 |
+
local mean by world_size * b_r / sum(b_r). Equal accumulation counts and full
|
| 1048 |
+
sequence lengths make sequence weighting equivalent to token weighting here.
|
| 1049 |
+
A plain unweighted mean of the four ranks would overrepresent the smaller batches.
|
| 1050 |
+
|
| 1051 |
+
### 6.3 Data plane and control plane
|
| 1052 |
+
|
| 1053 |
+
Tensor transfers use JACCL over Thunderbolt RDMA. Wired SSH and loopback-only
|
| 1054 |
+
coordinator tunnels carry control traffic; Mac-4's wired control path is relayed
|
| 1055 |
+
through Mac-2. Hugging Face streaming uses the host's internet connection and is
|
| 1056 |
+
separate from inter-Mac tensor communication.
|
| 1057 |
+
|
| 1058 |
+
The launcher verifies physical identities, ring links, RDMA, wired control
|
| 1059 |
+
connectivity, and synchronized inputs. This is custom orchestration around MLX,
|
| 1060 |
+
not an unmodified upstream example. Existing cluster/network helpers outside the
|
| 1061 |
+
dedicated model directory remain runtime dependencies.
|
| 1062 |
+
|
| 1063 |
+
### 6.4 Kernels and performance boundaries
|
| 1064 |
+
|
| 1065 |
+
The configured compute path uses compiled backward computation, MLX fast
|
| 1066 |
+
attention, a custom Metal cross-entropy implementation, and packed Metal SwiGLU.
|
| 1067 |
+
Cross-entropy reductions and optimizer-related state retain FP32 precision.
|
| 1068 |
+
|
| 1069 |
+
Gradient groups use a 32 MiB reduction setting. The trainer explicitly
|
| 1070 |
+
materializes gradients before communication; this report does not claim
|
| 1071 |
+
communication/backward overlap. The implementation's collective stream setting
|
| 1072 |
+
does not mean that model forward/backward computation runs on the CPU.
|
| 1073 |
+
|
| 1074 |
+
No isolated speedup is assigned to any kernel without a matched measurement.
|
| 1075 |
+
An earlier architecture's throughput is not a controlled baseline for this
|
| 1076 |
+
20-layer, 2,048-context model.
|
| 1077 |
+
|
| 1078 |
+
Implementation evidence: trainer (`../sml_v2/pretrain.py` in the original V2 documentation tree),
|
| 1079 |
+
launcher (`../sml_v2/launch.py` in the original V2 documentation tree).
|
| 1080 |
+
|
| 1081 |
+
## 7. Checkpointing and Reproducibility
|
| 1082 |
+
|
| 1083 |
+
### 7.1 What a resumable checkpoint preserves
|
| 1084 |
+
|
| 1085 |
+
Checkpoint bundles preserve model weights, FP32 master weights and optimizer
|
| 1086 |
+
state, update/token counters, recipe and artifact contracts, validation state,
|
| 1087 |
+
and consumed stream state. Replica hashes and data-cursor checks accompany
|
| 1088 |
+
commitment. Writes are staged before a completed bundle becomes the new pointer.
|
| 1089 |
+
|
| 1090 |
+
The stream cursor corresponds to consumed work, not the producer's most advanced
|
| 1091 |
+
prefetched position. Unconsumed queued batches are reconstructed after resume.
|
| 1092 |
+
Underlying readers may reread remote content to recover a position; that alone
|
| 1093 |
+
does not establish repeated training exposure.
|
| 1094 |
+
|
| 1095 |
+
### 7.2 Selection and retention
|
| 1096 |
+
|
| 1097 |
+
The latest pointer identifies the newest committed resume point. The best pointer
|
| 1098 |
+
identifies the lowest aggregate validation loss observed under the fixed contract.
|
| 1099 |
+
These may refer to the same bundle.
|
| 1100 |
+
|
| 1101 |
+
Routine saves are requested every 10M tokens, with additional saves for new
|
| 1102 |
+
validation bests, clean stops, and completion. The configured retention policy
|
| 1103 |
+
keeps two recent checkpoints and protects the best, so a distinct older best can
|
| 1104 |
+
require an additional bundle. Logs and staged job inputs have separate storage
|
| 1105 |
+
lifetimes.
|
| 1106 |
+
|
| 1107 |
+
An 8 GiB reserve, plus estimated checkpoint requirements, guards saving. Failed
|
| 1108 |
+
or interrupted work after the last committed bundle is not guaranteed recoverable.
|
| 1109 |
+
The system does not automatically restart failed training.
|
| 1110 |
+
|
| 1111 |
+
### 7.3 Reproduction contract
|
| 1112 |
+
|
| 1113 |
+
The job snapshots recipe, corpus definition, tokenizer, and code inputs and
|
| 1114 |
+
verifies copies and package versions across hosts. Resume validation uses
|
| 1115 |
+
artifact contracts rather than assuming that files with the same name are
|
| 1116 |
+
equivalent.
|
| 1117 |
+
|
| 1118 |
+
The dependency specification pins MLX and mlx-metal 0.32.2, NumPy 2.4.2,
|
| 1119 |
+
datasets 4.5.0, huggingface-hub 1.4.0, and tokenizers 0.22.2. The project requires
|
| 1120 |
+
Python 3.11 or later. Exact future release reproduction should additionally
|
| 1121 |
+
retain observed interpreter, macOS, hardware, and networking inventories.
|
| 1122 |
+
|
| 1123 |
+
These controls improve traceability; they do not constitute a claim of
|
| 1124 |
+
bitwise-identical execution across different machines or software releases.
|
| 1125 |
+
Operating instructions remain in the project README (`../README.md` in the original V2 documentation tree).
|
| 1126 |
+
|
| 1127 |
+
## 8. Evaluation Methodology
|
| 1128 |
+
|
| 1129 |
+
### 8.1 Fixed reference loss
|
| 1130 |
+
|
| 1131 |
+
The validation stream materializes sixteen batches per source, each containing
|
| 1132 |
+
two sequences of 2,048 targets. This yields:
|
| 1133 |
+
|
| 1134 |
+
| Quantity | Count |
|
| 1135 |
+
| --- | ---: |
|
| 1136 |
+
| Source components | 4 |
|
| 1137 |
+
| Batches per component | 16 |
|
| 1138 |
+
| Total batches | 64 |
|
| 1139 |
+
| Target positions per component | 65,536 |
|
| 1140 |
+
| Total target positions | 262,144 |
|
| 1141 |
+
|
| 1142 |
+
Per-source cross-entropies are combined using the training mixture's 55/25/10/10
|
| 1143 |
+
weights. Because the source sample sizes are equal but weights differ, this is
|
| 1144 |
+
not a simple equal average across all batches.
|
| 1145 |
+
|
| 1146 |
+
~~~text
|
| 1147 |
+
L_reference = 0.55 * L_web + 0.25 * L_dclm
|
| 1148 |
+
+ 0.10 * L_wiki + 0.10 * L_cosmopedia
|
| 1149 |
+
|
| 1150 |
+
reference_perplexity = exp(L_reference)
|
| 1151 |
+
~~~
|
| 1152 |
+
|
| 1153 |
+
Validation runs every 25M consumed tokens, approximately every 235 updates at
|
| 1154 |
+
the current batch geometry. The reference fingerprint remains unchanged across
|
| 1155 |
+
the documented continuation:
|
| 1156 |
+
|
| 1157 |
+
~~~text
|
| 1158 |
+
99e7d4417061db5a70138701694ad5577d0f9ff0d0fc729ddc6beff06b3a7081
|
| 1159 |
+
~~~
|
| 1160 |
+
|
| 1161 |
+
These fixed batches support longitudinal comparisons within this model's run.
|
| 1162 |
+
They are small relative to the corpus and do not quantify uncertainty across
|
| 1163 |
+
all possible held-out documents.
|
| 1164 |
+
|
| 1165 |
+
### 8.2 Generation probes
|
| 1166 |
+
|
| 1167 |
+
Five fixed raw-text prefixes are sampled every 50M tokens:
|
| 1168 |
+
|
| 1169 |
+
| Probe | Full prefix |
|
| 1170 |
+
| --- | --- |
|
| 1171 |
+
| Narrative continuation | The library was closed for repairs, so Maya decided to |
|
| 1172 |
+
| Basic explanation | Plants need sunlight because |
|
| 1173 |
+
| Learning advice | A useful way to remember a new word is to |
|
| 1174 |
+
| Contextual continuation | The train arrived late because of heavy snow. When the passengers stepped outside, |
|
| 1175 |
+
| Basic explanation | Clean drinking water is important because |
|
| 1176 |
+
|
| 1177 |
+
The recorded comparison path uses greedy decoding, temperature 0, at most 64
|
| 1178 |
+
new tokens, and the model's own frozen tokenizer. It uses cached autoregressive
|
| 1179 |
+
generation and stops at document end. It does not apply a repetition penalty
|
| 1180 |
+
or top-k sampling.
|
| 1181 |
+
|
| 1182 |
+
These settings deliberately make comparisons stable. Greedy failure cases are
|
| 1183 |
+
not the only possible outputs, but changing temperature does not by itself
|
| 1184 |
+
establish that a factual or contextual weakness is solved. Probes are qualitative
|
| 1185 |
+
development diagnostics with no reported automatic capability score.
|
| 1186 |
+
|
| 1187 |
+
### 8.3 Independent evaluation still to perform
|
| 1188 |
+
|
| 1189 |
+
Before any final capability claim, freeze candidate weights and publish the
|
| 1190 |
+
evaluation settings, prompts or task versions, decoding parameters, and scoring
|
| 1191 |
+
rules. The intended evaluation record should separate held-out language modeling,
|
| 1192 |
+
factual recall, use of supplied context, narrative coherence, and repetition.
|
| 1193 |
+
|
| 1194 |
+
No downstream benchmark score, human-review pass rate, or untouched final-split
|
| 1195 |
+
result has been established in this report. Future comparisons must use documented
|
| 1196 |
+
protocols and identify possible training-data overlap.
|
| 1197 |
+
|
| 1198 |
+
## 9. Interim Results
|
| 1199 |
+
|
| 1200 |
+
### 9.1 Reference-loss milestones
|
| 1201 |
+
|
| 1202 |
+
| Step | Consumed training tokens | Reference loss | Perplexity | Context |
|
| 1203 |
+
| ---: | ---: | ---: | ---: | --- |
|
| 1204 |
+
| 235 | 25,026,560 | 5.7345 | 309.37 | Early training |
|
| 1205 |
+
| 4,696 | 500,105,216 | 3.3536 | 28.61 | Budget-extension boundary |
|
| 1206 |
+
| 5,165 | 550,051,840 | 3.4327 | 30.96 | Near the end of rewarm |
|
| 1207 |
+
| 7,982 | 850,051,072 | 3.3160 | 27.55 | Continued pretraining |
|
| 1208 |
+
| 9,156 | 975,077,376 | 3.2832 | 26.66 | Continued pretraining |
|
| 1209 |
+
| **9,391** | **1,000,103,936** | **3.2812** | **26.61** | **Reporting cutoff** |
|
| 1210 |
+
|
| 1211 |
+
All logged evaluations through the cutoff are retained in the
|
| 1212 |
+
validation CSV (`tables/validation_through_0009391.csv` in the original V2 documentation tree), including repeated
|
| 1213 |
+
observations if present. The table above selects milestones, not every event.
|
| 1214 |
+
Loss and perplexity retain their logged rounding.
|
| 1215 |
+
|
| 1216 |
+
Loss increased during rewarm and subsequently fell below the earlier boundary's
|
| 1217 |
+
value. This is a temporal association with the schedule change, not a controlled
|
| 1218 |
+
causal result. More consumed data and more optimizer updates also changed.
|
| 1219 |
+
|
| 1220 |
+
### 9.2 Per-source reference loss
|
| 1221 |
+
|
| 1222 |
+
| Source | Step 4,696 | Step 9,391 |
|
| 1223 |
+
| --- | ---: | ---: |
|
| 1224 |
+
| Web | 3.4531 | 3.3884 |
|
| 1225 |
+
| DCLM | 3.6497 | 3.5756 |
|
| 1226 |
+
| Wiki | 2.8654 | 2.7904 |
|
| 1227 |
+
| Cosmopedia | 2.5543 | 2.4468 |
|
| 1228 |
+
|
| 1229 |
+
All four fixed source references improved between these boundaries. Differences
|
| 1230 |
+
between sources reflect different reference distributions as well as learned
|
| 1231 |
+
prediction; a lower source loss is not a ranking of factual competence.
|
| 1232 |
+
|
| 1233 |
+
### 9.3 Throughput
|
| 1234 |
+
|
| 1235 |
+
As one identifiable production observation, step 9,280 logged **12,889 tokens/s**
|
| 1236 |
+
for its reporting interval and **13,570 run tokens/s**. These are aggregate
|
| 1237 |
+
cluster training-position rates, not inference generation speed and not a
|
| 1238 |
+
fourfold sum of independently reported rank rates.
|
| 1239 |
+
|
| 1240 |
+
The run counter describes that worker invocation's timed training loop, not all
|
| 1241 |
+
project wall time. Startup, interrupted sessions, and external preparation must
|
| 1242 |
+
be accounted for separately before reporting total training duration or cost.
|
| 1243 |
+
A final throughput summary, distribution of step times, peak-memory audit, and
|
| 1244 |
+
energy measurement remain pending. No model FLOP utilization is claimed.
|
| 1245 |
+
|
| 1246 |
+
### 9.4 Qualitative limitations observed so far
|
| 1247 |
+
|
| 1248 |
+
The logged prefixes elicit grammatical fragments but also repetitive clauses,
|
| 1249 |
+
topic drift, and factual errors. At step 5,165, for example, the word-learning
|
| 1250 |
+
prefix began with useful advice about using a word in a sentence and then
|
| 1251 |
+
repeated that idea. The plant and water explanations were not dependable.
|
| 1252 |
+
|
| 1253 |
+
Improving reference loss is therefore evidence of better prediction on those
|
| 1254 |
+
reference batches, not proof of reliable open-ended generation. A final report
|
| 1255 |
+
should retain complete successes and failures rather than presenting only
|
| 1256 |
+
favorable excerpts. The full probe prefixes and generation settings above make
|
| 1257 |
+
that review reproducible.
|
| 1258 |
+
|
| 1259 |
+
## 10. Post-Training and Release Status
|
| 1260 |
+
|
| 1261 |
+
| Item | Status at this report boundary |
|
| 1262 |
+
| --- | --- |
|
| 1263 |
+
| Tokenizer fitting and development audit | Completed |
|
| 1264 |
+
| From-scratch pretraining | In progress |
|
| 1265 |
+
| 15B-token endpoint | Planned, not reached |
|
| 1266 |
+
| Final pretrained checkpoint selection | Pending |
|
| 1267 |
+
| Instruction fine-tuning for these weights | Not reported |
|
| 1268 |
+
| Preference optimization / reinforcement learning | Not reported |
|
| 1269 |
+
| Independent downstream evaluation | Pending |
|
| 1270 |
+
| Export parity and fresh-download validation of final weights | Pending |
|
| 1271 |
+
| Public final-weight release | Pending |
|
| 1272 |
+
|
| 1273 |
+
The prepared [OpenSML repository](https://huggingface.co/wzebrowski/OpenSML) is
|
| 1274 |
+
private at this revision. Its model card uses Apache-2.0 metadata for the planned
|
| 1275 |
+
release. That does not relicense upstream datasets or remove obligations on
|
| 1276 |
+
third-party code and content.
|
| 1277 |
+
|
| 1278 |
+
A final export should include weights, matching tokenizer and configuration,
|
| 1279 |
+
inference instructions, provenance, evaluation settings, and a reproducible
|
| 1280 |
+
loading/generation check. Compatibility with an inference library should be
|
| 1281 |
+
verified rather than inferred from the model's general Transformer architecture.
|
| 1282 |
+
|
| 1283 |
+
No existing fine-tuned checkpoint from an earlier model is presented as a
|
| 1284 |
+
post-trained version of OpenSML-152M.
|
| 1285 |
+
|
| 1286 |
+
## 11. Limitations and Intended Use
|
| 1287 |
+
|
| 1288 |
+
- **Incomplete training:** the reported snapshot covers approximately 1B tokens, not the full 15B target.
|
| 1289 |
+
- **Generation reliability:** repetitive and incorrect text remains an observed failure mode.
|
| 1290 |
+
- **Development reuse:** reference batches and fixed prompts have been inspected repeatedly.
|
| 1291 |
+
- **Data coverage:** educational prose does not guarantee balanced coverage of every domain or language.
|
| 1292 |
+
- **Deduplication limits:** a bounded exact-hash window does not remove all duplicates, paraphrases, or benchmark overlap.
|
| 1293 |
+
- **Sequence boundaries:** packing allows attention across document boundaries without an attention reset.
|
| 1294 |
+
- **Source order:** live streaming does not perform the seeded document shuffle used for tokenizer fitting.
|
| 1295 |
+
- **Schedule confounding:** the recorded early decay and rewarm prevent describing this as a single unchanged training schedule.
|
| 1296 |
+
- **Uncontrolled design choices:** architecture, tokenizer, and data choices have not been individually validated by matched ablations.
|
| 1297 |
+
- **Infrastructure dependence:** wired routing, tunnels, and project-specific collective safeguards add operational complexity.
|
| 1298 |
+
- **Unmeasured efficiency:** no end-to-end energy result, MFU measurement, or final total training cost is reported.
|
| 1299 |
+
|
| 1300 |
+
Current intended use is research into small-model training and text completion.
|
| 1301 |
+
This base model should not be treated as a reliable assistant or a source of
|
| 1302 |
+
high-stakes factual advice.
|
| 1303 |
+
|
| 1304 |
+
## 12. Evidence and Completion Checklist
|
| 1305 |
+
|
| 1306 |
+
### 12.1 Local evidence map
|
| 1307 |
+
|
| 1308 |
+
| Claim group | Primary records |
|
| 1309 |
+
| --- | --- |
|
| 1310 |
+
| Architecture and parameter construction | Model implementation (`../sml_v2/model.py` in the original V2 documentation tree) |
|
| 1311 |
+
| Optimizer and precision | Precision implementation (`../sml_v2/precision.py` in the original V2 documentation tree) |
|
| 1312 |
+
| Source weights, fields, revisions | Corpus configuration (`../configs/corpus.json` in the original V2 documentation tree) |
|
| 1313 |
+
| Filtering, identity, split rules | Corpus implementation (`../sml_v2/corpus.py` in the original V2 documentation tree) |
|
| 1314 |
+
| Stream cursors and packing | Streaming implementation (`../sml_v2/stream.py` in the original V2 documentation tree) |
|
| 1315 |
+
| Tokenizer construction and audits | Manifest (`../tokenizer/bytebpe32k_v1/manifest.json` in the original V2 documentation tree), audit (`../tokenizer/bytebpe32k_v1/report.json` in the original V2 documentation tree) |
|
| 1316 |
+
| Live continuation settings | Recorded job recipe (`../runs/full_15b_v1/jobs/20260918_085811_b4e5c849/input/recipe.json` in the original V2 documentation tree) |
|
| 1317 |
+
| Distributed updates and evaluation | Trainer (`../sml_v2/pretrain.py` in the original V2 documentation tree), launcher (`../sml_v2/launch.py` in the original V2 documentation tree) |
|
| 1318 |
+
| Reported validation observations | CSV (`tables/validation_through_0009391.csv` in the original V2 documentation tree), provenance (`tables/validation_through_0009391.json` in the original V2 documentation tree) |
|
| 1319 |
+
| Implementation ancestry | Code provenance (`../provenance.json` in the original V2 documentation tree) |
|
| 1320 |
+
|
| 1321 |
+
The evidence table references the local project layout. A future published report
|
| 1322 |
+
must package durable copies or revision-pinned links; local run directories alone
|
| 1323 |
+
are not a public reproduction artifact.
|
| 1324 |
+
|
| 1325 |
+
The companion evidence exporter (`../scripts/export_report_evidence.py` in the original V2 documentation tree) reads
|
| 1326 |
+
logs without loading a model, contacting workers, or changing training. It
|
| 1327 |
+
records source-log hashes, line numbers, and the exported table's hash. Active
|
| 1328 |
+
logs grow, so their hashes identify the snapshot read rather than an immutable
|
| 1329 |
+
future file.
|
| 1330 |
+
|
| 1331 |
+
### 12.2 Reporting approach and attribution
|
| 1332 |
+
|
| 1333 |
+
The organization was informed by the transparent reporting approach in
|
| 1334 |
+
[PetitGPT's technical report](https://github.com/yangqi0/petitgpt/blob/53a5bb33052fa8092987eacc1047e040a7c5ce30/docs/petitgpt-v1/TECHNICAL_REPORT.md).
|
| 1335 |
+
The prose, model configuration, implementation description, and measurements
|
| 1336 |
+
here describe this project. PetitGPT's results are not imported as our results
|
| 1337 |
+
or used as matched baselines.
|
| 1338 |
+
|
| 1339 |
+
The system builds on established Transformer methods, MLX, Hugging Face tooling,
|
| 1340 |
+
and the cited data sources. Component-specific attribution and inherited
|
| 1341 |
+
implementation history should remain attached to the released code.
|
| 1342 |
+
|
| 1343 |
+
### 12.3 Items required for a completed report
|
| 1344 |
+
|
| 1345 |
+
- [ ] Freeze the final training history, schedule, source consumption, and selected checkpoint.
|
| 1346 |
+
- [ ] Publish the complete loss curve with restart and schedule boundaries identified.
|
| 1347 |
+
- [ ] Summarize sustained throughput, memory, elapsed time, and measurement scope.
|
| 1348 |
+
- [ ] Evaluate the reserved final split without using it for checkpoint selection.
|
| 1349 |
+
- [ ] Run independently specified capability and generation evaluations.
|
| 1350 |
+
- [ ] Publish complete qualitative examples with prompt and decoding settings.
|
| 1351 |
+
- [ ] Document any post-training experiments separately from base-model results.
|
| 1352 |
+
- [ ] Verify exported weights, tokenizer, loading, and generation from a fresh download.
|
| 1353 |
+
- [ ] Package durable evidence and review dataset/code attribution before release.
|
| 1354 |
+
|
| 1355 |
+
Until those items are completed, this document is a detailed methods and interim
|
| 1356 |
+
results report, not a final model-quality claim.
|
TRAINING_RECORDS_MANIFEST.json
ADDED
|
@@ -0,0 +1,847 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"scope": "Original selected SFT lineage inputs, recipe code, logs and evaluation receipts; no weights, optimizer tensors or complete pretraining cache. Historical V2 source names are preserved.",
|
| 3 |
+
"files": [
|
| 4 |
+
{
|
| 5 |
+
"path": "exports/opensml-150m/SOURCE_NOTICE.md",
|
| 6 |
+
"bytes": 1717,
|
| 7 |
+
"sha256": "f23e5289cac871e325fd06edc4b538167e8c4cb737491adabc591d1535810c1d"
|
| 8 |
+
},
|
| 9 |
+
{
|
| 10 |
+
"path": "exports/opensml-150m/THIRD_PARTY_NOTICES.md",
|
| 11 |
+
"bytes": 5918,
|
| 12 |
+
"sha256": "7d5e0edccfe69bed72de19aa6a004256262da3c271e8397e7ba72ec67767948f"
|
| 13 |
+
},
|
| 14 |
+
{
|
| 15 |
+
"path": "sml-mlx-v2/experiments/public_repair_384_v1/README.txt",
|
| 16 |
+
"bytes": 5653,
|
| 17 |
+
"sha256": "3deb2a3f65b5c42a936a5cb9fd2e99914a1d09cdb9729d799750216e29edc6e1"
|
| 18 |
+
},
|
| 19 |
+
{
|
| 20 |
+
"path": "sml-mlx-v2/experiments/public_repair_384_v1/audits/checkpoint512_v1/analyze.py",
|
| 21 |
+
"bytes": 11931,
|
| 22 |
+
"sha256": "0c086b2082ea257c7026b9f90f72a2b7d699279f53eda0f1474b97cb2e180b31"
|
| 23 |
+
},
|
| 24 |
+
{
|
| 25 |
+
"path": "sml-mlx-v2/experiments/public_repair_384_v1/audits/checkpoint512_v1/arc_challenge_changed_rows.json",
|
| 26 |
+
"bytes": 319279,
|
| 27 |
+
"sha256": "e02a6b6bd21e31d023f8537adb710b146dc52dfa5e8bcd6b2f3ace21c8cc6be3"
|
| 28 |
+
},
|
| 29 |
+
{
|
| 30 |
+
"path": "sml-mlx-v2/experiments/public_repair_384_v1/audits/checkpoint512_v1/arc_easy_changed_rows.json",
|
| 31 |
+
"bytes": 664901,
|
| 32 |
+
"sha256": "eda40bc6ca822381dc78c993e9726c0ce3f9b8b610a8fe19e8cee1a365a8d4e9"
|
| 33 |
+
},
|
| 34 |
+
{
|
| 35 |
+
"path": "sml-mlx-v2/experiments/public_repair_384_v1/audits/checkpoint512_v1/build_report.py",
|
| 36 |
+
"bytes": 7558,
|
| 37 |
+
"sha256": "1a157b7890ef1d84009f5d2e29131da3f574cae42a9640cf88cee8423321b70e"
|
| 38 |
+
},
|
| 39 |
+
{
|
| 40 |
+
"path": "sml-mlx-v2/experiments/public_repair_384_v1/audits/checkpoint512_v1/hellaswag_changed_rows.json",
|
| 41 |
+
"bytes": 564949,
|
| 42 |
+
"sha256": "cc6ca7f8ffa4c34955ad522fbb8c19aa205bcaadafe7c2e001dcdafaafb18c0d"
|
| 43 |
+
},
|
| 44 |
+
{
|
| 45 |
+
"path": "sml-mlx-v2/experiments/public_repair_384_v1/audits/checkpoint512_v1/ifeval_all_annotated.json",
|
| 46 |
+
"bytes": 1467781,
|
| 47 |
+
"sha256": "f1c35030244ccfad6c33817729e1403978803dc4a0e076be7dba6fa6f74d0f4c"
|
| 48 |
+
},
|
| 49 |
+
{
|
| 50 |
+
"path": "sml-mlx-v2/experiments/public_repair_384_v1/audits/checkpoint512_v1/piqa_changed_rows.json",
|
| 51 |
+
"bytes": 81333,
|
| 52 |
+
"sha256": "e41ed6e8793acb2eb38235368b5fc11935286d289b451aee97dcf05ac0de3e39"
|
| 53 |
+
},
|
| 54 |
+
{
|
| 55 |
+
"path": "sml-mlx-v2/experiments/public_repair_384_v1/audits/checkpoint512_v1/public_dev_changes.json",
|
| 56 |
+
"bytes": 220329,
|
| 57 |
+
"sha256": "8064c6650b7957f2bf0a429fbe5aa05488225ffc961d9f4cf1754199239bb739"
|
| 58 |
+
},
|
| 59 |
+
{
|
| 60 |
+
"path": "sml-mlx-v2/experiments/public_repair_384_v1/audits/checkpoint512_v1/receipt.json",
|
| 61 |
+
"bytes": 5295,
|
| 62 |
+
"sha256": "31d3b6e7f99da6d92cdba7a5e41dfe976e4722311c4628db44bc8c8b661e9e01"
|
| 63 |
+
},
|
| 64 |
+
{
|
| 65 |
+
"path": "sml-mlx-v2/experiments/public_repair_384_v1/audits/checkpoint512_v1/summary.json",
|
| 66 |
+
"bytes": 37976,
|
| 67 |
+
"sha256": "c13a62d05d415828981bccc6cf23112e918e3a12e4b0016c62fcfc86a173cc52"
|
| 68 |
+
},
|
| 69 |
+
{
|
| 70 |
+
"path": "sml-mlx-v2/experiments/public_repair_384_v1/audits/next_route_20261001/analyze.py",
|
| 71 |
+
"bytes": 5199,
|
| 72 |
+
"sha256": "45784c21764aaefd9f5f8d21fb67445cc73c073210358006b1d097cded7e17b0"
|
| 73 |
+
},
|
| 74 |
+
{
|
| 75 |
+
"path": "sml-mlx-v2/experiments/public_repair_384_v1/audits/next_route_20261001/findings.json",
|
| 76 |
+
"bytes": 10493,
|
| 77 |
+
"sha256": "3c6b0842660c1e66dc9a3f2ebf1712bf4c824302ee560e6a4300fbd24b1392e1"
|
| 78 |
+
},
|
| 79 |
+
{
|
| 80 |
+
"path": "sml-mlx-v2/experiments/public_repair_384_v1/audits/next_route_20261001/probe.py",
|
| 81 |
+
"bytes": 9260,
|
| 82 |
+
"sha256": "a1494c32dea72810cc86702b16b838e4c78bd9d3f01fa45d088f15b6fd63ac78"
|
| 83 |
+
},
|
| 84 |
+
{
|
| 85 |
+
"path": "sml-mlx-v2/experiments/public_repair_384_v1/audits/next_route_20261001/sampling.json",
|
| 86 |
+
"bytes": 236002,
|
| 87 |
+
"sha256": "daeae2df4c849dd0d38e15b88b576edc2a90f5f51c6f3768e6ed5d7c9a653764"
|
| 88 |
+
},
|
| 89 |
+
{
|
| 90 |
+
"path": "sml-mlx-v2/experiments/public_repair_384_v1/benchmarks/public-repair-384-plus-128/ifeval/integrity.json",
|
| 91 |
+
"bytes": 161,
|
| 92 |
+
"sha256": "e76134f1a82f5f456056baf463c16e6a81a15f170c9b3d847327d11c3087085e"
|
| 93 |
+
},
|
| 94 |
+
{
|
| 95 |
+
"path": "sml-mlx-v2/experiments/public_repair_384_v1/benchmarks/public-repair-384-plus-128/ifeval/manifest.json",
|
| 96 |
+
"bytes": 172290,
|
| 97 |
+
"sha256": "7c9e9627a22d4862193817a987d5060704b5a125dc285b892a4c4f0dd48c8b2a"
|
| 98 |
+
},
|
| 99 |
+
{
|
| 100 |
+
"path": "sml-mlx-v2/experiments/public_repair_384_v1/benchmarks/public-repair-384-plus-128/ifeval/records.jsonl",
|
| 101 |
+
"bytes": 2278523,
|
| 102 |
+
"sha256": "4b1a7c5ce69cde554b2b07dfefe26aa8fc003fe2eece3cb3f7cac6fe9cbaeff2"
|
| 103 |
+
},
|
| 104 |
+
{
|
| 105 |
+
"path": "sml-mlx-v2/experiments/public_repair_384_v1/benchmarks/public-repair-384-plus-128/ifeval/summary.json",
|
| 106 |
+
"bytes": 615,
|
| 107 |
+
"sha256": "6d5f3a88e0afd009b9f4fd527e7edb961f230678e0bffad3888601ea570d67b6"
|
| 108 |
+
},
|
| 109 |
+
{
|
| 110 |
+
"path": "sml-mlx-v2/experiments/public_repair_384_v1/benchmarks/public-repair-384-plus-128/multiple-choice/integrity.json",
|
| 111 |
+
"bytes": 163,
|
| 112 |
+
"sha256": "c5059de1980e9abaa6f033e307eb57d98047cf002ae0d1c1d0318a247df3d0b8"
|
| 113 |
+
},
|
| 114 |
+
{
|
| 115 |
+
"path": "sml-mlx-v2/experiments/public_repair_384_v1/benchmarks/public-repair-384-plus-128/multiple-choice/manifest.json",
|
| 116 |
+
"bytes": 22453,
|
| 117 |
+
"sha256": "e9e35c43bb110f11c1190f9110aee455ffa61cc3a1abfdfc5985d72efb6cc8db"
|
| 118 |
+
},
|
| 119 |
+
{
|
| 120 |
+
"path": "sml-mlx-v2/experiments/public_repair_384_v1/benchmarks/public-repair-384-plus-128/multiple-choice/records.jsonl",
|
| 121 |
+
"bytes": 8905350,
|
| 122 |
+
"sha256": "58c4fc6c5cf830f345b06d4a75f0a3078171e9a28a595c2bf4e64455c0ec4184"
|
| 123 |
+
},
|
| 124 |
+
{
|
| 125 |
+
"path": "sml-mlx-v2/experiments/public_repair_384_v1/benchmarks/public-repair-384-plus-128/multiple-choice/summary.json",
|
| 126 |
+
"bytes": 690,
|
| 127 |
+
"sha256": "f2a63e07b2c2db4aa2742fcb88d03ac8af4f4abb5d40092db84f2a3101243d22"
|
| 128 |
+
},
|
| 129 |
+
{
|
| 130 |
+
"path": "sml-mlx-v2/experiments/public_repair_384_v1/benchmarks/readiness/readiness_public-repair-384-plus-128_ifeval.json",
|
| 131 |
+
"bytes": 174893,
|
| 132 |
+
"sha256": "7260060b8b59a727fc4fce844bd9eac716f28b37acf0d3bc9f125b9ab8f09ad4"
|
| 133 |
+
},
|
| 134 |
+
{
|
| 135 |
+
"path": "sml-mlx-v2/experiments/public_repair_384_v1/benchmarks/readiness/readiness_public-repair-384-plus-128_multiple-choice.json",
|
| 136 |
+
"bytes": 23559,
|
| 137 |
+
"sha256": "d232fdd220cc578d75b22f8030419da9e7ac62e56ef4c70af701a8040d6d85e7"
|
| 138 |
+
},
|
| 139 |
+
{
|
| 140 |
+
"path": "sml-mlx-v2/experiments/public_repair_384_v1/config.json",
|
| 141 |
+
"bytes": 1194,
|
| 142 |
+
"sha256": "2fd560ee19aa6da5df60aab88d8fafab0114c598e46ea20a3760b31d83114922"
|
| 143 |
+
},
|
| 144 |
+
{
|
| 145 |
+
"path": "sml-mlx-v2/experiments/public_repair_384_v1/data/prepared.json",
|
| 146 |
+
"bytes": 8450457,
|
| 147 |
+
"sha256": "71090fe7bd30f9454090ec48fc92ff7af4a27a7443ec4d2b4539aef9c4c0909a"
|
| 148 |
+
},
|
| 149 |
+
{
|
| 150 |
+
"path": "sml-mlx-v2/experiments/public_repair_384_v1/readiness.json",
|
| 151 |
+
"bytes": 19316,
|
| 152 |
+
"sha256": "397585461f323b229df9e9f23366154ecf0d87c5649ea1f54623b18ced9a17c5"
|
| 153 |
+
},
|
| 154 |
+
{
|
| 155 |
+
"path": "sml-mlx-v2/experiments/public_repair_384_v1/runs/sft/contract.json",
|
| 156 |
+
"bytes": 18350,
|
| 157 |
+
"sha256": "c2333789e610b71b7b8c046ff53be78732f1829d64153f28289435632a0dbbcf"
|
| 158 |
+
},
|
| 159 |
+
{
|
| 160 |
+
"path": "sml-mlx-v2/experiments/public_repair_384_v1/runs/sft/evaluations/update_00000.json",
|
| 161 |
+
"bytes": 543743,
|
| 162 |
+
"sha256": "4bbb244cef4bfa53753877295c71a62c7a11e72ed4f1a84425a677fc9598c0e7"
|
| 163 |
+
},
|
| 164 |
+
{
|
| 165 |
+
"path": "sml-mlx-v2/experiments/public_repair_384_v1/runs/sft/evaluations/update_00064.json",
|
| 166 |
+
"bytes": 453277,
|
| 167 |
+
"sha256": "2d7b9c962208eb1bb175e111c105a05687d77b40905df9404a01d947a3a16259"
|
| 168 |
+
},
|
| 169 |
+
{
|
| 170 |
+
"path": "sml-mlx-v2/experiments/public_repair_384_v1/runs/sft/evaluations/update_00128.json",
|
| 171 |
+
"bytes": 455898,
|
| 172 |
+
"sha256": "35e20b36b4f111ac55c72211c3bfb55a2726cec51211a6544115dc6b4b0ca851"
|
| 173 |
+
},
|
| 174 |
+
{
|
| 175 |
+
"path": "sml-mlx-v2/experiments/public_repair_384_v1/runs/sft/evaluations/update_00192.json",
|
| 176 |
+
"bytes": 474855,
|
| 177 |
+
"sha256": "18793a84af62788168f3f65d9d6da0623b0faa5cc21163461025e20ba5a5b813"
|
| 178 |
+
},
|
| 179 |
+
{
|
| 180 |
+
"path": "sml-mlx-v2/experiments/public_repair_384_v1/runs/sft/evaluations/update_00256.json",
|
| 181 |
+
"bytes": 475209,
|
| 182 |
+
"sha256": "4abb56c59cd3c3363ac7fcc953043f9d52a22b4bedd4b58827c5bec4d129dd41"
|
| 183 |
+
},
|
| 184 |
+
{
|
| 185 |
+
"path": "sml-mlx-v2/experiments/public_repair_384_v1/runs/sft/finished.json",
|
| 186 |
+
"bytes": 99,
|
| 187 |
+
"sha256": "cb6ffecb12bb4015a64c3d0e23ead5ef8e46b2fd53436e211f90334a1b41f56a"
|
| 188 |
+
},
|
| 189 |
+
{
|
| 190 |
+
"path": "sml-mlx-v2/experiments/public_repair_384_v1/runs/sft/latest.json",
|
| 191 |
+
"bytes": 82,
|
| 192 |
+
"sha256": "03f0a1ae27ddeea55be00de287ac8f9838b3d89d443eb4d2345b1ad714a90107"
|
| 193 |
+
},
|
| 194 |
+
{
|
| 195 |
+
"path": "sml-mlx-v2/experiments/public_repair_384_v1/runs/sft/step_0000448_e6272c82afad/manifest.json",
|
| 196 |
+
"bytes": 561,
|
| 197 |
+
"sha256": "c84d5a09b2f21fb80ff00b709ce7bc3a0d17157248fc93509b11af7101b375bb"
|
| 198 |
+
},
|
| 199 |
+
{
|
| 200 |
+
"path": "sml-mlx-v2/experiments/public_repair_384_v1/runs/sft/step_0000448_e6272c82afad/model.safetensors.json",
|
| 201 |
+
"bytes": 560,
|
| 202 |
+
"sha256": "00e3b5bc1cf131ad80d3788ba546ea155e6a3dc7fc89dbddf4885782938d4796"
|
| 203 |
+
},
|
| 204 |
+
{
|
| 205 |
+
"path": "sml-mlx-v2/experiments/public_repair_384_v1/runs/sft/step_0000512_6972bbf9be08/manifest.json",
|
| 206 |
+
"bytes": 561,
|
| 207 |
+
"sha256": "eb254f3d11b3e40af726a7ba07a8d123f77c4271f9709bb720560203d131244e"
|
| 208 |
+
},
|
| 209 |
+
{
|
| 210 |
+
"path": "sml-mlx-v2/experiments/public_repair_384_v1/runs/sft/step_0000512_6972bbf9be08/model.safetensors.json",
|
| 211 |
+
"bytes": 561,
|
| 212 |
+
"sha256": "418784fc8da5cea97100a704f00e646d0feac8613d49b62c0d1e6baea8574c0f"
|
| 213 |
+
},
|
| 214 |
+
{
|
| 215 |
+
"path": "sml-mlx-v2/experiments/public_repair_384_v1/runs/sft/step_0000576_69e1ad1810fd/manifest.json",
|
| 216 |
+
"bytes": 561,
|
| 217 |
+
"sha256": "fdb1cbf6178a54ad671472ce95a003ce53c58872d9c33a48e8de783653b82f19"
|
| 218 |
+
},
|
| 219 |
+
{
|
| 220 |
+
"path": "sml-mlx-v2/experiments/public_repair_384_v1/runs/sft/step_0000576_69e1ad1810fd/model.safetensors.json",
|
| 221 |
+
"bytes": 561,
|
| 222 |
+
"sha256": "c1826e8f9f9dde192515bde18c80b1b4a15d0e13007f11751f9beb0573d22e99"
|
| 223 |
+
},
|
| 224 |
+
{
|
| 225 |
+
"path": "sml-mlx-v2/experiments/public_repair_384_v1/runs/sft/step_0000640_c0d26296ef71/manifest.json",
|
| 226 |
+
"bytes": 561,
|
| 227 |
+
"sha256": "c8295d027fbe49a0db971f4473b4f21bf313009db92cd54c0ff40ee019f1cfbc"
|
| 228 |
+
},
|
| 229 |
+
{
|
| 230 |
+
"path": "sml-mlx-v2/experiments/public_repair_384_v1/runs/sft/step_0000640_c0d26296ef71/model.safetensors.json",
|
| 231 |
+
"bytes": 561,
|
| 232 |
+
"sha256": "266b4501faad19f123268121f392469564d322f044c3e6b8066c48a7800400e2"
|
| 233 |
+
},
|
| 234 |
+
{
|
| 235 |
+
"path": "sml-mlx-v2/experiments/public_repair_384_v1/runs/sft/training.jsonl",
|
| 236 |
+
"bytes": 44724,
|
| 237 |
+
"sha256": "6fb3e2999a57d51e3bef729be494de4b30364a2b14d2e0e886eb31821d64e9d8"
|
| 238 |
+
},
|
| 239 |
+
{
|
| 240 |
+
"path": "sml-mlx-v2/experiments/public_repair_384_v1/runs/sft/training.log",
|
| 241 |
+
"bytes": 10065,
|
| 242 |
+
"sha256": "5303ab85bbeac866fdb68141eb542158f8f24ee2df1bdf247a4575142eb9f12a"
|
| 243 |
+
},
|
| 244 |
+
{
|
| 245 |
+
"path": "sml-mlx-v2/experiments/public_repair_384_v1/scripts/benchmark.py",
|
| 246 |
+
"bytes": 2851,
|
| 247 |
+
"sha256": "1d5bbae8c2d6262e4e8326b75af941c32a7d863b7e858a7bf17df749ccd77076"
|
| 248 |
+
},
|
| 249 |
+
{
|
| 250 |
+
"path": "sml-mlx-v2/experiments/public_repair_384_v1/scripts/data.py",
|
| 251 |
+
"bytes": 13082,
|
| 252 |
+
"sha256": "36793fec90c5cd7cb504edc38c57a698115fa8ad8c51a5d97d6826403e87df38"
|
| 253 |
+
},
|
| 254 |
+
{
|
| 255 |
+
"path": "sml-mlx-v2/experiments/public_repair_384_v1/scripts/launch.py",
|
| 256 |
+
"bytes": 15205,
|
| 257 |
+
"sha256": "348215af57ffeaf85ed68b1ce60413c9b43df6c8f643515bb4ee036920ae930d"
|
| 258 |
+
},
|
| 259 |
+
{
|
| 260 |
+
"path": "sml-mlx-v2/experiments/public_repair_384_v1/scripts/test_data.py",
|
| 261 |
+
"bytes": 2566,
|
| 262 |
+
"sha256": "8d8bb35a656a989fc007df5602750b2f2a8baf6a86508aa7d82c76f75bdad275"
|
| 263 |
+
},
|
| 264 |
+
{
|
| 265 |
+
"path": "sml-mlx-v2/experiments/public_repair_384_v1/scripts/test_evaluation.py",
|
| 266 |
+
"bytes": 2517,
|
| 267 |
+
"sha256": "eacf876f9ba03412aba3cc28d0f8bdcac1097ec1a1a6e9768b1d099c40f0144d"
|
| 268 |
+
},
|
| 269 |
+
{
|
| 270 |
+
"path": "sml-mlx-v2/experiments/public_repair_384_v1/source_pins.json",
|
| 271 |
+
"bytes": 884,
|
| 272 |
+
"sha256": "a18cd8ba1ec4a68fb22725db75f3ea8138db5f18e9b1bcf2311ef26b9efc99c9"
|
| 273 |
+
},
|
| 274 |
+
{
|
| 275 |
+
"path": "sml-mlx-v2/experiments/repair512_search_v1/candidates/028-broad-public-long-stable/KEEP.json",
|
| 276 |
+
"bytes": 596,
|
| 277 |
+
"sha256": "718c641093a0acaba2ade0ce3e666221b0e89a49d17d44aefa90f43a4244f65e"
|
| 278 |
+
},
|
| 279 |
+
{
|
| 280 |
+
"path": "sml-mlx-v2/experiments/repair512_search_v1/candidates/028-broad-public-long-stable/benchmark-u256.log",
|
| 281 |
+
"bytes": 27100,
|
| 282 |
+
"sha256": "319c7b342cfccd03e57c60e06ca525d548e3191c5db2afb46039194469230a20"
|
| 283 |
+
},
|
| 284 |
+
{
|
| 285 |
+
"path": "sml-mlx-v2/experiments/repair512_search_v1/candidates/028-broad-public-long-stable/benchmarks/readiness/readiness_repair512-search-028-broad-public-long-stable-u256_ifeval.json",
|
| 286 |
+
"bytes": 174579,
|
| 287 |
+
"sha256": "b02861fcd54e8c6bef2ee61e5ff48c3817630908f1d3542452a582bd0f0d632b"
|
| 288 |
+
},
|
| 289 |
+
{
|
| 290 |
+
"path": "sml-mlx-v2/experiments/repair512_search_v1/candidates/028-broad-public-long-stable/benchmarks/readiness/readiness_repair512-search-028-broad-public-long-stable-u256_multiple-choice.json",
|
| 291 |
+
"bytes": 23244,
|
| 292 |
+
"sha256": "da11352661e8f5e932debde2eb8234061077ff877e81a1358d4f2b84dd422de7"
|
| 293 |
+
},
|
| 294 |
+
{
|
| 295 |
+
"path": "sml-mlx-v2/experiments/repair512_search_v1/candidates/028-broad-public-long-stable/benchmarks/repair512-search-028-broad-public-long-stable-u256/ifeval/integrity.json",
|
| 296 |
+
"bytes": 161,
|
| 297 |
+
"sha256": "f923ec455d9aaae428370bd7d573462d174d2719eaafce22178b8b4f7fffdd82"
|
| 298 |
+
},
|
| 299 |
+
{
|
| 300 |
+
"path": "sml-mlx-v2/experiments/repair512_search_v1/candidates/028-broad-public-long-stable/benchmarks/repair512-search-028-broad-public-long-stable-u256/ifeval/manifest.json",
|
| 301 |
+
"bytes": 171982,
|
| 302 |
+
"sha256": "af4b836f50fe1ae10a19eb4634d191c5b8b1ba9e1c3d6ae1d31bec95cdb8010c"
|
| 303 |
+
},
|
| 304 |
+
{
|
| 305 |
+
"path": "sml-mlx-v2/experiments/repair512_search_v1/candidates/028-broad-public-long-stable/benchmarks/repair512-search-028-broad-public-long-stable-u256/ifeval/records.jsonl",
|
| 306 |
+
"bytes": 1563553,
|
| 307 |
+
"sha256": "19155f279bb543d787f664f3c3f58790ebe5e976421057683ebbfd5dbb9fc638"
|
| 308 |
+
},
|
| 309 |
+
{
|
| 310 |
+
"path": "sml-mlx-v2/experiments/repair512_search_v1/candidates/028-broad-public-long-stable/benchmarks/repair512-search-028-broad-public-long-stable-u256/ifeval/summary.json",
|
| 311 |
+
"bytes": 613,
|
| 312 |
+
"sha256": "a6716e18e9bccbcc0d8c6cfbc84231f644f0b4baf5438ed4288483324850a58b"
|
| 313 |
+
},
|
| 314 |
+
{
|
| 315 |
+
"path": "sml-mlx-v2/experiments/repair512_search_v1/candidates/028-broad-public-long-stable/benchmarks/repair512-search-028-broad-public-long-stable-u256/multiple-choice/integrity.json",
|
| 316 |
+
"bytes": 163,
|
| 317 |
+
"sha256": "729c34c8d48b369ac8a615a50db76e8b7d1e9eef7134a1bf34849c573b79a234"
|
| 318 |
+
},
|
| 319 |
+
{
|
| 320 |
+
"path": "sml-mlx-v2/experiments/repair512_search_v1/candidates/028-broad-public-long-stable/benchmarks/repair512-search-028-broad-public-long-stable-u256/multiple-choice/manifest.json",
|
| 321 |
+
"bytes": 22145,
|
| 322 |
+
"sha256": "ef7197ac9430d226269d45fc0b7d3422c3f0a20ac2817870b13e31249d2e7bca"
|
| 323 |
+
},
|
| 324 |
+
{
|
| 325 |
+
"path": "sml-mlx-v2/experiments/repair512_search_v1/candidates/028-broad-public-long-stable/benchmarks/repair512-search-028-broad-public-long-stable-u256/multiple-choice/records.jsonl",
|
| 326 |
+
"bytes": 8905340,
|
| 327 |
+
"sha256": "aab6309b9000e5c341cd6e0ba48ab31ffa6f06cc79f25edd488006acfc212c27"
|
| 328 |
+
},
|
| 329 |
+
{
|
| 330 |
+
"path": "sml-mlx-v2/experiments/repair512_search_v1/candidates/028-broad-public-long-stable/benchmarks/repair512-search-028-broad-public-long-stable-u256/multiple-choice/summary.json",
|
| 331 |
+
"bytes": 690,
|
| 332 |
+
"sha256": "65e9d9819640a3f4f7667a984d3c3055f283bc7d47e8fb94091bca54e7dc97ec"
|
| 333 |
+
},
|
| 334 |
+
{
|
| 335 |
+
"path": "sml-mlx-v2/experiments/repair512_search_v1/candidates/028-broad-public-long-stable/checkpoint_cleanup.json",
|
| 336 |
+
"bytes": 3955,
|
| 337 |
+
"sha256": "795944665293786f9b7436a8d7df7d9a5c8586674971d311520bada82c84a39b"
|
| 338 |
+
},
|
| 339 |
+
{
|
| 340 |
+
"path": "sml-mlx-v2/experiments/repair512_search_v1/candidates/028-broad-public-long-stable/comparison.json",
|
| 341 |
+
"bytes": 4976,
|
| 342 |
+
"sha256": "ab774c75d42db577966a4231178fccab9b350af2948c8a206039627f7eed9a12"
|
| 343 |
+
},
|
| 344 |
+
{
|
| 345 |
+
"path": "sml-mlx-v2/experiments/repair512_search_v1/candidates/028-broad-public-long-stable/config.json",
|
| 346 |
+
"bytes": 2203,
|
| 347 |
+
"sha256": "d06d3552b264aab676d966a74598078955d2ea43683fc038a5401a7e42ffbe0c"
|
| 348 |
+
},
|
| 349 |
+
{
|
| 350 |
+
"path": "sml-mlx-v2/experiments/repair512_search_v1/candidates/028-broad-public-long-stable/data.json",
|
| 351 |
+
"bytes": 15034926,
|
| 352 |
+
"sha256": "a2d4d9401de47eb44030168be8bb04e865de467081019a7624110f08637f4dfa"
|
| 353 |
+
},
|
| 354 |
+
{
|
| 355 |
+
"path": "sml-mlx-v2/experiments/repair512_search_v1/candidates/028-broad-public-long-stable/negatives.json",
|
| 356 |
+
"bytes": 4229,
|
| 357 |
+
"sha256": "048cd6f1f30d998e40fdb4d76bf806e18ea66286c40d5a5defcc0843aaa0acc4"
|
| 358 |
+
},
|
| 359 |
+
{
|
| 360 |
+
"path": "sml-mlx-v2/experiments/repair512_search_v1/candidates/028-broad-public-long-stable/retained_result.json",
|
| 361 |
+
"bytes": 6583,
|
| 362 |
+
"sha256": "20a585841d228c28310a4f26024debb6ef2f2d25ae044b95530d55353c795297"
|
| 363 |
+
},
|
| 364 |
+
{
|
| 365 |
+
"path": "sml-mlx-v2/experiments/repair512_search_v1/candidates/028-broad-public-long-stable/run.log",
|
| 366 |
+
"bytes": 22776,
|
| 367 |
+
"sha256": "c8e9c9a947bfb006729b73133fdc1cc2d95b41c3ae94a6178f2ae87ac0823dc4"
|
| 368 |
+
},
|
| 369 |
+
{
|
| 370 |
+
"path": "sml-mlx-v2/experiments/repair512_search_v1/candidates/028-broad-public-long-stable/runs/sft/contract.json",
|
| 371 |
+
"bytes": 18725,
|
| 372 |
+
"sha256": "6268d303653c6751a1e10f1e3c38e21ad64ebd83621e228b87db087b61ef8483"
|
| 373 |
+
},
|
| 374 |
+
{
|
| 375 |
+
"path": "sml-mlx-v2/experiments/repair512_search_v1/candidates/028-broad-public-long-stable/runs/sft/evaluations/targeted_00000.json",
|
| 376 |
+
"bytes": 84837,
|
| 377 |
+
"sha256": "2760e5d9cd08da92ac80bc0179b74c7947976c30c6778a885d6ef0690e450653"
|
| 378 |
+
},
|
| 379 |
+
{
|
| 380 |
+
"path": "sml-mlx-v2/experiments/repair512_search_v1/candidates/028-broad-public-long-stable/runs/sft/evaluations/targeted_00128.json",
|
| 381 |
+
"bytes": 75746,
|
| 382 |
+
"sha256": "b6ed077ce1abc47bb460c2aadff12745a1d5218495d1429f61ccbc6f30eae2cd"
|
| 383 |
+
},
|
| 384 |
+
{
|
| 385 |
+
"path": "sml-mlx-v2/experiments/repair512_search_v1/candidates/028-broad-public-long-stable/runs/sft/evaluations/targeted_00256.json",
|
| 386 |
+
"bytes": 78536,
|
| 387 |
+
"sha256": "91bb4f2b016acae6d5933868987db95f661f687e88228f4c021572727960a49b"
|
| 388 |
+
},
|
| 389 |
+
{
|
| 390 |
+
"path": "sml-mlx-v2/experiments/repair512_search_v1/candidates/028-broad-public-long-stable/runs/sft/evaluations/targeted_00384.json",
|
| 391 |
+
"bytes": 85653,
|
| 392 |
+
"sha256": "269355ccc3f5c6af97af3a0fb82a6773cfc40c6a32e1d5ce6cc4531ee1b43d00"
|
| 393 |
+
},
|
| 394 |
+
{
|
| 395 |
+
"path": "sml-mlx-v2/experiments/repair512_search_v1/candidates/028-broad-public-long-stable/runs/sft/evaluations/targeted_00512.json",
|
| 396 |
+
"bytes": 80172,
|
| 397 |
+
"sha256": "c11c626ac249c6de8fa00dddfad0b87139e85153ea7bde9a589d775d7c1292de"
|
| 398 |
+
},
|
| 399 |
+
{
|
| 400 |
+
"path": "sml-mlx-v2/experiments/repair512_search_v1/candidates/028-broad-public-long-stable/runs/sft/evaluations/update_00000.json",
|
| 401 |
+
"bytes": 455938,
|
| 402 |
+
"sha256": "36aee7f595230203b72490104d775714920de59d513d4a67de5e38532f1a52cf"
|
| 403 |
+
},
|
| 404 |
+
{
|
| 405 |
+
"path": "sml-mlx-v2/experiments/repair512_search_v1/candidates/028-broad-public-long-stable/runs/sft/evaluations/update_00128.json",
|
| 406 |
+
"bytes": 452121,
|
| 407 |
+
"sha256": "1f7b09e2a166a8392b6c51e00fca4d9075110d7be0c7d6910c47595e344bad61"
|
| 408 |
+
},
|
| 409 |
+
{
|
| 410 |
+
"path": "sml-mlx-v2/experiments/repair512_search_v1/candidates/028-broad-public-long-stable/runs/sft/evaluations/update_00256.json",
|
| 411 |
+
"bytes": 444583,
|
| 412 |
+
"sha256": "886bc64ccb4e69ebb2d88c20279518e2cb15a8c126dd5435487cb7bf136e880a"
|
| 413 |
+
},
|
| 414 |
+
{
|
| 415 |
+
"path": "sml-mlx-v2/experiments/repair512_search_v1/candidates/028-broad-public-long-stable/runs/sft/evaluations/update_00384.json",
|
| 416 |
+
"bytes": 443219,
|
| 417 |
+
"sha256": "60e25041a1f05af6f18a94eb5d21c6a995fb9e35c37b7b7b5c938fa598fe2c54"
|
| 418 |
+
},
|
| 419 |
+
{
|
| 420 |
+
"path": "sml-mlx-v2/experiments/repair512_search_v1/candidates/028-broad-public-long-stable/runs/sft/evaluations/update_00512.json",
|
| 421 |
+
"bytes": 456062,
|
| 422 |
+
"sha256": "40b98ff3a9c54fbd611fb2c7efc48f9aae0c1e7ed9b6b48cc9a600d014fd9b82"
|
| 423 |
+
},
|
| 424 |
+
{
|
| 425 |
+
"path": "sml-mlx-v2/experiments/repair512_search_v1/candidates/028-broad-public-long-stable/runs/sft/finished.json",
|
| 426 |
+
"bytes": 268,
|
| 427 |
+
"sha256": "0f144440bfc330e533de811655b5c2fcb2188ae737a06d509440f2b33f386aca"
|
| 428 |
+
},
|
| 429 |
+
{
|
| 430 |
+
"path": "sml-mlx-v2/experiments/repair512_search_v1/candidates/028-broad-public-long-stable/runs/sft/latest.json",
|
| 431 |
+
"bytes": 82,
|
| 432 |
+
"sha256": "b15a5860caf7b126ca2e8ef02718bdccce16faa32e48f8e699b5df9567561e37"
|
| 433 |
+
},
|
| 434 |
+
{
|
| 435 |
+
"path": "sml-mlx-v2/experiments/repair512_search_v1/candidates/028-broad-public-long-stable/runs/sft/step_0000768_4980617cb301/manifest.json",
|
| 436 |
+
"bytes": 561,
|
| 437 |
+
"sha256": "1bc8d8350f20ac9c5cd69ad79c55b1120c0830dea30000c7576e140b5d2d22a3"
|
| 438 |
+
},
|
| 439 |
+
{
|
| 440 |
+
"path": "sml-mlx-v2/experiments/repair512_search_v1/candidates/028-broad-public-long-stable/runs/sft/step_0000768_4980617cb301/model.safetensors.json",
|
| 441 |
+
"bytes": 525,
|
| 442 |
+
"sha256": "7c0e307d7bc1973a1d5b8c683b2911c4dd2fead65d49226cdce53d6dfe098908"
|
| 443 |
+
},
|
| 444 |
+
{
|
| 445 |
+
"path": "sml-mlx-v2/experiments/repair512_search_v1/candidates/028-broad-public-long-stable/runs/sft/training.jsonl",
|
| 446 |
+
"bytes": 148139,
|
| 447 |
+
"sha256": "90bf86c280f79327762c752059cb65d9cbf134f9bbd696b9f59698bdc8e82758"
|
| 448 |
+
},
|
| 449 |
+
{
|
| 450 |
+
"path": "sml-mlx-v2/experiments/repair512_search_v1/candidates/028-broad-public-long-stable/selection.json",
|
| 451 |
+
"bytes": 1832,
|
| 452 |
+
"sha256": "50fca08ffe0fc3d0cd759ef4ec09509bb836ff92ea09932111db43edf78e7d9d"
|
| 453 |
+
},
|
| 454 |
+
{
|
| 455 |
+
"path": "sml-mlx-v2/experiments/repair512_search_v1/candidates/028-broad-public-long-stable/source_pins.json",
|
| 456 |
+
"bytes": 1020,
|
| 457 |
+
"sha256": "11baf5a81fd28f9e2e114cc7e1c050172175745e168154d2004590925c4577e4"
|
| 458 |
+
},
|
| 459 |
+
{
|
| 460 |
+
"path": "sml-mlx-v2/experiments/unified_text_v2_sft_v1/README.md",
|
| 461 |
+
"bytes": 6144,
|
| 462 |
+
"sha256": "fa54b6faca34e079e2d98a5fa61c46bd4b365d346224d1ea65db76d56fe36e02"
|
| 463 |
+
},
|
| 464 |
+
{
|
| 465 |
+
"path": "sml-mlx-v2/experiments/unified_text_v2_sft_v1/audits/384_review_v1/additional_findings.json",
|
| 466 |
+
"bytes": 5310,
|
| 467 |
+
"sha256": "86955ddde9aa5813f0adc3b1aefae6f15789179c8e93a3ebcc78128136e0a83f"
|
| 468 |
+
},
|
| 469 |
+
{
|
| 470 |
+
"path": "sml-mlx-v2/experiments/unified_text_v2_sft_v1/audits/384_review_v1/analyze.py",
|
| 471 |
+
"bytes": 8908,
|
| 472 |
+
"sha256": "4d5c47d2b9f84bc87ccf33d3b71365e9befcd36706627871ad0efb9b18a927ab"
|
| 473 |
+
},
|
| 474 |
+
{
|
| 475 |
+
"path": "sml-mlx-v2/experiments/unified_text_v2_sft_v1/audits/384_review_v1/build_report.py",
|
| 476 |
+
"bytes": 20320,
|
| 477 |
+
"sha256": "9f0058c6a23f6dcc0e41970e2f236b4775151a74060df1e01b2bd4d03fb7cc14"
|
| 478 |
+
},
|
| 479 |
+
{
|
| 480 |
+
"path": "sml-mlx-v2/experiments/unified_text_v2_sft_v1/audits/384_review_v1/ifeval_all_annotated.json",
|
| 481 |
+
"bytes": 1322865,
|
| 482 |
+
"sha256": "2a11935866624a92879df0f79643fcb69e61b3f5d70f11fec35338d2d6857f51"
|
| 483 |
+
},
|
| 484 |
+
{
|
| 485 |
+
"path": "sml-mlx-v2/experiments/unified_text_v2_sft_v1/audits/384_review_v1/legacy_chat_all.json",
|
| 486 |
+
"bytes": 29754,
|
| 487 |
+
"sha256": "09d26878651c6a4b1e82e0c4aee8094d578765d64c1f6463089d2fcd933b5380"
|
| 488 |
+
},
|
| 489 |
+
{
|
| 490 |
+
"path": "sml-mlx-v2/experiments/unified_text_v2_sft_v1/audits/384_review_v1/receipt.json",
|
| 491 |
+
"bytes": 1238,
|
| 492 |
+
"sha256": "066f55cca00422c993b5950ed59003347d1e2cc9b3a9a54c27a0d5ab308636d4"
|
| 493 |
+
},
|
| 494 |
+
{
|
| 495 |
+
"path": "sml-mlx-v2/experiments/unified_text_v2_sft_v1/audits/384_review_v1/recovery_all.json",
|
| 496 |
+
"bytes": 50089,
|
| 497 |
+
"sha256": "47fe12c3f7374db96704419eec237cf41966b6c6e8ed5266d5cf9442427f587d"
|
| 498 |
+
},
|
| 499 |
+
{
|
| 500 |
+
"path": "sml-mlx-v2/experiments/unified_text_v2_sft_v1/audits/384_review_v1/summary.json",
|
| 501 |
+
"bytes": 12875,
|
| 502 |
+
"sha256": "8a59b73fca8edba04e1a09d1a9cd753350d094adb98c54983ceb0cacd4453917"
|
| 503 |
+
},
|
| 504 |
+
{
|
| 505 |
+
"path": "sml-mlx-v2/experiments/unified_text_v2_sft_v1/audits/384_review_v1/training_refusal_markers.json",
|
| 506 |
+
"bytes": 635188,
|
| 507 |
+
"sha256": "64c1acdecc5d18d6c2d1854ea6ed309c6922aa1b893fea94af59f039e85d6761"
|
| 508 |
+
},
|
| 509 |
+
{
|
| 510 |
+
"path": "sml-mlx-v2/experiments/unified_text_v2_sft_v1/baselines/retained_768.json",
|
| 511 |
+
"bytes": 480232,
|
| 512 |
+
"sha256": "37cd576a70e3981dc95062cb1639e8c5dcf0220325dd9bcf513be0dc4d5e4f43"
|
| 513 |
+
},
|
| 514 |
+
{
|
| 515 |
+
"path": "sml-mlx-v2/experiments/unified_text_v2_sft_v1/baselines/retained_768_previous_list_definition.json",
|
| 516 |
+
"bytes": 480163,
|
| 517 |
+
"sha256": "170b55dd225cb6aae7fef8c02eb15d855b64b56bf014a8636a4011ba3e602572"
|
| 518 |
+
},
|
| 519 |
+
{
|
| 520 |
+
"path": "sml-mlx-v2/experiments/unified_text_v2_sft_v1/benchmarks/readiness/readiness_unified-text-v2-384_ifeval.json",
|
| 521 |
+
"bytes": 174984,
|
| 522 |
+
"sha256": "73072666f43a3e684b2eaac4f6c01fbdcc664c4ddce6faa15e97fb21cc0f9cae"
|
| 523 |
+
},
|
| 524 |
+
{
|
| 525 |
+
"path": "sml-mlx-v2/experiments/unified_text_v2_sft_v1/benchmarks/readiness/readiness_unified-text-v2-384_multiple-choice.json",
|
| 526 |
+
"bytes": 23570,
|
| 527 |
+
"sha256": "dcfb1c954c61718cd2cdb11d179a8a1dc6c5d5c4de759045b2f5dd4e2ba27e3f"
|
| 528 |
+
},
|
| 529 |
+
{
|
| 530 |
+
"path": "sml-mlx-v2/experiments/unified_text_v2_sft_v1/benchmarks/unified-text-v2-384/ifeval/integrity.json",
|
| 531 |
+
"bytes": 161,
|
| 532 |
+
"sha256": "c2ad62d77a74faf44598b992beaf18f4b1603f8d28a4bc0c5d50646cced3ff3d"
|
| 533 |
+
},
|
| 534 |
+
{
|
| 535 |
+
"path": "sml-mlx-v2/experiments/unified_text_v2_sft_v1/benchmarks/unified-text-v2-384/ifeval/manifest.json",
|
| 536 |
+
"bytes": 172301,
|
| 537 |
+
"sha256": "dd0d989aadb4bd6d2c046cb3203f8167aee28d1205de6e52d896c54252296409"
|
| 538 |
+
},
|
| 539 |
+
{
|
| 540 |
+
"path": "sml-mlx-v2/experiments/unified_text_v2_sft_v1/benchmarks/unified-text-v2-384/ifeval/records.jsonl",
|
| 541 |
+
"bytes": 2616383,
|
| 542 |
+
"sha256": "b1c9b1d3bc18878e1b3c33b57edb534ff39959507e86163cc4901e3a7400effa"
|
| 543 |
+
},
|
| 544 |
+
{
|
| 545 |
+
"path": "sml-mlx-v2/experiments/unified_text_v2_sft_v1/benchmarks/unified-text-v2-384/ifeval/summary.json",
|
| 546 |
+
"bytes": 614,
|
| 547 |
+
"sha256": "913db00ad90df8294541d2ff8d0f98b2b26b08d4b9c0c56230a3c0d4a60cd6d8"
|
| 548 |
+
},
|
| 549 |
+
{
|
| 550 |
+
"path": "sml-mlx-v2/experiments/unified_text_v2_sft_v1/benchmarks/unified-text-v2-384/multiple-choice/integrity.json",
|
| 551 |
+
"bytes": 163,
|
| 552 |
+
"sha256": "4b3da697314fe4ac2573820dfcb69396d0890aa7b1f1287535f24489f1552131"
|
| 553 |
+
},
|
| 554 |
+
{
|
| 555 |
+
"path": "sml-mlx-v2/experiments/unified_text_v2_sft_v1/benchmarks/unified-text-v2-384/multiple-choice/manifest.json",
|
| 556 |
+
"bytes": 22464,
|
| 557 |
+
"sha256": "bfc12c9da0a40c9f04b6d46f08898b7be6108113faabe40d3aee1fa928acbfd9"
|
| 558 |
+
},
|
| 559 |
+
{
|
| 560 |
+
"path": "sml-mlx-v2/experiments/unified_text_v2_sft_v1/benchmarks/unified-text-v2-384/multiple-choice/records.jsonl",
|
| 561 |
+
"bytes": 8905737,
|
| 562 |
+
"sha256": "8fc77af506dd4814d249e0f68f15a1f13b1154cdec1fd0d376a72f2521d8db6e"
|
| 563 |
+
},
|
| 564 |
+
{
|
| 565 |
+
"path": "sml-mlx-v2/experiments/unified_text_v2_sft_v1/benchmarks/unified-text-v2-384/multiple-choice/summary.json",
|
| 566 |
+
"bytes": 690,
|
| 567 |
+
"sha256": "260e6ce6208113ba6596d8eacf15a8c24f4484dc3dcab72b091c9d921e866b76"
|
| 568 |
+
},
|
| 569 |
+
{
|
| 570 |
+
"path": "sml-mlx-v2/experiments/unified_text_v2_sft_v1/comparisons/step_00384.json",
|
| 571 |
+
"bytes": 2029,
|
| 572 |
+
"sha256": "77029aa3d4a5c4bb4a1e8afecc7a948ad8c5d800c9dd97c1d535dc44660802a2"
|
| 573 |
+
},
|
| 574 |
+
{
|
| 575 |
+
"path": "sml-mlx-v2/experiments/unified_text_v2_sft_v1/comparisons/step_00384.md",
|
| 576 |
+
"bytes": 943,
|
| 577 |
+
"sha256": "2b59fca5c8548e351799f9810e52a8dd64f31a258ef7072fd8e3a41fa7ce6fc2"
|
| 578 |
+
},
|
| 579 |
+
{
|
| 580 |
+
"path": "sml-mlx-v2/experiments/unified_text_v2_sft_v1/config.json",
|
| 581 |
+
"bytes": 914,
|
| 582 |
+
"sha256": "a7086f6cf57bad7171c011ff2949580ffefc0e5cd23fe7f254f5328dbd642ede"
|
| 583 |
+
},
|
| 584 |
+
{
|
| 585 |
+
"path": "sml-mlx-v2/experiments/unified_text_v2_sft_v1/data/prepared.json",
|
| 586 |
+
"bytes": 47629159,
|
| 587 |
+
"sha256": "14e3e79cce495d880feddd2b905622157b5b796ee43ae06965a86dfb5fff3b1f"
|
| 588 |
+
},
|
| 589 |
+
{
|
| 590 |
+
"path": "sml-mlx-v2/experiments/unified_text_v2_sft_v1/readiness.json",
|
| 591 |
+
"bytes": 19772,
|
| 592 |
+
"sha256": "41fa86eae50cfaef7679d0a40c0814175cb42b170109b279064b8f8b3ea115f5"
|
| 593 |
+
},
|
| 594 |
+
{
|
| 595 |
+
"path": "sml-mlx-v2/experiments/unified_text_v2_sft_v1/runs/sft/contract.json",
|
| 596 |
+
"bytes": 18745,
|
| 597 |
+
"sha256": "da074b0d3ca56df597587d2390613e7824f48c774f41d59650fff46bc9b0e1f5"
|
| 598 |
+
},
|
| 599 |
+
{
|
| 600 |
+
"path": "sml-mlx-v2/experiments/unified_text_v2_sft_v1/runs/sft/evaluations/update_00000.json",
|
| 601 |
+
"bytes": 2063118,
|
| 602 |
+
"sha256": "4171276fec78087bdeae37747e85617e4f9853573259e1a530f65b3cba739401"
|
| 603 |
+
},
|
| 604 |
+
{
|
| 605 |
+
"path": "sml-mlx-v2/experiments/unified_text_v2_sft_v1/runs/sft/evaluations/update_00000.md",
|
| 606 |
+
"bytes": 148982,
|
| 607 |
+
"sha256": "71b4b468a12cc9f3cca21eb287ceb347f608544413a62576dd4831d0b4d99c5d"
|
| 608 |
+
},
|
| 609 |
+
{
|
| 610 |
+
"path": "sml-mlx-v2/experiments/unified_text_v2_sft_v1/runs/sft/evaluations/update_00064.json",
|
| 611 |
+
"bytes": 473373,
|
| 612 |
+
"sha256": "845820f20f781b671ea1505539c610fe6f6488dc4796a592ec8086d13d83483d"
|
| 613 |
+
},
|
| 614 |
+
{
|
| 615 |
+
"path": "sml-mlx-v2/experiments/unified_text_v2_sft_v1/runs/sft/evaluations/update_00064.md",
|
| 616 |
+
"bytes": 50304,
|
| 617 |
+
"sha256": "506d45f704d5810a598ae9b7a801cba66fb941c50ad13188891e51d4398d26c8"
|
| 618 |
+
},
|
| 619 |
+
{
|
| 620 |
+
"path": "sml-mlx-v2/experiments/unified_text_v2_sft_v1/runs/sft/evaluations/update_00128.json",
|
| 621 |
+
"bytes": 480191,
|
| 622 |
+
"sha256": "130ae60a75f29b724ea6de590124760602b90be0591c82559414a6db252c0e96"
|
| 623 |
+
},
|
| 624 |
+
{
|
| 625 |
+
"path": "sml-mlx-v2/experiments/unified_text_v2_sft_v1/runs/sft/evaluations/update_00128.md",
|
| 626 |
+
"bytes": 47755,
|
| 627 |
+
"sha256": "1788f909a719cf0af0591a36ae2a9fd88c2304d1ac25d50d5701e9ca395fa7ff"
|
| 628 |
+
},
|
| 629 |
+
{
|
| 630 |
+
"path": "sml-mlx-v2/experiments/unified_text_v2_sft_v1/runs/sft/evaluations/update_00256.json",
|
| 631 |
+
"bytes": 486927,
|
| 632 |
+
"sha256": "24a7697fbece4b32f6996be399101e44a8fd48e1df2474bdf22d216fa861bca1"
|
| 633 |
+
},
|
| 634 |
+
{
|
| 635 |
+
"path": "sml-mlx-v2/experiments/unified_text_v2_sft_v1/runs/sft/evaluations/update_00256.md",
|
| 636 |
+
"bytes": 46403,
|
| 637 |
+
"sha256": "a7db00bfdffa9d22dd211ee5794e40cc9d09a109aeb5de1b5c29639fee22d29d"
|
| 638 |
+
},
|
| 639 |
+
{
|
| 640 |
+
"path": "sml-mlx-v2/experiments/unified_text_v2_sft_v1/runs/sft/evaluations/update_00384.json",
|
| 641 |
+
"bytes": 476887,
|
| 642 |
+
"sha256": "7e897668a592b7eaa0d94090ee48eca8aaaacf3e53334b4c9181180be9170b42"
|
| 643 |
+
},
|
| 644 |
+
{
|
| 645 |
+
"path": "sml-mlx-v2/experiments/unified_text_v2_sft_v1/runs/sft/evaluations/update_00384.md",
|
| 646 |
+
"bytes": 47974,
|
| 647 |
+
"sha256": "729e9ff66707bead9503df53b9a29a96385f3d43e0210cf78e0d800be35fc95d"
|
| 648 |
+
},
|
| 649 |
+
{
|
| 650 |
+
"path": "sml-mlx-v2/experiments/unified_text_v2_sft_v1/runs/sft/evaluations/update_00512.json",
|
| 651 |
+
"bytes": 484202,
|
| 652 |
+
"sha256": "c51ebd7375b3e051730d9be57ce0e8896254a93000f121b9a27311a2db1998ca"
|
| 653 |
+
},
|
| 654 |
+
{
|
| 655 |
+
"path": "sml-mlx-v2/experiments/unified_text_v2_sft_v1/runs/sft/evaluations/update_00512.md",
|
| 656 |
+
"bytes": 46758,
|
| 657 |
+
"sha256": "44a2a12128769799999f4181dd1d9a6bafb0335c6b5418f4841b4ad2b1b4aa6c"
|
| 658 |
+
},
|
| 659 |
+
{
|
| 660 |
+
"path": "sml-mlx-v2/experiments/unified_text_v2_sft_v1/runs/sft/evaluations/update_00640.json",
|
| 661 |
+
"bytes": 491169,
|
| 662 |
+
"sha256": "a8633be13429a7fea13714366b8df57d08d0ab397e926d14c25a9c6c0825f42f"
|
| 663 |
+
},
|
| 664 |
+
{
|
| 665 |
+
"path": "sml-mlx-v2/experiments/unified_text_v2_sft_v1/runs/sft/evaluations/update_00640.md",
|
| 666 |
+
"bytes": 47990,
|
| 667 |
+
"sha256": "a3f2ecebff5c145c8a3a449e3208af65f608e280ffb91b1af0ac2514ef5cdc1c"
|
| 668 |
+
},
|
| 669 |
+
{
|
| 670 |
+
"path": "sml-mlx-v2/experiments/unified_text_v2_sft_v1/runs/sft/evaluations/update_00768.json",
|
| 671 |
+
"bytes": 493756,
|
| 672 |
+
"sha256": "cf06f3df28190830a589ad0f061514bd32eaf5552fdfa335cf7b0e0279d452a9"
|
| 673 |
+
},
|
| 674 |
+
{
|
| 675 |
+
"path": "sml-mlx-v2/experiments/unified_text_v2_sft_v1/runs/sft/evaluations/update_00768.md",
|
| 676 |
+
"bytes": 49557,
|
| 677 |
+
"sha256": "b920ecef4c3b2a41b7ba7f86868319c47ba80187a9c30ab5c29d6fbba000ec6f"
|
| 678 |
+
},
|
| 679 |
+
{
|
| 680 |
+
"path": "sml-mlx-v2/experiments/unified_text_v2_sft_v1/runs/sft/inputs/benchmark.py",
|
| 681 |
+
"bytes": 2936,
|
| 682 |
+
"sha256": "df13c3567c3723a99d2685347b0ebe9bb42c9fececaf0b7f212b84ecb6dc7e78"
|
| 683 |
+
},
|
| 684 |
+
{
|
| 685 |
+
"path": "sml-mlx-v2/experiments/unified_text_v2_sft_v1/runs/sft/inputs/compare.py",
|
| 686 |
+
"bytes": 2146,
|
| 687 |
+
"sha256": "a58478ebd74e944450f8c9fbe567bc85f361c6b1528a103efb7326ae0bce0f6f"
|
| 688 |
+
},
|
| 689 |
+
{
|
| 690 |
+
"path": "sml-mlx-v2/experiments/unified_text_v2_sft_v1/runs/sft/inputs/config.json",
|
| 691 |
+
"bytes": 914,
|
| 692 |
+
"sha256": "a7086f6cf57bad7171c011ff2949580ffefc0e5cd23fe7f254f5328dbd642ede"
|
| 693 |
+
},
|
| 694 |
+
{
|
| 695 |
+
"path": "sml-mlx-v2/experiments/unified_text_v2_sft_v1/runs/sft/inputs/data.py",
|
| 696 |
+
"bytes": 14082,
|
| 697 |
+
"sha256": "f09cfdf9a1fc0fea8384f7ab6890026b0f653fac9f9506b455c65d6de09224a6"
|
| 698 |
+
},
|
| 699 |
+
{
|
| 700 |
+
"path": "sml-mlx-v2/experiments/unified_text_v2_sft_v1/runs/sft/inputs/evaluate.py",
|
| 701 |
+
"bytes": 2912,
|
| 702 |
+
"sha256": "41e1ecf0ed1da7d5e6b9513c298e82636f3991bc5c4a00a3f6f172f68f161cdc"
|
| 703 |
+
},
|
| 704 |
+
{
|
| 705 |
+
"path": "sml-mlx-v2/experiments/unified_text_v2_sft_v1/runs/sft/inputs/launch.py",
|
| 706 |
+
"bytes": 18026,
|
| 707 |
+
"sha256": "ecad7943c55810d9da4c4043e7eb0c2e1f6939d2b038f24250f85af89a1924e5"
|
| 708 |
+
},
|
| 709 |
+
{
|
| 710 |
+
"path": "sml-mlx-v2/experiments/unified_text_v2_sft_v1/runs/sft/latest.json",
|
| 711 |
+
"bytes": 82,
|
| 712 |
+
"sha256": "29baea72db44893e925638234536df3a651db7a55082baa200789895e327048b"
|
| 713 |
+
},
|
| 714 |
+
{
|
| 715 |
+
"path": "sml-mlx-v2/experiments/unified_text_v2_sft_v1/runs/sft/report.json",
|
| 716 |
+
"bytes": 190,
|
| 717 |
+
"sha256": "a34abd46eb396062a8f44bea7f4481264cc90f2317aa34d71635e2608e2a925b"
|
| 718 |
+
},
|
| 719 |
+
{
|
| 720 |
+
"path": "sml-mlx-v2/experiments/unified_text_v2_sft_v1/runs/sft/step_0000064_26e5f8d01db6/manifest.json",
|
| 721 |
+
"bytes": 560,
|
| 722 |
+
"sha256": "9722ab5768a9792a39f302af69abcaf113e3eb36b5d01fb2500b75257b57b08e"
|
| 723 |
+
},
|
| 724 |
+
{
|
| 725 |
+
"path": "sml-mlx-v2/experiments/unified_text_v2_sft_v1/runs/sft/step_0000064_26e5f8d01db6/model.safetensors.json",
|
| 726 |
+
"bytes": 572,
|
| 727 |
+
"sha256": "134dfc9bd5dcd077a48b31863f6aa7bebc10c4b861db3a678611683eaf82d7e0"
|
| 728 |
+
},
|
| 729 |
+
{
|
| 730 |
+
"path": "sml-mlx-v2/experiments/unified_text_v2_sft_v1/runs/sft/step_0000128_158ec2e1d74f/manifest.json",
|
| 731 |
+
"bytes": 561,
|
| 732 |
+
"sha256": "51d5fa5286917a59a054b14aca69e223bb7f8a9e07461d85332394fa762603ee"
|
| 733 |
+
},
|
| 734 |
+
{
|
| 735 |
+
"path": "sml-mlx-v2/experiments/unified_text_v2_sft_v1/runs/sft/step_0000128_158ec2e1d74f/model.safetensors.json",
|
| 736 |
+
"bytes": 574,
|
| 737 |
+
"sha256": "caed696ea736885cac4b4cff1b422efece12c8b20b2101f325cec37bf6f46e1a"
|
| 738 |
+
},
|
| 739 |
+
{
|
| 740 |
+
"path": "sml-mlx-v2/experiments/unified_text_v2_sft_v1/runs/sft/step_0000256_b0e8d0cf7cb2/manifest.json",
|
| 741 |
+
"bytes": 561,
|
| 742 |
+
"sha256": "8520bed611f0e04470461e48e31647dc24ddada0e8268f89c1740a1581599ad4"
|
| 743 |
+
},
|
| 744 |
+
{
|
| 745 |
+
"path": "sml-mlx-v2/experiments/unified_text_v2_sft_v1/runs/sft/step_0000256_b0e8d0cf7cb2/model.safetensors.json",
|
| 746 |
+
"bytes": 574,
|
| 747 |
+
"sha256": "0a1ef903461c68f8e31ff7848758534380b88e236dd7ef48cd0ab1cd669f5b0f"
|
| 748 |
+
},
|
| 749 |
+
{
|
| 750 |
+
"path": "sml-mlx-v2/experiments/unified_text_v2_sft_v1/runs/sft/step_0000384_807628c9dbdc/manifest.json",
|
| 751 |
+
"bytes": 561,
|
| 752 |
+
"sha256": "1010a05a709e3da8fffd73deb8ce649026e4ed212b01a762ad569c15edaee9a1"
|
| 753 |
+
},
|
| 754 |
+
{
|
| 755 |
+
"path": "sml-mlx-v2/experiments/unified_text_v2_sft_v1/runs/sft/step_0000384_807628c9dbdc/model.safetensors.json",
|
| 756 |
+
"bytes": 574,
|
| 757 |
+
"sha256": "ca07ddc3db511d5458397e4d0651dc791f0e3ac6b0279a2f887dd4ef7df5bc6b"
|
| 758 |
+
},
|
| 759 |
+
{
|
| 760 |
+
"path": "sml-mlx-v2/experiments/unified_text_v2_sft_v1/runs/sft/step_0000512_0d93b325c545/manifest.json",
|
| 761 |
+
"bytes": 561,
|
| 762 |
+
"sha256": "8c9ed76764064f2a3a1836a07075ce2cd18de95b22240f55e43f1805cfeacf62"
|
| 763 |
+
},
|
| 764 |
+
{
|
| 765 |
+
"path": "sml-mlx-v2/experiments/unified_text_v2_sft_v1/runs/sft/step_0000512_0d93b325c545/model.safetensors.json",
|
| 766 |
+
"bytes": 574,
|
| 767 |
+
"sha256": "0413ed5c82b1bf3e5fb58d87aafc4e8472cf0a6ef99a259f6a0db890aedd250d"
|
| 768 |
+
},
|
| 769 |
+
{
|
| 770 |
+
"path": "sml-mlx-v2/experiments/unified_text_v2_sft_v1/runs/sft/step_0000640_000f4e4da94e/manifest.json",
|
| 771 |
+
"bytes": 561,
|
| 772 |
+
"sha256": "b4fe64901c96a87bf1510efda315ebfa3005e6d16dcc0c780534cba015af0f36"
|
| 773 |
+
},
|
| 774 |
+
{
|
| 775 |
+
"path": "sml-mlx-v2/experiments/unified_text_v2_sft_v1/runs/sft/step_0000640_000f4e4da94e/model.safetensors.json",
|
| 776 |
+
"bytes": 575,
|
| 777 |
+
"sha256": "3d30d9b7ec060c3f5f8414930544ebe9206cb2a855025406b3bb26566fd7a5f2"
|
| 778 |
+
},
|
| 779 |
+
{
|
| 780 |
+
"path": "sml-mlx-v2/experiments/unified_text_v2_sft_v1/runs/sft/step_0000768_bbb87b1b9e42/manifest.json",
|
| 781 |
+
"bytes": 561,
|
| 782 |
+
"sha256": "da58cd27f19dfd5e2842552bb3d6fe2f80808d141c8774fa2f4dc72dbeaa0540"
|
| 783 |
+
},
|
| 784 |
+
{
|
| 785 |
+
"path": "sml-mlx-v2/experiments/unified_text_v2_sft_v1/runs/sft/step_0000768_bbb87b1b9e42/model.safetensors.json",
|
| 786 |
+
"bytes": 575,
|
| 787 |
+
"sha256": "8d3b044abedcd35b9583fc365aee8d081e783a32ed18f45323dd1cdd59262c7a"
|
| 788 |
+
},
|
| 789 |
+
{
|
| 790 |
+
"path": "sml-mlx-v2/experiments/unified_text_v2_sft_v1/runs/sft/training.jsonl",
|
| 791 |
+
"bytes": 221436,
|
| 792 |
+
"sha256": "1f0f46d77253cbbdf594702f707de45150fadad89f1a2a4ce752a057c06463ce"
|
| 793 |
+
},
|
| 794 |
+
{
|
| 795 |
+
"path": "sml-mlx-v2/experiments/unified_text_v2_sft_v1/runs/sft/training.log",
|
| 796 |
+
"bytes": 24809,
|
| 797 |
+
"sha256": "13b9180dff22b0c1dc4be75b6203ce405e1ef43ab131155d2a3f9b3215f0dc6a"
|
| 798 |
+
},
|
| 799 |
+
{
|
| 800 |
+
"path": "sml-mlx-v2/experiments/unified_text_v2_sft_v1/scripts/benchmark.py",
|
| 801 |
+
"bytes": 2936,
|
| 802 |
+
"sha256": "df13c3567c3723a99d2685347b0ebe9bb42c9fececaf0b7f212b84ecb6dc7e78"
|
| 803 |
+
},
|
| 804 |
+
{
|
| 805 |
+
"path": "sml-mlx-v2/experiments/unified_text_v2_sft_v1/scripts/compare.py",
|
| 806 |
+
"bytes": 2146,
|
| 807 |
+
"sha256": "a58478ebd74e944450f8c9fbe567bc85f361c6b1528a103efb7326ae0bce0f6f"
|
| 808 |
+
},
|
| 809 |
+
{
|
| 810 |
+
"path": "sml-mlx-v2/experiments/unified_text_v2_sft_v1/scripts/data.py",
|
| 811 |
+
"bytes": 14082,
|
| 812 |
+
"sha256": "f09cfdf9a1fc0fea8384f7ab6890026b0f653fac9f9506b455c65d6de09224a6"
|
| 813 |
+
},
|
| 814 |
+
{
|
| 815 |
+
"path": "sml-mlx-v2/experiments/unified_text_v2_sft_v1/scripts/evaluate.py",
|
| 816 |
+
"bytes": 2912,
|
| 817 |
+
"sha256": "41e1ecf0ed1da7d5e6b9513c298e82636f3991bc5c4a00a3f6f172f68f161cdc"
|
| 818 |
+
},
|
| 819 |
+
{
|
| 820 |
+
"path": "sml-mlx-v2/experiments/unified_text_v2_sft_v1/scripts/launch.py",
|
| 821 |
+
"bytes": 18026,
|
| 822 |
+
"sha256": "ecad7943c55810d9da4c4043e7eb0c2e1f6939d2b038f24250f85af89a1924e5"
|
| 823 |
+
},
|
| 824 |
+
{
|
| 825 |
+
"path": "sml-mlx-v2/sft/conversation_foundation_v1/prepared.json",
|
| 826 |
+
"bytes": 179779711,
|
| 827 |
+
"sha256": "ae8a93a306bda7b996e33292ad9e25c9efda11379f772ccadad054430975dd29"
|
| 828 |
+
},
|
| 829 |
+
{
|
| 830 |
+
"path": "sml-mlx-v2/sft/grounded_rank_384/prepared.json",
|
| 831 |
+
"bytes": 5298180,
|
| 832 |
+
"sha256": "cf0a379a6bd78440152a57ffc1d98853de6ac25932052926e1d451f44d5a9454"
|
| 833 |
+
},
|
| 834 |
+
{
|
| 835 |
+
"path": "sml-mlx-v2/sft/preference_long_640/prepared.json",
|
| 836 |
+
"bytes": 29979623,
|
| 837 |
+
"sha256": "56d24fa9b368a17870c82e10320c2286297f3b6d389c50afb099822dce21af13"
|
| 838 |
+
},
|
| 839 |
+
{
|
| 840 |
+
"path": "sml-mlx-v2/sft/text_followup_512_v1/prepared.json",
|
| 841 |
+
"bytes": 14235573,
|
| 842 |
+
"sha256": "f7676dd515a9755bd26d460b486eb940e484081ae8910c044008f03bada61c51"
|
| 843 |
+
}
|
| 844 |
+
],
|
| 845 |
+
"archive": "OpenSML-150M-training-records.tar.gz",
|
| 846 |
+
"archive_sha256": "45d442f2a9713b73f14d4301d96a0c4b1d963985c706b3c7a7ec9631029503a3"
|
| 847 |
+
}
|
TRIAL28_RESULTS.json
ADDED
|
@@ -0,0 +1,262 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"checkpoint": "OpenSML-150M",
|
| 3 |
+
"bundle": "step_0000768_4980617cb301",
|
| 4 |
+
"weight_sha256": "cbd3e3fb4ada74d7264371b79cee7598f513b7b950f1f141ef9f1a43bd2e1b4e",
|
| 5 |
+
"parent_weight_sha256": "465ce42aad2e7c765f169aa75aa4124ec03fec17b46e6f5eabf75c2c4a8d4772",
|
| 6 |
+
"base_weight_sha256": "ca9bd5d82005f28e77f319d3a5a29f29fb4e4f86e7ceea049f01162fd8aae80f",
|
| 7 |
+
"lineage": [
|
| 8 |
+
"Pretrained Stage B step 73243",
|
| 9 |
+
"Unified384",
|
| 10 |
+
"Repair512",
|
| 11 |
+
"Trial28 +256"
|
| 12 |
+
],
|
| 13 |
+
"total_sft_step": 768,
|
| 14 |
+
"trial_additional_updates": 256,
|
| 15 |
+
"trial_planned_updates": 512,
|
| 16 |
+
"trial_consumed_records": 4096,
|
| 17 |
+
"selection": "Owner-selected current baseline; exploratory selection after repeated benchmark inspection; chat-repetition development gate failed",
|
| 18 |
+
"trial_config": {
|
| 19 |
+
"anchor_replay_only": true,
|
| 20 |
+
"automatic_selection": false,
|
| 21 |
+
"balanced_instructions": false,
|
| 22 |
+
"batch_conversations": 16,
|
| 23 |
+
"batch_counts": {
|
| 24 |
+
"chat": 4,
|
| 25 |
+
"grounded": 4,
|
| 26 |
+
"human": 4,
|
| 27 |
+
"instructions": 4
|
| 28 |
+
},
|
| 29 |
+
"betas": [
|
| 30 |
+
0.9,
|
| 31 |
+
0.95
|
| 32 |
+
],
|
| 33 |
+
"ce_weight": 1.0,
|
| 34 |
+
"checkpoint_keep": 4,
|
| 35 |
+
"clip_norm": 1.0,
|
| 36 |
+
"context": 2048,
|
| 37 |
+
"data_focused": false,
|
| 38 |
+
"dataset_plan": "breadth-stable",
|
| 39 |
+
"dpo_beta": 0.1,
|
| 40 |
+
"dpo_weight": 0.0,
|
| 41 |
+
"epochs": 1,
|
| 42 |
+
"evaluation_updates": [
|
| 43 |
+
0,
|
| 44 |
+
128,
|
| 45 |
+
256,
|
| 46 |
+
384,
|
| 47 |
+
512
|
| 48 |
+
],
|
| 49 |
+
"final_lr": 2e-07,
|
| 50 |
+
"format_preference_beta": 5.0,
|
| 51 |
+
"format_preference_weight": 0.0,
|
| 52 |
+
"freeze_embeddings": false,
|
| 53 |
+
"fresh_per_batch": 4,
|
| 54 |
+
"generated_history": false,
|
| 55 |
+
"generation_conversations": 56,
|
| 56 |
+
"generation_per_source": {
|
| 57 |
+
"chat": 8,
|
| 58 |
+
"grounded": 8,
|
| 59 |
+
"human": 8,
|
| 60 |
+
"instructions": 32
|
| 61 |
+
},
|
| 62 |
+
"holdout_per_source": 32,
|
| 63 |
+
"instruction_edge_weight": 1.0,
|
| 64 |
+
"instruction_weight": 1.0,
|
| 65 |
+
"kl_weight": 2.0,
|
| 66 |
+
"max_assistant_tokens": 192,
|
| 67 |
+
"max_new_tokens": 384,
|
| 68 |
+
"maximum_instruction_word_count": 120,
|
| 69 |
+
"method": "Broader verified public instruction/annotated QA mixture; two fresh passes plus repair512 replay; assistant-only CE + EOS; repetition penalty .3 and replay KL anchor 2",
|
| 70 |
+
"minimum_free_gib": 12,
|
| 71 |
+
"name": "public-repair-384-v1",
|
| 72 |
+
"negative_replay_only": true,
|
| 73 |
+
"on_policy": true,
|
| 74 |
+
"peak_lr": 2e-06,
|
| 75 |
+
"policy_kl_weight": 0.0,
|
| 76 |
+
"ranking_weight": 0.0,
|
| 77 |
+
"reference_aware": true,
|
| 78 |
+
"repetition_allowance": 2,
|
| 79 |
+
"repetition_ngram": 4,
|
| 80 |
+
"replay_only": false,
|
| 81 |
+
"seed": 202610011,
|
| 82 |
+
"source_caps": {
|
| 83 |
+
"chat": 192,
|
| 84 |
+
"grounded": 160,
|
| 85 |
+
"human": 160,
|
| 86 |
+
"instructions": 192
|
| 87 |
+
},
|
| 88 |
+
"source_model_sha256": "465ce42aad2e7c765f169aa75aa4124ec03fec17b46e6f5eabf75c2c4a8d4772",
|
| 89 |
+
"source_step": 512,
|
| 90 |
+
"train_all_norms": false,
|
| 91 |
+
"train_final_norm": false,
|
| 92 |
+
"train_last_blocks": 0,
|
| 93 |
+
"training_counts": {
|
| 94 |
+
"chat": 512,
|
| 95 |
+
"grounded": 2560,
|
| 96 |
+
"human": 1536,
|
| 97 |
+
"instructions": 3584
|
| 98 |
+
},
|
| 99 |
+
"ul_weight": 0.3,
|
| 100 |
+
"updates": 512,
|
| 101 |
+
"validation_conversations": 128,
|
| 102 |
+
"warmup_updates": 16,
|
| 103 |
+
"weight_decay": 0.0,
|
| 104 |
+
"weighting": "conversation"
|
| 105 |
+
},
|
| 106 |
+
"source_pins": {
|
| 107 |
+
"constraints": {
|
| 108 |
+
"file": "data/smol-constraints/train-00000-of-00001.parquet",
|
| 109 |
+
"license": "Apache-2.0",
|
| 110 |
+
"local_file": "constraints.parquet",
|
| 111 |
+
"repo": "HuggingFaceTB/smoltalk",
|
| 112 |
+
"revision": "5feaf2fd3ffca7c237fc38d1861bc30365d48ffa",
|
| 113 |
+
"sha256": "3369eaff911d3511ee21561a3b8607e1acfd773a6ade80f4759490ffdcce7ba4",
|
| 114 |
+
"split": "train"
|
| 115 |
+
},
|
| 116 |
+
"squad": {
|
| 117 |
+
"file": "squad_v2/train-00000-of-00001.parquet",
|
| 118 |
+
"license": "CC-BY-SA-4.0",
|
| 119 |
+
"local_file": "squad.parquet",
|
| 120 |
+
"repo": "rajpurkar/squad_v2",
|
| 121 |
+
"revision": "3ffb306f725f7d2ce8394bc1873b24868140c412",
|
| 122 |
+
"sha256": "f6da32ffb482ff463ad056477740d1bb284b96a45db3a08bee6a225ca6abf291",
|
| 123 |
+
"split": "train"
|
| 124 |
+
},
|
| 125 |
+
"sciq": {
|
| 126 |
+
"repo": "allenai/sciq",
|
| 127 |
+
"revision": "2c94ad3e1aafab77146f384e23536f97a4849815",
|
| 128 |
+
"file": "data/train-00000-of-00001.parquet",
|
| 129 |
+
"local_file": "sciq.parquet",
|
| 130 |
+
"license": "CC-BY-NC-3.0",
|
| 131 |
+
"split": "train",
|
| 132 |
+
"sha256": "19644360954006d06e9ad3df07bddb34f8535c081b831d48f604603c713ac167"
|
| 133 |
+
}
|
| 134 |
+
},
|
| 135 |
+
"benchmarks": {
|
| 136 |
+
"multiple-choice": {
|
| 137 |
+
"summary": {
|
| 138 |
+
"completed": 15428,
|
| 139 |
+
"expected": 15428,
|
| 140 |
+
"status": "complete",
|
| 141 |
+
"tasks": {
|
| 142 |
+
"arc_challenge": {
|
| 143 |
+
"acc": 0.26023890784982934,
|
| 144 |
+
"acc_norm": 0.295221843003413,
|
| 145 |
+
"completed": 1172,
|
| 146 |
+
"expected": 1172
|
| 147 |
+
},
|
| 148 |
+
"arc_easy": {
|
| 149 |
+
"acc": 0.5664983164983165,
|
| 150 |
+
"acc_norm": 0.5542929292929293,
|
| 151 |
+
"completed": 2376,
|
| 152 |
+
"expected": 2376
|
| 153 |
+
},
|
| 154 |
+
"hellaswag": {
|
| 155 |
+
"acc": 0.30551682931686913,
|
| 156 |
+
"acc_norm": 0.33937462656841266,
|
| 157 |
+
"completed": 10042,
|
| 158 |
+
"expected": 10042
|
| 159 |
+
},
|
| 160 |
+
"piqa": {
|
| 161 |
+
"acc": 0.6452665941240479,
|
| 162 |
+
"acc_norm": 0.6409140369967355,
|
| 163 |
+
"completed": 1838,
|
| 164 |
+
"expected": 1838
|
| 165 |
+
}
|
| 166 |
+
},
|
| 167 |
+
"training": false
|
| 168 |
+
},
|
| 169 |
+
"integrity": {
|
| 170 |
+
"completed": 15428,
|
| 171 |
+
"inputs_unchanged": true,
|
| 172 |
+
"manifest_sha256": "ef7197ac9430d226269d45fc0b7d3422c3f0a20ac2817870b13e31249d2e7bca",
|
| 173 |
+
"training": false
|
| 174 |
+
},
|
| 175 |
+
"protocol": {
|
| 176 |
+
"decode_mode": "cached",
|
| 177 |
+
"eos": 1,
|
| 178 |
+
"extra_stop_strings": [],
|
| 179 |
+
"greedy": true,
|
| 180 |
+
"harness": "b954108c9baaaa934b4ad842033b31a97ee30816",
|
| 181 |
+
"ifeval_template": "User: {unchanged prompt}\nAssistant:",
|
| 182 |
+
"max_new_tokens": 1280,
|
| 183 |
+
"mc_metrics": [
|
| 184 |
+
"acc",
|
| 185 |
+
"acc_norm"
|
| 186 |
+
],
|
| 187 |
+
"mc_template": "plain official question/continuation; no chat/BOS/EOS",
|
| 188 |
+
"repetition_penalty": 1,
|
| 189 |
+
"seed": 24092026
|
| 190 |
+
},
|
| 191 |
+
"fp32": true,
|
| 192 |
+
"attention": "MLX explicit vanilla attention; PyTorch equivalence not claimed",
|
| 193 |
+
"batch_size": 1,
|
| 194 |
+
"context": 2048,
|
| 195 |
+
"prepared_sha256": "88b30e3a273f6817e9af1e360dbeb44714c58f2b345ca875a0ad83a0e8c05da5"
|
| 196 |
+
},
|
| 197 |
+
"ifeval": {
|
| 198 |
+
"summary": {
|
| 199 |
+
"completed": 541,
|
| 200 |
+
"expected": 541,
|
| 201 |
+
"loose": {
|
| 202 |
+
"instruction_accuracy": 0.2577937649880096,
|
| 203 |
+
"instruction_correct": 215,
|
| 204 |
+
"instruction_total": 834,
|
| 205 |
+
"prompt_accuracy": 0.15711645101663585,
|
| 206 |
+
"prompt_correct": 85,
|
| 207 |
+
"prompt_total": 541
|
| 208 |
+
},
|
| 209 |
+
"status": "complete",
|
| 210 |
+
"stop_counts": {
|
| 211 |
+
"context_limit": 0,
|
| 212 |
+
"eos": 508,
|
| 213 |
+
"length": 33
|
| 214 |
+
},
|
| 215 |
+
"strict": {
|
| 216 |
+
"instruction_accuracy": 0.2529976019184652,
|
| 217 |
+
"instruction_correct": 211,
|
| 218 |
+
"instruction_total": 834,
|
| 219 |
+
"prompt_accuracy": 0.15157116451016636,
|
| 220 |
+
"prompt_correct": 82,
|
| 221 |
+
"prompt_total": 541
|
| 222 |
+
},
|
| 223 |
+
"training": false
|
| 224 |
+
},
|
| 225 |
+
"integrity": {
|
| 226 |
+
"completed": 541,
|
| 227 |
+
"inputs_unchanged": true,
|
| 228 |
+
"manifest_sha256": "af4b836f50fe1ae10a19eb4634d191c5b8b1ba9e1c3d6ae1d31bec95cdb8010c",
|
| 229 |
+
"training": false
|
| 230 |
+
},
|
| 231 |
+
"protocol": {
|
| 232 |
+
"decode_mode": "cached",
|
| 233 |
+
"eos": 1,
|
| 234 |
+
"extra_stop_strings": [],
|
| 235 |
+
"greedy": true,
|
| 236 |
+
"harness": "b954108c9baaaa934b4ad842033b31a97ee30816",
|
| 237 |
+
"ifeval_template": "User: {unchanged prompt}\nAssistant:",
|
| 238 |
+
"max_new_tokens": 1280,
|
| 239 |
+
"mc_metrics": [
|
| 240 |
+
"acc",
|
| 241 |
+
"acc_norm"
|
| 242 |
+
],
|
| 243 |
+
"mc_template": "plain official question/continuation; no chat/BOS/EOS",
|
| 244 |
+
"repetition_penalty": 1,
|
| 245 |
+
"seed": 24092026
|
| 246 |
+
},
|
| 247 |
+
"fp32": true,
|
| 248 |
+
"attention": "MLX explicit vanilla attention; PyTorch equivalence not claimed",
|
| 249 |
+
"batch_size": 1,
|
| 250 |
+
"context": 2048,
|
| 251 |
+
"prepared_sha256": "88b30e3a273f6817e9af1e360dbeb44714c58f2b345ca875a0ad83a0e8c05da5"
|
| 252 |
+
}
|
| 253 |
+
},
|
| 254 |
+
"source_record_sha256": {
|
| 255 |
+
"config.json": "d06d3552b264aab676d966a74598078955d2ea43683fc038a5401a7e42ffbe0c",
|
| 256 |
+
"selection.json": "50fca08ffe0fc3d0cd759ef4ec09509bb836ff92ea09932111db43edf78e7d9d",
|
| 257 |
+
"source_pins.json": "11baf5a81fd28f9e2e114cc7e1c050172175745e168154d2004590925c4577e4",
|
| 258 |
+
"retained_result.json": "20a585841d228c28310a4f26024debb6ef2f2d25ae044b95530d55353c795297"
|
| 259 |
+
},
|
| 260 |
+
"internal_experiment": "Trial 28 \u2014 Repair512 +256",
|
| 261 |
+
"public_model_name": "OpenSML-150M"
|
| 262 |
+
}
|
checkpoint_provenance.json
ADDED
|
@@ -0,0 +1,38 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"model_name": "OpenSML-150M",
|
| 3 |
+
"step": 768,
|
| 4 |
+
"additional_updates": 256,
|
| 5 |
+
"weights_sha256": "cbd3e3fb4ada74d7264371b79cee7598f513b7b950f1f141ef9f1a43bd2e1b4e",
|
| 6 |
+
"source_metadata": {
|
| 7 |
+
"additional_updates": 256,
|
| 8 |
+
"automatic_promotion": false,
|
| 9 |
+
"contract": "e7ad0c5c033aa86c115458bb4be6efe1d20e9d0c73aa8231480e16ff6f1f4fdd",
|
| 10 |
+
"experimental": true,
|
| 11 |
+
"source_bundle": "experiments/public_repair_384_v1/runs/sft/step_0000512_6972bbf9be08",
|
| 12 |
+
"source_model_sha256": "465ce42aad2e7c765f169aa75aa4124ec03fec17b46e6f5eabf75c2c4a8d4772",
|
| 13 |
+
"source_step": 512,
|
| 14 |
+
"step": 768,
|
| 15 |
+
"tokenizer": "1194292c6d906ac19e6f01c6ad2b42825143fad426a22aa8856d903776701ecb",
|
| 16 |
+
"training_format": "plain-user-assistant-eos-v1"
|
| 17 |
+
},
|
| 18 |
+
"source_manifest": {
|
| 19 |
+
"created_ns": 1790893470379935000,
|
| 20 |
+
"files": {
|
| 21 |
+
"model.safetensors": {
|
| 22 |
+
"bytes": 601772434,
|
| 23 |
+
"sha256": "cbd3e3fb4ada74d7264371b79cee7598f513b7b950f1f141ef9f1a43bd2e1b4e"
|
| 24 |
+
},
|
| 25 |
+
"model.safetensors.json": {
|
| 26 |
+
"bytes": 525,
|
| 27 |
+
"sha256": "7c0e307d7bc1973a1d5b8c683b2911c4dd2fead65d49226cdce53d6dfe098908"
|
| 28 |
+
},
|
| 29 |
+
"model.safetensors.optimizer.safetensors": {
|
| 30 |
+
"bytes": 1805319748,
|
| 31 |
+
"sha256": "a23dd9b5ca2af99ac3a7648a7b9a70acb04c183aacbea71fdaabd2a1fdc2c720"
|
| 32 |
+
}
|
| 33 |
+
},
|
| 34 |
+
"format": "sml-pretrain-bundle-v1",
|
| 35 |
+
"step": 768
|
| 36 |
+
},
|
| 37 |
+
"export": "Exact unchanged FP32 weights; optimizer tensors excluded. Native reference MLX inference."
|
| 38 |
+
}
|
config.json
ADDED
|
@@ -0,0 +1,24 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"model_name": "OpenSML-150M",
|
| 3 |
+
"format": "opensml-native-mlx-v1",
|
| 4 |
+
"model": {
|
| 5 |
+
"attention_impl": "vanilla",
|
| 6 |
+
"bias": false,
|
| 7 |
+
"ce_impl": "reference",
|
| 8 |
+
"d_model": 768,
|
| 9 |
+
"ffn_impl": "reference",
|
| 10 |
+
"loss_dtype": "float32",
|
| 11 |
+
"max_seq_len": 2048,
|
| 12 |
+
"mlp_multiple_of": 256,
|
| 13 |
+
"mlp_ratio": 4.0,
|
| 14 |
+
"n_heads": 12,
|
| 15 |
+
"n_kv_heads": 4,
|
| 16 |
+
"n_layers": 20,
|
| 17 |
+
"qk_norm": true,
|
| 18 |
+
"vocab_size": 32000
|
| 19 |
+
},
|
| 20 |
+
"training_format": "plain-user-assistant-eos-v1",
|
| 21 |
+
"dtype": "float32",
|
| 22 |
+
"context_length": 2048,
|
| 23 |
+
"weights_sha256": "cbd3e3fb4ada74d7264371b79cee7598f513b7b950f1f141ef9f1a43bd2e1b4e"
|
| 24 |
+
}
|
corpus.json
ADDED
|
@@ -0,0 +1,60 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"max_bytes": 200000,
|
| 3 |
+
"max_rows_per_source": 5000000,
|
| 4 |
+
"min_chars": 200,
|
| 5 |
+
"name": "sml-v2-educational-prose-v1",
|
| 6 |
+
"seed": 7337,
|
| 7 |
+
"shuffle_buffer": 10000,
|
| 8 |
+
"sources": [
|
| 9 |
+
{
|
| 10 |
+
"config": "fineweb-edu-dedup",
|
| 11 |
+
"label": "web",
|
| 12 |
+
"license": "ODC-BY; preserve underlying source notices",
|
| 13 |
+
"repo": "HuggingFaceTB/smollm-corpus",
|
| 14 |
+
"revision": "3ba9d605774198c5868892d7a8deda78031a781f",
|
| 15 |
+
"split": "train",
|
| 16 |
+
"text_field": "text",
|
| 17 |
+
"weight": 55
|
| 18 |
+
},
|
| 19 |
+
{
|
| 20 |
+
"label": "dclm",
|
| 21 |
+
"license": "CC-BY-4.0",
|
| 22 |
+
"min_score": {
|
| 23 |
+
"field": "edu_int_score",
|
| 24 |
+
"value": 3
|
| 25 |
+
},
|
| 26 |
+
"repo": "HuggingFaceTB/dclm-edu",
|
| 27 |
+
"revision": "dbad8ad71224482740cd9c9d353591adbf62fe04",
|
| 28 |
+
"split": "train",
|
| 29 |
+
"text_field": "text",
|
| 30 |
+
"weight": 25
|
| 31 |
+
},
|
| 32 |
+
{
|
| 33 |
+
"config": "en",
|
| 34 |
+
"label": "wiki",
|
| 35 |
+
"license": "CC-BY-SA-4.0 / GFDL",
|
| 36 |
+
"repo": "HuggingFaceFW/finewiki",
|
| 37 |
+
"revision": "8bd13e72e6a002407649b3e898535f42ceb1aeb9",
|
| 38 |
+
"split": "train",
|
| 39 |
+
"text_field": "text",
|
| 40 |
+
"weight": 10
|
| 41 |
+
},
|
| 42 |
+
{
|
| 43 |
+
"config": "cosmopedia-v2",
|
| 44 |
+
"format_contains": [
|
| 45 |
+
"textbook",
|
| 46 |
+
"tutorial",
|
| 47 |
+
"blog",
|
| 48 |
+
"educational"
|
| 49 |
+
],
|
| 50 |
+
"label": "cosmopedia",
|
| 51 |
+
"license": "ODC-BY; synthetic content; preserve provenance",
|
| 52 |
+
"repo": "HuggingFaceTB/smollm-corpus",
|
| 53 |
+
"revision": "3ba9d605774198c5868892d7a8deda78031a781f",
|
| 54 |
+
"split": "train",
|
| 55 |
+
"text_field": "text",
|
| 56 |
+
"weight": 10
|
| 57 |
+
}
|
| 58 |
+
],
|
| 59 |
+
"split_buckets": 10000
|
| 60 |
+
}
|
inference.py
ADDED
|
@@ -0,0 +1,36 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
"""Standalone OpenSML-150M inference on Apple Silicon using native MLX."""
|
| 2 |
+
import argparse,json
|
| 3 |
+
from pathlib import Path
|
| 4 |
+
import mlx.core as mx
|
| 5 |
+
from native_model import TransformerConfig,TransformerLM,count_parameters
|
| 6 |
+
from native_tokenizer import Tokenizer
|
| 7 |
+
from native_utils import file_sha256
|
| 8 |
+
|
| 9 |
+
def load_model(directory):
|
| 10 |
+
root=Path(directory).resolve();cfg=json.loads((root/'config.json').read_text())
|
| 11 |
+
if cfg['format']!='opensml-native-mlx-v1':raise ValueError('Unsupported model format')
|
| 12 |
+
if file_sha256(root/'model.safetensors')!=cfg['weights_sha256']:raise ValueError('Weights checksum mismatch')
|
| 13 |
+
tok=Tokenizer(root)
|
| 14 |
+
if tok.vocab_size!=cfg['model']['vocab_size']:raise ValueError('Tokenizer/model vocabulary mismatch')
|
| 15 |
+
model=TransformerLM(TransformerConfig(**cfg['model']));model.load_weights(str(root/'model.safetensors'),strict=True);model.eval();mx.eval(model.parameters())
|
| 16 |
+
return model,tok
|
| 17 |
+
|
| 18 |
+
def generate(model,tokenizer,prompt,max_new_tokens=128,raw_completion=False):
|
| 19 |
+
if max_new_tokens<1:raise ValueError('max_new_tokens must be positive')
|
| 20 |
+
text=prompt if raw_completion else f'User: {prompt}\nAssistant:'
|
| 21 |
+
ids=tokenizer.encode(text)
|
| 22 |
+
if not ids or len(ids)+max_new_tokens>model.cfg.max_seq_len:raise ValueError('Prompt plus output budget must fit the 2048-token context')
|
| 23 |
+
generated=[];caches=None;inputs=mx.array([ids]);stop='max_new_tokens'
|
| 24 |
+
for _ in range(max_new_tokens):
|
| 25 |
+
logits,caches=model.step(inputs,caches=caches)
|
| 26 |
+
token=int(mx.argmax(logits,axis=-1).item());generated.append(token)
|
| 27 |
+
if token==tokenizer.eos:stop='eos';break
|
| 28 |
+
inputs=mx.array([[token]])
|
| 29 |
+
answer=generated[:-1] if generated and generated[-1]==tokenizer.eos else generated
|
| 30 |
+
return {'text':tokenizer.decode(answer),'token_ids':generated,'stop_reason':stop,'prompt_tokens':len(ids),'generated_tokens':len(generated)}
|
| 31 |
+
|
| 32 |
+
def main():
|
| 33 |
+
p=argparse.ArgumentParser(description=__doc__);p.add_argument('--model-directory',type=Path,default=Path(__file__).resolve().parent);p.add_argument('--prompt',required=True);p.add_argument('--max-new-tokens',type=int,default=128);p.add_argument('--raw-completion',action='store_true',help='Skip the User/Assistant wrapper for base-style completion prompts');a=p.parse_args()
|
| 34 |
+
model,tok=load_model(a.model_directory)
|
| 35 |
+
print(json.dumps(generate(model,tok,a.prompt,a.max_new_tokens,a.raw_completion),ensure_ascii=False,indent=2))
|
| 36 |
+
if __name__=='__main__':main()
|
manifest.json
ADDED
|
@@ -0,0 +1,31 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"boundary_policy": "raw-text-then-one-document-EOS-v1",
|
| 3 |
+
"corpus_fingerprint": "a89f69d6f63cfa4385da233693a445404234a18194170fe1d2b4a74bf501f5d6",
|
| 4 |
+
"format": "sml-v2-tokenizer-v1",
|
| 5 |
+
"recipe": {
|
| 6 |
+
"corpus": "a89f69d6f63cfa4385da233693a445404234a18194170fe1d2b4a74bf501f5d6",
|
| 7 |
+
"min_frequency": 2,
|
| 8 |
+
"sample_manifest": "30ead6f502f11e99b479e3711a81ce7198787408d0700153615fc3255b244f46",
|
| 9 |
+
"specials": [
|
| 10 |
+
"<|pad|>",
|
| 11 |
+
"<|doc_end|>",
|
| 12 |
+
"<|turn_start|>",
|
| 13 |
+
"<|turn_end|>"
|
| 14 |
+
],
|
| 15 |
+
"tokenizers": "0.22.2",
|
| 16 |
+
"version": 1,
|
| 17 |
+
"vocab_size": 32000
|
| 18 |
+
},
|
| 19 |
+
"sha256": {
|
| 20 |
+
"corpus.json": "e4c47b7b6aba08f948de7c2c7cb94c58dbd09dde2ded6ac185c60856ee686d27",
|
| 21 |
+
"tokenizer.json": "e095f0413a11fa91fbb58f37d00e4c6bcda59beb89b28f6f680db1436a7e8891",
|
| 22 |
+
"tokenizer_config.json": "619f500553367eb76f5be00a98625130ec857b9c367561334984096c029ba2a9"
|
| 23 |
+
},
|
| 24 |
+
"special_ids": {
|
| 25 |
+
"eos": 1,
|
| 26 |
+
"pad": 0,
|
| 27 |
+
"turn_end": 3,
|
| 28 |
+
"turn_start": 2
|
| 29 |
+
},
|
| 30 |
+
"vocab_size": 32000
|
| 31 |
+
}
|
native_model.py
ADDED
|
@@ -0,0 +1,278 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
#!/usr/bin/env python3
|
| 2 |
+
"""MLX-only transformer model for small causal language modeling."""
|
| 3 |
+
|
| 4 |
+
from __future__ import annotations
|
| 5 |
+
|
| 6 |
+
import math
|
| 7 |
+
from dataclasses import dataclass
|
| 8 |
+
from typing import List, Optional, Tuple
|
| 9 |
+
|
| 10 |
+
import mlx.core as mx
|
| 11 |
+
import mlx.nn as nn
|
| 12 |
+
import mlx.nn.losses as losses
|
| 13 |
+
|
| 14 |
+
|
| 15 |
+
@dataclass
|
| 16 |
+
class TransformerConfig:
|
| 17 |
+
vocab_size: int
|
| 18 |
+
max_seq_len: int = 1024
|
| 19 |
+
d_model: int = 768
|
| 20 |
+
n_heads: int = 12
|
| 21 |
+
n_kv_heads: Optional[int] = None
|
| 22 |
+
n_layers: int = 12
|
| 23 |
+
mlp_ratio: float = 4.0
|
| 24 |
+
mlp_multiple_of: int = 256
|
| 25 |
+
rope_base: float = 10000.0
|
| 26 |
+
bias: bool = False
|
| 27 |
+
qk_norm: bool = True
|
| 28 |
+
attention_impl: str = "fast"
|
| 29 |
+
loss_dtype: str = "float32"
|
| 30 |
+
ce_impl: str = "reference"
|
| 31 |
+
ffn_impl: str = "reference"
|
| 32 |
+
|
| 33 |
+
def __post_init__(self) -> None:
|
| 34 |
+
if self.vocab_size <= 0:
|
| 35 |
+
raise ValueError("vocab_size must be > 0")
|
| 36 |
+
if self.max_seq_len <= 0:
|
| 37 |
+
raise ValueError("max_seq_len must be > 0")
|
| 38 |
+
if self.d_model <= 0:
|
| 39 |
+
raise ValueError("d_model must be > 0")
|
| 40 |
+
if self.n_heads <= 0 or self.d_model % self.n_heads != 0:
|
| 41 |
+
raise ValueError("n_heads must divide d_model")
|
| 42 |
+
if self.n_kv_heads is None:
|
| 43 |
+
self.n_kv_heads = self.n_heads
|
| 44 |
+
if self.n_kv_heads <= 0 or self.n_heads % self.n_kv_heads != 0:
|
| 45 |
+
raise ValueError("n_kv_heads must be positive and divide n_heads")
|
| 46 |
+
if self.n_layers <= 0:
|
| 47 |
+
raise ValueError("n_layers must be > 0")
|
| 48 |
+
if self.mlp_ratio <= 1.0:
|
| 49 |
+
raise ValueError("mlp_ratio must be > 1.0")
|
| 50 |
+
if self.mlp_multiple_of <= 0:
|
| 51 |
+
raise ValueError("mlp_multiple_of must be > 0")
|
| 52 |
+
if self.attention_impl not in {"fast", "vanilla"}:
|
| 53 |
+
raise ValueError("attention_impl must be one of: fast, vanilla")
|
| 54 |
+
if self.loss_dtype not in {"float32", "model"}:
|
| 55 |
+
raise ValueError("loss_dtype must be one of: float32, model")
|
| 56 |
+
if self.ce_impl not in {"reference", "metal"}:
|
| 57 |
+
raise ValueError("ce_impl must be reference or metal")
|
| 58 |
+
if self.ce_impl == "metal" and self.loss_dtype != "float32":
|
| 59 |
+
raise ValueError("Metal CE uses FP32 reductions")
|
| 60 |
+
if self.ffn_impl not in {"reference", "packed-metal"}:
|
| 61 |
+
raise ValueError("ffn_impl must be reference or packed-metal")
|
| 62 |
+
|
| 63 |
+
|
| 64 |
+
def _tree_leaves(tree):
|
| 65 |
+
if isinstance(tree, dict):
|
| 66 |
+
for v in tree.values():
|
| 67 |
+
yield from _tree_leaves(v)
|
| 68 |
+
elif isinstance(tree, (list, tuple)):
|
| 69 |
+
for v in tree:
|
| 70 |
+
yield from _tree_leaves(v)
|
| 71 |
+
else:
|
| 72 |
+
yield tree
|
| 73 |
+
|
| 74 |
+
|
| 75 |
+
def count_parameters(model: nn.Module) -> int:
|
| 76 |
+
total = 0
|
| 77 |
+
for leaf in _tree_leaves(model.parameters()):
|
| 78 |
+
if isinstance(leaf, mx.array):
|
| 79 |
+
n = 1
|
| 80 |
+
for d in leaf.shape:
|
| 81 |
+
n *= int(d)
|
| 82 |
+
total += n
|
| 83 |
+
return total
|
| 84 |
+
|
| 85 |
+
|
| 86 |
+
class CausalSelfAttention(nn.Module):
|
| 87 |
+
def __init__(self, cfg: TransformerConfig):
|
| 88 |
+
super().__init__()
|
| 89 |
+
self.n_heads = cfg.n_heads
|
| 90 |
+
self.n_kv_heads = cfg.n_kv_heads
|
| 91 |
+
self.head_dim = cfg.d_model // cfg.n_heads
|
| 92 |
+
self.q_dim = cfg.n_heads * self.head_dim
|
| 93 |
+
self.kv_dim = cfg.n_kv_heads * self.head_dim
|
| 94 |
+
self.max_seq_len = cfg.max_seq_len
|
| 95 |
+
|
| 96 |
+
self.qkv_proj = nn.Linear(cfg.d_model, self.q_dim + 2 * self.kv_dim, bias=cfg.bias)
|
| 97 |
+
self.proj = nn.Linear(cfg.d_model, cfg.d_model, bias=cfg.bias)
|
| 98 |
+
self.q_norm = nn.RMSNorm(self.head_dim) if cfg.qk_norm else None
|
| 99 |
+
self.k_norm = nn.RMSNorm(self.head_dim) if cfg.qk_norm else None
|
| 100 |
+
self.rope = nn.RoPE(self.head_dim, base=cfg.rope_base)
|
| 101 |
+
self.attention_impl = cfg.attention_impl
|
| 102 |
+
|
| 103 |
+
def __call__(
|
| 104 |
+
self,
|
| 105 |
+
x: mx.array,
|
| 106 |
+
cache: Optional[Tuple[mx.array, mx.array]] = None,
|
| 107 |
+
) -> Tuple[mx.array, Tuple[mx.array, mx.array]]:
|
| 108 |
+
bsz, seqlen, d_model = x.shape
|
| 109 |
+
qkv = self.qkv_proj(x)
|
| 110 |
+
q, k, v = mx.split(qkv, [self.q_dim, self.q_dim + self.kv_dim], axis=-1)
|
| 111 |
+
|
| 112 |
+
def split_heads(t: mx.array, n_heads: int) -> mx.array:
|
| 113 |
+
t = t.reshape(bsz, seqlen, n_heads, self.head_dim)
|
| 114 |
+
return t.transpose(0, 2, 1, 3)
|
| 115 |
+
|
| 116 |
+
q = split_heads(q, self.n_heads)
|
| 117 |
+
k = split_heads(k, self.n_kv_heads)
|
| 118 |
+
v = split_heads(v, self.n_kv_heads)
|
| 119 |
+
if self.q_norm is not None:
|
| 120 |
+
q = self.q_norm(q)
|
| 121 |
+
k = self.k_norm(k)
|
| 122 |
+
|
| 123 |
+
cache_offset = 0
|
| 124 |
+
if cache is not None and cache[0] is not None:
|
| 125 |
+
cache_offset = int(cache[0].shape[2])
|
| 126 |
+
q = self.rope(q, offset=cache_offset)
|
| 127 |
+
k = self.rope(k, offset=cache_offset)
|
| 128 |
+
|
| 129 |
+
if cache is not None:
|
| 130 |
+
k_cache, v_cache = cache
|
| 131 |
+
if k_cache is not None and v_cache is not None:
|
| 132 |
+
k = mx.concatenate([k_cache, k], axis=2)
|
| 133 |
+
v = mx.concatenate([v_cache, v], axis=2)
|
| 134 |
+
|
| 135 |
+
q_len = q.shape[2]
|
| 136 |
+
k_len = k.shape[2]
|
| 137 |
+
if q_len > self.max_seq_len or k_len > self.max_seq_len:
|
| 138 |
+
raise ValueError(
|
| 139 |
+
f"Sequence length {q_len}/{k_len} exceeds max_seq_len={self.max_seq_len}"
|
| 140 |
+
)
|
| 141 |
+
scale = 1.0 / math.sqrt(self.head_dim)
|
| 142 |
+
# Cache compact KV heads, not the expanded heads used by vanilla GQA.
|
| 143 |
+
next_cache = (k, v)
|
| 144 |
+
if self.attention_impl == "fast":
|
| 145 |
+
attn = mx.fast.scaled_dot_product_attention(
|
| 146 |
+
q,
|
| 147 |
+
k,
|
| 148 |
+
v,
|
| 149 |
+
scale=scale,
|
| 150 |
+
mask="causal",
|
| 151 |
+
)
|
| 152 |
+
else:
|
| 153 |
+
repeats = self.n_heads // self.n_kv_heads
|
| 154 |
+
if repeats > 1:
|
| 155 |
+
k = mx.repeat(k, repeats, axis=1)
|
| 156 |
+
v = mx.repeat(v, repeats, axis=1)
|
| 157 |
+
full_mask = nn.MultiHeadAttention.create_additive_causal_mask(k_len)
|
| 158 |
+
mask = full_mask[k_len - q_len : k_len, :k_len]
|
| 159 |
+
mask = mx.expand_dims(mx.expand_dims(mask, axis=0), axis=0).astype(q.dtype)
|
| 160 |
+
scores = mx.matmul(q, k.transpose(0, 1, 3, 2)) * scale
|
| 161 |
+
scores = scores + mask
|
| 162 |
+
probs = mx.softmax(scores.astype(mx.float32), axis=-1).astype(v.dtype)
|
| 163 |
+
attn = mx.matmul(probs, v)
|
| 164 |
+
out = attn.transpose(0, 2, 1, 3).reshape(bsz, q_len, d_model)
|
| 165 |
+
out = self.proj(out)
|
| 166 |
+
return out, next_cache
|
| 167 |
+
|
| 168 |
+
|
| 169 |
+
class FeedForward(nn.Module):
|
| 170 |
+
def __init__(self, cfg: TransformerConfig):
|
| 171 |
+
super().__init__()
|
| 172 |
+
# SwiGLU uses three projections, so 2/3 keeps parameter count comparable
|
| 173 |
+
# to a conventional 4x two-projection MLP.
|
| 174 |
+
hidden_dim = int((2.0 / 3.0) * cfg.d_model * cfg.mlp_ratio)
|
| 175 |
+
hidden_dim = cfg.mlp_multiple_of * math.ceil(hidden_dim / cfg.mlp_multiple_of)
|
| 176 |
+
self.hidden_dim = hidden_dim
|
| 177 |
+
self.ffn_impl = cfg.ffn_impl
|
| 178 |
+
self.gate_up = nn.Linear(cfg.d_model, 2 * hidden_dim, bias=cfg.bias)
|
| 179 |
+
self.down = nn.Linear(hidden_dim, cfg.d_model, bias=cfg.bias)
|
| 180 |
+
|
| 181 |
+
def __call__(self, x: mx.array) -> mx.array:
|
| 182 |
+
gate_up = self.gate_up(x)
|
| 183 |
+
if self.ffn_impl == "packed-metal":
|
| 184 |
+
try:
|
| 185 |
+
from .fast_swiglu import packed_swiglu
|
| 186 |
+
except ImportError:
|
| 187 |
+
from fast_swiglu import packed_swiglu
|
| 188 |
+
return self.down(packed_swiglu(gate_up))
|
| 189 |
+
gate, up = mx.split(gate_up, [self.hidden_dim], axis=-1)
|
| 190 |
+
return self.down(nn.silu(gate) * up)
|
| 191 |
+
|
| 192 |
+
|
| 193 |
+
class TransformerBlock(nn.Module):
|
| 194 |
+
def __init__(self, cfg: TransformerConfig):
|
| 195 |
+
super().__init__()
|
| 196 |
+
self.norm1 = nn.RMSNorm(cfg.d_model)
|
| 197 |
+
self.attn = CausalSelfAttention(cfg)
|
| 198 |
+
self.norm2 = nn.RMSNorm(cfg.d_model)
|
| 199 |
+
self.ffn = FeedForward(cfg)
|
| 200 |
+
|
| 201 |
+
def __call__(
|
| 202 |
+
self,
|
| 203 |
+
x: mx.array,
|
| 204 |
+
cache: Optional[Tuple[mx.array, mx.array]] = None,
|
| 205 |
+
) -> Tuple[mx.array, Tuple[mx.array, mx.array]]:
|
| 206 |
+
attn_out, new_cache = self.attn(self.norm1(x), cache=cache)
|
| 207 |
+
x = x + attn_out
|
| 208 |
+
x = x + self.ffn(self.norm2(x))
|
| 209 |
+
return x, new_cache
|
| 210 |
+
|
| 211 |
+
|
| 212 |
+
class TransformerLM(nn.Module):
|
| 213 |
+
def __init__(self, cfg: TransformerConfig):
|
| 214 |
+
super().__init__()
|
| 215 |
+
self.cfg = cfg
|
| 216 |
+
self.embed = nn.Embedding(cfg.vocab_size, cfg.d_model)
|
| 217 |
+
self.blocks = [TransformerBlock(cfg) for _ in range(cfg.n_layers)]
|
| 218 |
+
# MLX >= 0.32.2 supplies the memory-reduced Metal RMSNorm backward
|
| 219 |
+
# for every nn.RMSNorm here, including block and Q/K norms. Keep the
|
| 220 |
+
# native primitive so compilation/autodiff select that implementation.
|
| 221 |
+
self.norm = nn.RMSNorm(cfg.d_model)
|
| 222 |
+
|
| 223 |
+
def logits(
|
| 224 |
+
self,
|
| 225 |
+
input_ids: mx.array,
|
| 226 |
+
caches: Optional[List[Tuple[mx.array, mx.array]]] = None,
|
| 227 |
+
) -> Tuple[mx.array, List[Tuple[mx.array, mx.array]]]:
|
| 228 |
+
x = self.embed(input_ids)
|
| 229 |
+
if caches is None:
|
| 230 |
+
caches = [None] * len(self.blocks)
|
| 231 |
+
|
| 232 |
+
new_caches = []
|
| 233 |
+
for block, block_cache in zip(self.blocks, caches):
|
| 234 |
+
x, next_cache = block(x, cache=block_cache)
|
| 235 |
+
new_caches.append(next_cache)
|
| 236 |
+
|
| 237 |
+
x = self.norm(x)
|
| 238 |
+
weight = self.embed.weight
|
| 239 |
+
logits = mx.matmul(x, weight.transpose(1, 0))
|
| 240 |
+
return logits, new_caches
|
| 241 |
+
|
| 242 |
+
def __call__(
|
| 243 |
+
self,
|
| 244 |
+
input_ids: mx.array,
|
| 245 |
+
targets: Optional[mx.array] = None,
|
| 246 |
+
ignore_index: int = -100,
|
| 247 |
+
) -> dict:
|
| 248 |
+
logits, _ = self.logits(input_ids, caches=None)
|
| 249 |
+
out = {"logits": logits}
|
| 250 |
+
if targets is None:
|
| 251 |
+
return out
|
| 252 |
+
|
| 253 |
+
loss_logits = logits.astype(mx.float32) if self.cfg.loss_dtype == "float32" else logits
|
| 254 |
+
mask = targets != ignore_index
|
| 255 |
+
safe_targets = mx.where(mask, targets, mx.zeros_like(targets))
|
| 256 |
+
if self.cfg.ce_impl == "metal":
|
| 257 |
+
try:
|
| 258 |
+
from .fast_loss import cross_entropy
|
| 259 |
+
except ImportError:
|
| 260 |
+
from fast_loss import cross_entropy
|
| 261 |
+
per_token = cross_entropy(logits, safe_targets)
|
| 262 |
+
else:
|
| 263 |
+
per_token = losses.cross_entropy(loss_logits, safe_targets, reduction="none")
|
| 264 |
+
mask = mask.astype(per_token.dtype)
|
| 265 |
+
denom = mx.maximum(mask.sum(), mx.array(1.0, dtype=per_token.dtype))
|
| 266 |
+
loss = (per_token * mask).sum() / denom
|
| 267 |
+
out["loss"] = loss
|
| 268 |
+
out["token_loss"] = per_token
|
| 269 |
+
return out
|
| 270 |
+
|
| 271 |
+
def step(
|
| 272 |
+
self,
|
| 273 |
+
token_ids: mx.array,
|
| 274 |
+
caches: Optional[List[Tuple[mx.array, mx.array]]] = None,
|
| 275 |
+
) -> Tuple[mx.array, List[Tuple[mx.array, mx.array]]]:
|
| 276 |
+
# token_ids shape: [B, 1]
|
| 277 |
+
logits, new_caches = self.logits(token_ids, caches=caches)
|
| 278 |
+
return logits[:, -1, :], new_caches
|
native_tokenizer.py
ADDED
|
@@ -0,0 +1,55 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
"""Own vocabulary, explicit structural IDs, verified frozen artifact."""
|
| 2 |
+
|
| 3 |
+
from pathlib import Path
|
| 4 |
+
from native_utils import file_sha256, read_json
|
| 5 |
+
|
| 6 |
+
SPECIALS = ["<|pad|>", "<|doc_end|>", "<|turn_start|>", "<|turn_end|>"]
|
| 7 |
+
FIXTURES = ["A plant uses sunlight to make sugars.", " leading and trailing spaces \n\n",
|
| 8 |
+
"\tif x:\n\t\treturn x + 1\n", "caf\u00e9, \u03c0, \u4e2d\u6587, \U0001f680; e\u0301",
|
| 9 |
+
"17 * 6 = 102; x**2 + y**2 = z**2", '{"items": [1, 2]}', "a\r\nb\r\n", "",
|
| 10 |
+
"Print " + " and ".join(SPECIALS) + " literally."]
|
| 11 |
+
|
| 12 |
+
|
| 13 |
+
class Tokenizer:
|
| 14 |
+
def __init__(self, directory):
|
| 15 |
+
from tokenizers import Tokenizer as Backend
|
| 16 |
+
directory = Path(directory)
|
| 17 |
+
self.manifest = read_json(directory / "manifest.json")
|
| 18 |
+
if self.manifest["format"] != "sml-v2-tokenizer-v1":
|
| 19 |
+
raise ValueError("Not a v2 tokenizer")
|
| 20 |
+
if not {"tokenizer.json", "tokenizer_config.json", "corpus.json"} <= self.manifest["sha256"].keys():
|
| 21 |
+
raise ValueError("Incomplete tokenizer integrity manifest")
|
| 22 |
+
if self.manifest["special_ids"] != dict(pad=0, eos=1, turn_start=2, turn_end=3):
|
| 23 |
+
raise ValueError("Structural token metadata changed")
|
| 24 |
+
for name, digest in self.manifest["sha256"].items():
|
| 25 |
+
if Path(name).name != name or file_sha256(directory / name) != digest:
|
| 26 |
+
raise ValueError(f"Tokenizer integrity failure: {name}")
|
| 27 |
+
self.backend = Backend.from_file(str(directory / "tokenizer.json"))
|
| 28 |
+
self.backend.no_padding()
|
| 29 |
+
self.backend.no_truncation()
|
| 30 |
+
self.backend.encode_special_tokens = True
|
| 31 |
+
self.fingerprint = file_sha256(directory / "manifest.json")
|
| 32 |
+
self.eos = self.manifest["special_ids"]["eos"]
|
| 33 |
+
self.pad = self.manifest["special_ids"]["pad"]
|
| 34 |
+
self.vocab_size = self.backend.get_vocab_size(with_added_tokens=True)
|
| 35 |
+
ids = set(self.backend.get_vocab().values())
|
| 36 |
+
if ids != set(range(self.manifest["vocab_size"])):
|
| 37 |
+
raise ValueError("Tokenizer IDs are not the declared dense vocabulary")
|
| 38 |
+
for i, token in enumerate(SPECIALS):
|
| 39 |
+
if self.backend.token_to_id(token) != i:
|
| 40 |
+
raise ValueError("Special token mapping changed")
|
| 41 |
+
|
| 42 |
+
def encode(self, text):
|
| 43 |
+
ids = self.backend.encode(text, add_special_tokens=False).ids
|
| 44 |
+
if any(i < len(SPECIALS) for i in ids):
|
| 45 |
+
raise ValueError("Ordinary text emitted structural token IDs")
|
| 46 |
+
return ids
|
| 47 |
+
|
| 48 |
+
def decode(self, ids):
|
| 49 |
+
return self.backend.decode([int(i) for i in ids], skip_special_tokens=False)
|
| 50 |
+
|
| 51 |
+
def assert_roundtrip(self, text):
|
| 52 |
+
ids = self.encode(text)
|
| 53 |
+
if self.decode(ids) != text:
|
| 54 |
+
raise ValueError(f"Tokenizer round-trip failed: {text[:120]!r}")
|
| 55 |
+
return ids
|
native_utils.py
ADDED
|
@@ -0,0 +1,8 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
import hashlib,json
|
| 2 |
+
from pathlib import Path
|
| 3 |
+
def read_json(p):return json.loads(Path(p).read_text())
|
| 4 |
+
def file_sha256(p):
|
| 5 |
+
h=hashlib.sha256()
|
| 6 |
+
with Path(p).open("rb") as f:
|
| 7 |
+
for b in iter(lambda:f.read(4*1024**2),b""):h.update(b)
|
| 8 |
+
return h.hexdigest()
|
pretraining-overview.svg
ADDED

|
pretraining-phase-b.svg
ADDED

|
pretraining-sources.svg
ADDED

|
report.json
ADDED
|
@@ -0,0 +1,38 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"fixtures_passed": 9,
|
| 3 |
+
"sources": {
|
| 4 |
+
"cosmopedia": {
|
| 5 |
+
"bytes": 402259,
|
| 6 |
+
"bytes_per_token": 5.061007523716062,
|
| 7 |
+
"documents": 103,
|
| 8 |
+
"roundtrip_failures": 0,
|
| 9 |
+
"seconds": 0.09366637503262609,
|
| 10 |
+
"tokens": 79482
|
| 11 |
+
},
|
| 12 |
+
"dclm": {
|
| 13 |
+
"bytes": 1001509,
|
| 14 |
+
"bytes_per_token": 4.453209483494593,
|
| 15 |
+
"documents": 165,
|
| 16 |
+
"roundtrip_failures": 0,
|
| 17 |
+
"seconds": 0.26016941701527685,
|
| 18 |
+
"tokens": 224896
|
| 19 |
+
},
|
| 20 |
+
"web": {
|
| 21 |
+
"bytes": 2205062,
|
| 22 |
+
"bytes_per_token": 4.625467253451697,
|
| 23 |
+
"documents": 559,
|
| 24 |
+
"roundtrip_failures": 0,
|
| 25 |
+
"seconds": 0.5487007499905303,
|
| 26 |
+
"tokens": 476722
|
| 27 |
+
},
|
| 28 |
+
"wiki": {
|
| 29 |
+
"bytes": 401775,
|
| 30 |
+
"bytes_per_token": 4.059276397546905,
|
| 31 |
+
"documents": 143,
|
| 32 |
+
"roundtrip_failures": 0,
|
| 33 |
+
"seconds": 0.10723229206632823,
|
| 34 |
+
"tokens": 98977
|
| 35 |
+
}
|
| 36 |
+
},
|
| 37 |
+
"vocab_size": 32000
|
| 38 |
+
}
|
requirements.txt
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
mlx==0.32.2
|
| 2 |
+
mlx-metal==0.32.2
|
| 3 |
+
tokenizers==0.22.2
|
tokenizer.json
ADDED
|
The diff for this file is too large to render.
See raw diff
|
|
|
tokenizer_config.json
ADDED
|
@@ -0,0 +1,8 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"add_bos_token": false,
|
| 3 |
+
"add_eos_token": false,
|
| 4 |
+
"clean_up_tokenization_spaces": false,
|
| 5 |
+
"eos_token": "<|doc_end|>",
|
| 6 |
+
"pad_token": "<|pad|>",
|
| 7 |
+
"tokenizer_class": "PreTrainedTokenizerFast"
|
| 8 |
+
}
|